
Any crew working with spoken audio hits the identical wall with generic speech-to-text. Assume contact-center calls, all-hands conferences, podcasts, depositions, and broadcast media. These workloads want two issues that customary transcription will get incorrect. First, timestamps land on the utterance stage, off by a number of seconds. Second, there’s no dependable reply to “who stated what.” These gaps make transcripts arduous to go looking, caption, redact, or analyze at scale. A lacking speaker label breaks compliance overview, and an imprecise timestamp breaks a caption or a redaction.
WhisperX closes each gaps. It wraps OpenAI’s Whisper with batched inference, provides wav2vec2 compelled alignment for exact per-word timestamps, and provides speaker diarization to label who spoke. These capabilities map on to actual workloads. Contact facilities can measure discuss time, verify script adherence, and run sentiment evaluation, whereas groups flip conferences into searchable notes. Media and e-learning groups generate correct captions (in SubRip Subtitle (SRT) and Internet Video Textual content Tracks (VTT) format) for big content material libraries. Time-sensitive makes use of get textual content the second somebody speaks. In regulated fields like healthcare, authorized, and finance, speaker-labeled transcripts help audits and authorized discovery.
The AWS WhisperX Deep Studying Container (DLC) packages all of this right into a GPU-ready picture. You deploy it to an Amazon SageMaker AI real-time or asynchronous endpoint with out constructing a customized picture. On this publish, we present deploy each endpoint sorts and when to decide on every. We additionally cowl the manufacturing particulars that matter: the GPU AMI pin, scaling, Amazon Easy Storage Service (Amazon S3) setup, and value controls. This publish is a part of a multimodal collection showcasing specialised AWS DLCs. The collection spans three AWS DLCs throughout 4 use circumstances: (1) vLLM-Omni for text-to-speech, (2) vLLM-Omni for picture and video, (3) WhisperX for speech-to-text (this publish), and (4) llama.cpp.
What’s WhisperX, and what workloads it unlocks
Whisper is a well-liked open supply computerized speech recognition (ASR) mannequin household from OpenAI that transcribes spoken audio into textual content precisely throughout many languages. It focuses on high-quality transcription and produces timestamps on the phrase or section stage. WhisperX is an open supply undertaking that builds on Whisper and extends it for manufacturing workloads. It provides per-word timestamps, speaker labels, and quicker transcription, three capabilities that collectively flip uncooked audio into structured, analyzable transcripts.
Why a purpose-built Deep Studying Container
The AWS WhisperX DLC is a maintained, GPU-ready picture that already incorporates Whisper, the alignment fashions, and the diarization weights, with no Hugging Face token required. It follows the usual Amazon SageMaker AI serving contract, so that you deploy it like another mannequin.
- Serving contract: The container serves on port
8080and exposesPOST /invocationsfor inference andGET /pingfor well being checks. - Request format: The endpoint expects
multipart/form-data, with the audio because thefilehalf plus optionally available string fields akin tolanguage,diarize, andresponse_format. Amazon SageMaker AI passes theContentTypeheader (together with the multipart boundary) by means of to the container unchanged. - Output codecs:
json,verbose_json,srt, andvtt, so the identical endpoint feeds analytics pipelines and video editors alike.
Selecting between real-time and asynchronous endpoints
Amazon SageMaker AI helps each real-time and asynchronous endpoints, so you possibly can serve the identical WhisperX DLC by means of both sample. The choice often comes all the way down to clip size and interactivity. For lengthy audio, use the asynchronous endpoint: it’s the really useful path when transcription, alignment, and diarization want extra time to run. Reserve the real-time endpoint for brief, interactive clips that end inside the Amazon SageMaker AI 60-second response cap.
| Dimension | Actual-time endpoint | Asynchronous endpoint |
| Greatest for | Quick, interactive clips | Lengthy audio, high-volume batch |
| Latency | Synchronous, should end < 60s | Submit-and-poll. No response cap |
| Invocation | InvokeEndpoint (inline physique) | InvokeEndpointAsync (S3 reference) |
| I/O | Physique in request / response | Enter + output in Amazon S3 |
| Scaling | Add situations (one request/container) | Add situations. Can autoscale to zero |
| Price profile | Payments whereas endpoint is up | Scale-to-zero when idle saves price |
Resolution structure
Each patterns share the identical container contract. Amazon SageMaker AI forwards every request to the WhisperX DLC on port 8080. The actual-time sample is synchronous, and the asynchronous sample brokers enter and output by means of Amazon S3. Occasion choice (ml.g4dn.xlarge for price, ml.g5.2xlarge for headroom) and the required GPU AMI pin apply to each, and also you scale throughput by including situations slightly than concurrency. The request/response sequence for every endpoint sort is proven in its walkthrough part.
Conditions
- An AWS account and an Amazon SageMaker AI execution function that may
create_model,create_endpoint, and (for asynchronous inference) learn and write S3. - GPU service quota to your endpoint occasion sort (for instance,
ml.g4dn.xlargeorml.g5.2xlarge). - The WhisperX DLC picture URI from Amazon Elastic Container Registry (Amazon ECR) (for instance,
763104351884.dkr.ecr.<area>.amazonaws.com/whisperx:3.8.6-cu128-amzn2023-sagemaker). - For asynchronous inference, an S3 bucket whose title incorporates “sagemaker.” The default
AmazonSageMakerFullAccesscoverage grants S3 entry solely to such buckets.
A whole, runnable JupyterLab pocket book that walks by means of these steps finish to finish is out there within the AWS Samples repository. You possibly can run it in Amazon SageMaker AI Studio towards your individual audio.
Walkthrough: Actual-time endpoint
The actual-time endpoint returns the transcript in the identical synchronous name. Use it for brief clips that comfortably end inside the 60-second cap. Determine 1 is a sequence diagram that traces a single real-time request finish to finish, from the consumer name by means of in-container transcription to the inline transcript.
Determine 1: Actual-time endpoint synchronous InvokeEndpoint circulation, in-container transcription, and inline transcript inside the 60-second cap
Studying the sequence finish to finish: the consumer assembles a multipart/form-data physique (the audio because the file half plus fields akin to language, diarize, and word-level timestamp granularity) and calls InvokeEndpoint. Amazon SageMaker AI forwards the request to the container on port 8080, passing the ContentType and its multipart boundary by means of unchanged. Contained in the container, WhisperX runs voice-activity detection and batched Whisper transcription, wav2vec2 compelled alignment for per-word timestamps, and speaker diarization to label who’s talking. It then serializes the outcome. The runtime returns the transcript (segments, phrases with timestamps, and speaker labels) inline to the consumer, which should full inside the Amazon SageMaker AI 60-second response cap.
Create the mannequin and endpoint config
Register the WhisperX DLC as a mannequin, the place IMAGE_URI factors on the WhisperX DLC in Amazon ECR, then create an endpoint config. On each GPU variant, you need to set InferenceAmiVersion to al2-ami-sagemaker-inference-gpu-3-1. With out this pin, the endpoint fails to start out with a zero-log CannotStartContainerError. Enable a beneficiant startup health-check timeout as a result of the weights load lazily.
Invoke with diarization and phrase timestamps
Construct a multipart/form-data physique with the audio because the file half and fields akin to language=en, diarize=true, and response_format=verbose_json. The response incorporates segments, per-word timestamps, and speaker labels.
The instance GitHub repository makes use of a public-domain recording of the air visitors management (ATC) communications from US Airways Flight 1549, the 2009 “Miracle on the Hudson” emergency touchdown. It’s an actual multi-party radio alternate with background noise, radio compression, and speedy callsign and frequency readouts. These circumstances make it a powerful check of transcription accuracy, word-level timestamps, and speaker diarization. The total roughly 3-minute recording is distributed to the asynchronous endpoint, and a 40-second section to the real-time endpoint.
Working this towards a 40-second section of the supply audio returns the next diarized, word-timed transcript:
Walkthrough: Asynchronous endpoint
The asynchronous endpoint removes the 60-second cap and is the really useful path for lengthy audio. Enter and output are brokered by means of Amazon S3, and also you ballot for the outcome. Determine 2 is a sequence diagram that traces the complete asynchronous lifecycle, from the S3 add and InvokeEndpointAsync name by means of container processing to the S3 output and failure paths.
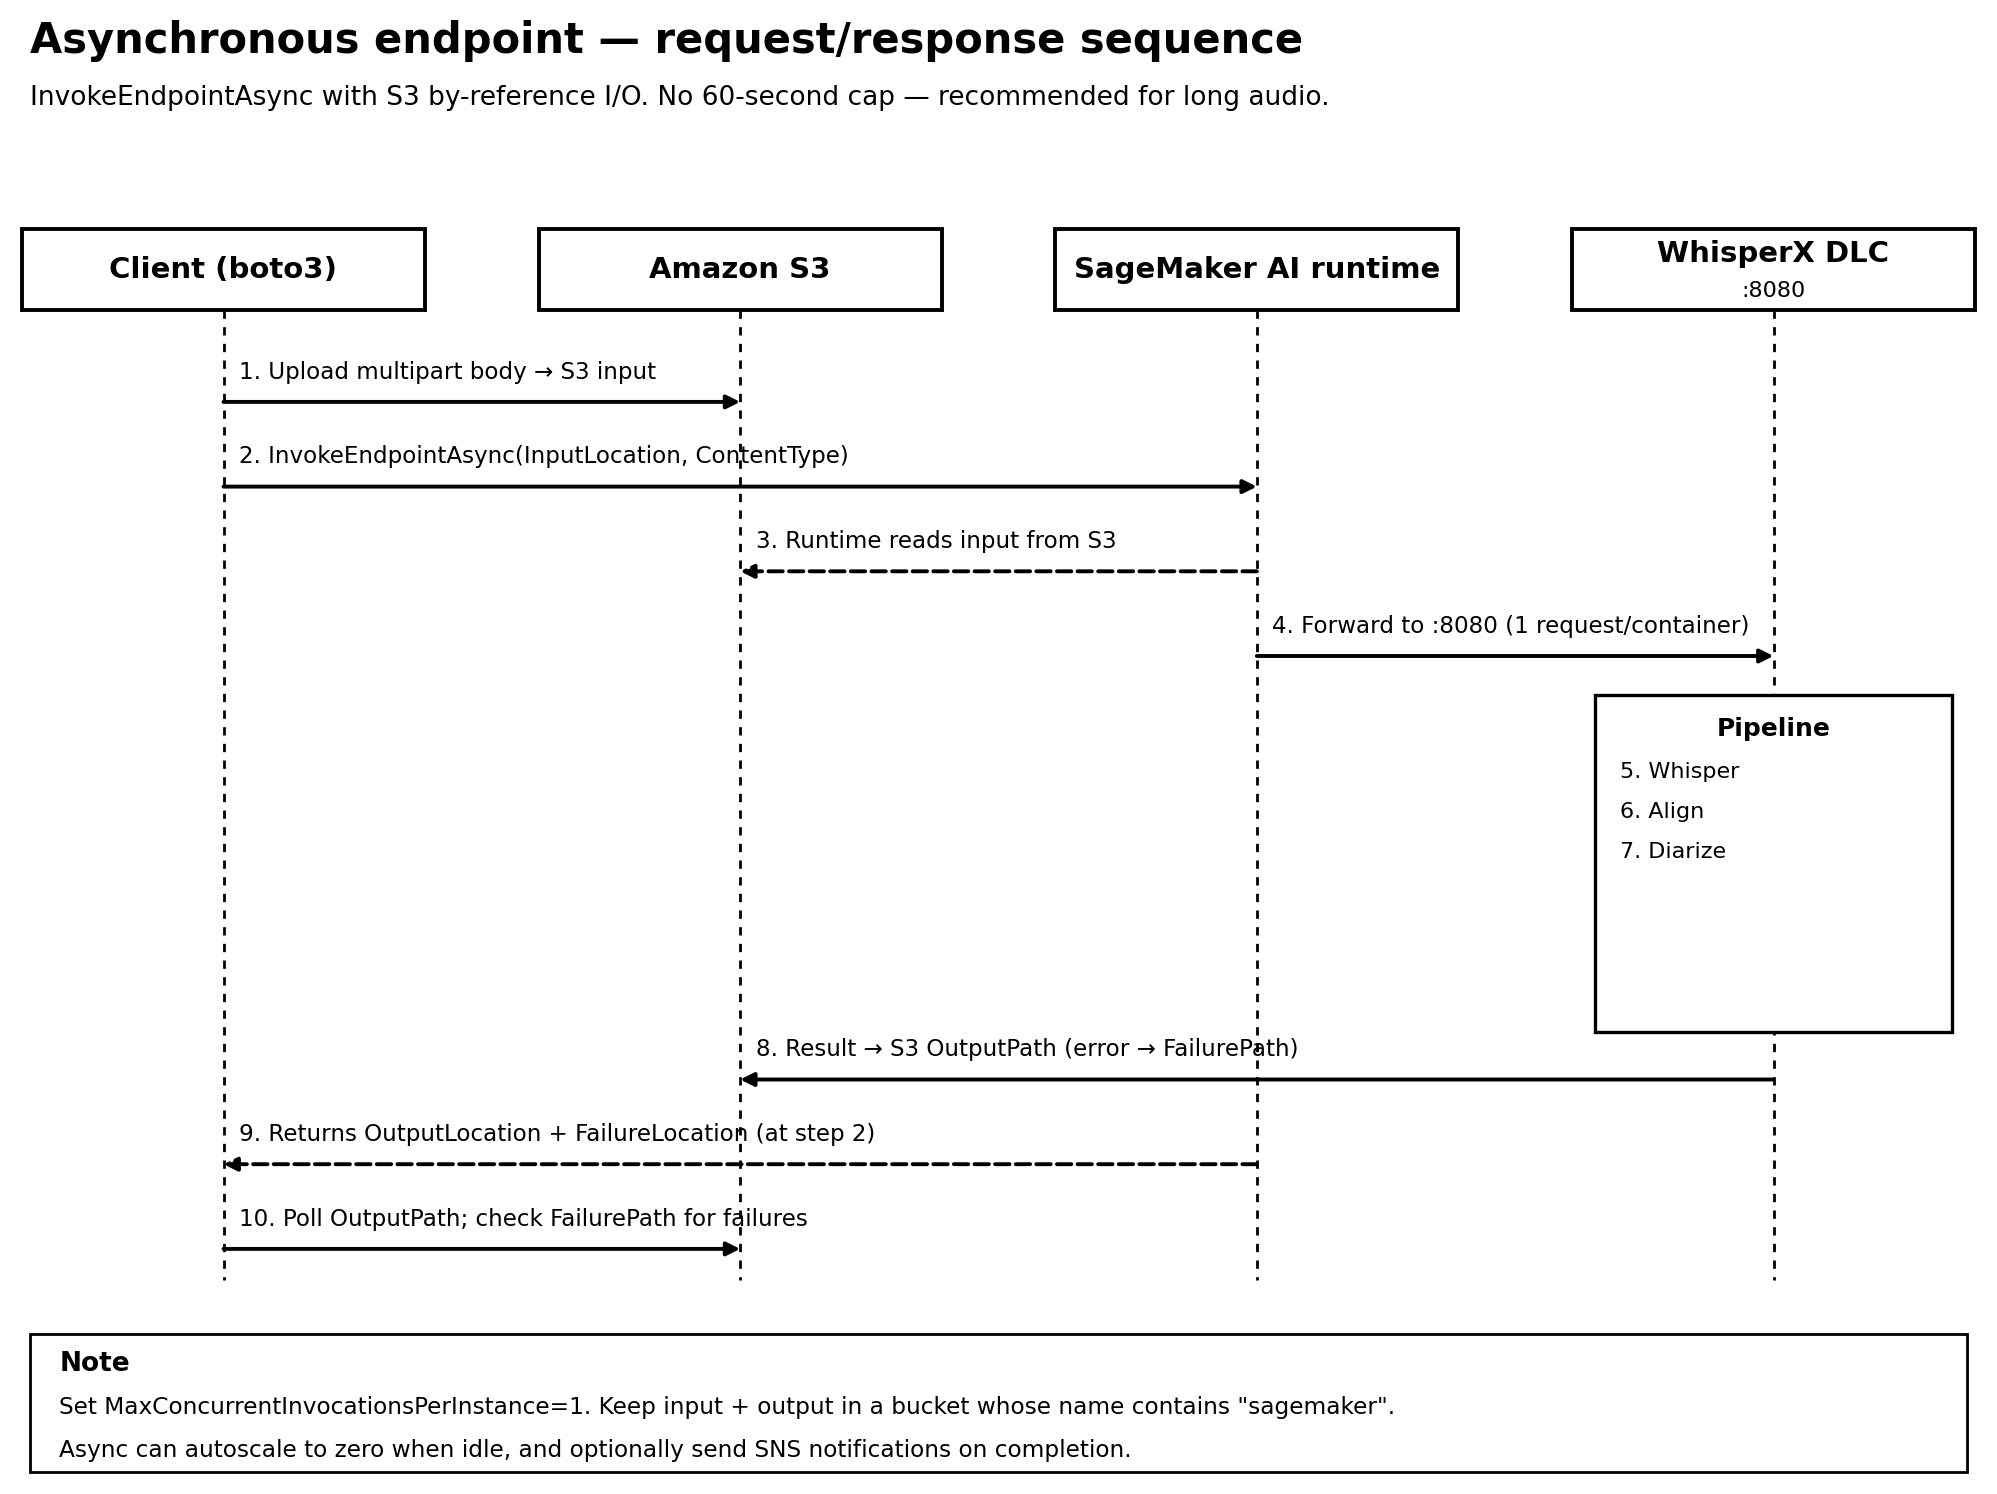
Determine 2: Asynchronous endpoint S3 by-reference InvokeEndpointAsync circulation, single-worker processing, and outcomes by means of the S3 output and failure paths
Studying the sequence finish to finish: the consumer uploads the multipart physique to Amazon S3 and calls InvokeEndpointAsync with the thing’s InputLocation. It receives an OutputLocation and FailureLocation instantly slightly than ready for the transcript. Amazon SageMaker AI reads the enter from Amazon S3 and forwards it to the container on port 8080. There, the identical voice-activity detection, batched transcription, forced-alignment, and diarization pipeline runs, one request per container. On success, the container writes the transcript to the S3 output path, or an error doc to the failure path. The consumer polls the output path for the outcome and checks the failure path, so a failed job surfaces an error as a substitute of looping indefinitely. As a result of work is brokered by means of Amazon S3, this path isn’t certain by the 60-second cap and fits lengthy audio.
Create the asynchronous endpoint config
The one structural distinction from the real-time endpoint is the endpoint config: it provides an AsyncInferenceConfig with an S3 OutputPath and S3FailurePath. Set MaxConcurrentInvocationsPerInstance=1 to match the container’s single-worker restrict, and hold the identical InferenceAmiVersion pin. IMAGE_URI is similar WhisperX DLC used for the real-time endpoint.
The remainder of the workflow is an identical to the real-time walkthrough. Constructing the multipart/form-data request (the build_multipart helper and transcription fields) is unchanged. You submit it with invoke_endpoint_async by S3 reference as a substitute of invoke_endpoint, then learn the transcript from the OutputLocation and verify the FailureLocation. Cleanup can also be the identical.
Submitting the complete roughly 3-minute recording to the asynchronous endpoint returns the next transcript (first and final 5 traces proven):
Cleansing up
A GPU endpoint payments repeatedly till you delete it. When you find yourself finished, delete the endpoint, endpoint config, and mannequin for each endpoints, and take away any S3 enter and output artifacts you not want.
Greatest practices and manufacturing concerns
- Pin the GPU AMI – At all times set
InferenceAmiVersion=al2-ami-sagemaker-inference-gpu-3-1on GPU variants. The default host AMI ships drivers that fail to start out this CUDA 12.8 picture. - Scale by situations, not concurrency – Inference is serialized to at least one request per container. Set
MaxConcurrentInvocationsPerInstance=1on asynchronous endpoints and add situations or containers for throughput. - Autoscale asynchronous endpoints to zero – For bursty batch workloads, scale the asynchronous endpoint to zero situations when idle to chop price, and use Amazon Easy Notification Service (Amazon SNS) completion notifications as a substitute of tight polling.
- Proper-size the GPU, and use occasion swimming pools for availability – Use
ml.g4dn.xlarge(T4) for price orml.g5.2xlarge(A10G) for headroom. To keep away from insufficient-capacity errors, record as much as 5 occasion sorts in an Amazon SageMaker AI occasion pool. It provisions the highest-priority sort first and falls again routinely when capability is unavailable. - Safe the S3 artifacts – Activate S3 Block Public Entry, default SSE-S3 or SSE-KMS encryption, and BucketOwnerEnforced possession on the asynchronous bucket. Scope the execution function to particular buckets and keys.
- Deal with personally identifiable info (PII) responsibly – Transcripts of calls and conferences may include delicate information, so encrypt artifacts, limit entry, and apply redaction downstream utilizing the word-level timestamps.
- Observe and retry – Monitor with Amazon CloudWatch, alarm on failures, and retry across the cold-start habits described earlier. For deeper GPU and inference visibility, activate the Amazon SageMaker AI detailed metrics and Insights dashboard on CloudWatch.
Conclusion
On this publish, we confirmed deploy the AWS WhisperX Deep Studying Container to Amazon SageMaker AI for word-level, speaker-labeled transcription. We used a real-time endpoint for brief interactive clips and an asynchronous endpoint for lengthy, high-volume audio. We lined the manufacturing particulars that matter most: the required GPU AMI pin, single-request-per-container scaling, S3 bucket naming, and value controls.
To go additional, discover the WhisperX DLC deployment guide, overview Amazon SageMaker AI asynchronous inference, and check out the accompanying demo pocket book towards your individual audio. You too can discover the complete working instance within the AWS Samples GitHub repository.
Acknowledgements
The authors thank the AWS Deep Studying Containers and Amazon SageMaker AI groups for his or her technical overview and contributions to the pattern.
In regards to the authors