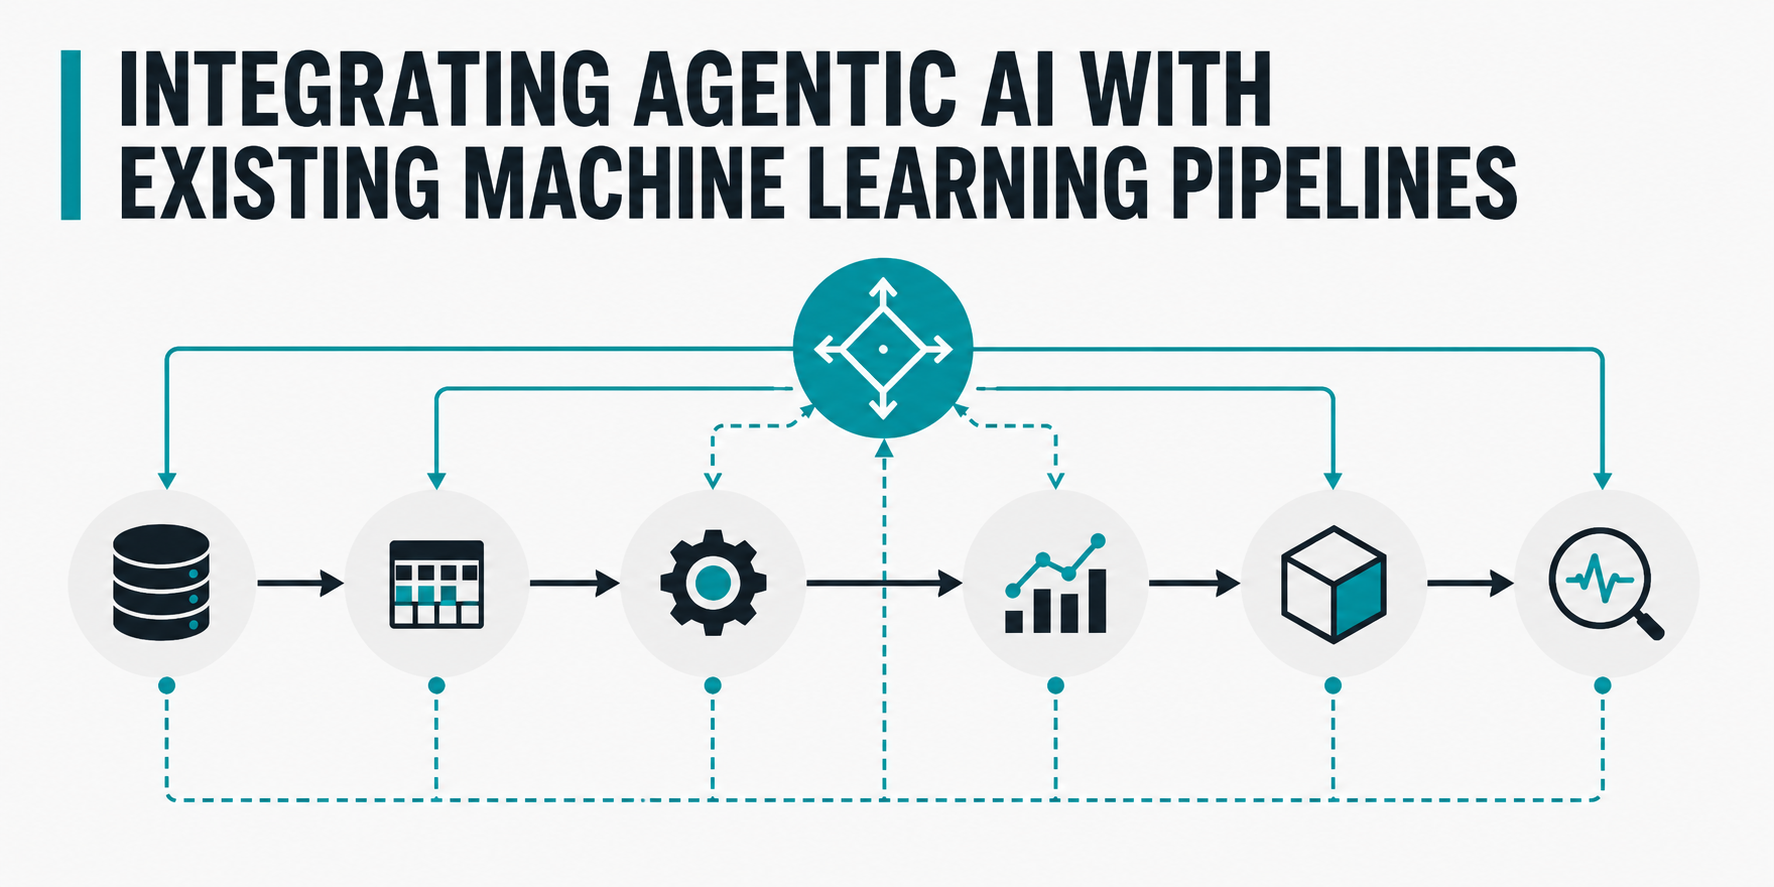

On this article, you’ll learn to mix a classical machine studying pipeline with an agentic AI system to construct a hybrid, autonomous buyer retention workflow.
Matters we’ll cowl embrace:
- generate an artificial dataset and practice a random forest classifier for buyer churn prediction utilizing scikit-learn.
- design an agentic AI system — full with instruments and an LLM-powered reasoning core — that interprets machine studying predictions and acts on them autonomously.
- wire the machine studying pipeline and the agent collectively right into a single, end-to-end runnable Python utility.
Introduction
Agentic AI and machine studying pipelines are removed from incompatible relating to constructing production-ready AI functions. In actual fact, embracing them as two sides of the identical coin has change into greater than a mere pattern: it constitutes a contemporary foundational structure sample that drives the shift from passive predictive analytics to autonomous decision-making and motion.
Conventional machine studying pipelines excel at sample recognition duties of various complexity, however they’re purely reactive of their base kind. In the meantime, agentic AI methods are all about proactivity: mixed with predictive machine studying fashions, they’ll construct on the insights yielded by such fashions to plan, use instruments, and tackle real-world use circumstances with little or no human steering.
On this hands-on article, we’ll present you bridge the hole between reactive machine studying fashions and proactive AI brokers. We’ll assemble a light-weight, free, runnable Python pipeline that:
- Predicts buyer churn primarily based on a classical machine studying mannequin constructed with scikit-learn.
- Fingers the obtained predictions over to an agent endowed with a state-of-the-art LLM to autonomously cause and execute completely different buyer retention methods.
Conditions
All the coding tutorial could be run free of charge in Google Colab or an area Jupyter pocket book, offered you might have the mandatory libraries put in and imported.
If you’re utilizing Colab, on the time of writing, the one library you may must manually set up is Groq:
Be sure you additionally import the next:
|
import numpy as np from sklearn.ensemble import RandomForestClassifier from sklearn.model_selection import train_test_split from groq import Groq |
Since Groq — one among right this moment’s most succesful open-source LLM suppliers — requires an API key, you’ll want to register on their web site and create your personal API key here. You have to to include it in your pocket book or Google Colab account. The code under is designed to learn the API key from the “Secrets and techniques” part discovered on the left-hand sidebar in Google Colab: create a brand new secret variable there known as GROQ_API_KEY, and paste your precise Groq API key into the “worth” subject.
These directions will aid you inject the newly added API key into your program:
|
import os from google.colab import userdata
# Injecting the Colab secret into normal surroundings variables os.environ[“GROQ_API_KEY”] = userdata.get(‘GROQ_API_KEY’) |
Step-by-Step Information
As soon as the stipulations are arrange, we’ll begin constructing the classical machine studying pipeline — for buyer churn prediction — that may later be prolonged by incorporating agentic AI rules and instruments.
First, we’d like a prospects dataset to feed to our machine studying mannequin. For this instance, we’ll synthetically generate our personal dataset containing 500 prospects, every described by two predictor options plus a goal variable indicating whether or not the shopper is vulnerable to churn. The 2 enter options are the month-to-month buyer spend and the variety of assist tickets issued by the shopper: each are real-world predictors of a buyer’s willingness to stick with or abandon a model. Discover that the code makes use of numpy capabilities to introduce random noise, making the artificially generated knowledge look real looking:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 |
# ========================================== # 0. SYNTHETIC DATASET GENERATION # ==========================================
# Producing a practical dataset of 500 prospects described by two enter options np.random.seed(42) n_samples = 500
# Function 1: Month-to-month buyer’s spend (uniformly distributed between $10 and $150) spend = np.random.uniform(10, 150, n_samples)
# Function 2: Help tickets issued by buyer (Poisson distribution, averaging 1.5 tickets) tickets = np.random.poisson(lam=1.5, measurement=n_samples)
# Generate goal variable / Binary class (Churn): # Churn threat will increase with extra tickets and reduces with increased spend base_churn_risk = (tickets * 0.15) + np.the place(spend < 30, 0.3, 0) – np.the place(spend > 100, 0.2, 0) # Add some random noise to make the dataset real looking base_churn_risk += np.random.regular(0, 0.1, n_samples) base_churn_risk = np.clip(base_churn_risk, 0, 1) # 0 = Retain, 1 = Churn (Threshold at 0.5) y = (base_churn_risk > 0.5).astype(int) X = np.column_stack((spend, tickets)) |
Subsequent, we construct a easy, classical machine studying pipeline by splitting the dataset into coaching and take a look at units and coaching a random forest ensemble classifier. We confirm the mannequin’s efficiency on the take a look at set earlier than persevering with:
|
# ========================================== # 1. CLASSIC ML PIPELINE (Predictive -> Classification) # ==========================================
# Prepare/Take a look at Cut up X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)
# Prepare the predictive classifier on the bigger dataset print(f“Coaching ML Mannequin on {len(X_train)} data…”) ml_model = RandomForestClassifier(n_estimators=50, max_depth=5, random_state=42) ml_model.match(X_train, y_train) print(f“Mannequin Accuracy on Take a look at Set: {ml_model.rating(X_test, y_test)*100:.1f}%n”) |
Prediction outcomes on the take a look at knowledge:
|
Coaching ML Mannequin on 400 data... Mannequin Accuracy on Take a look at Set: 91.0% |
A 91% accuracy is sweet sufficient for our functions, so we’ll proceed to incorporating our agent into the loop.
The primary side we’ll create for our agent is its “palms” — in different phrases, the instruments the agent can use to carry out particular actions on account of its reasoning and decision-making. Whereas in real-world settings these instruments sometimes work together with exterior parts, providers, and databases through API calls or comparable protocols, we mock two customer-oriented actions right here utilizing easy printed messages:
|
# ========================================== # 2. THE TOOLS (Agentic “Fingers”) # ========================================== # These are two capabilities the agent can be allowed to set off in the true world. # Actions are mocked and emulated by utilizing parameterized print messages def send_discount(customer_id): return f“[Action Executed] Despatched a 20% low cost code to Buyer {customer_id}.”
def schedule_support_call(customer_id): return f“[Action Executed] Escalated Buyer {customer_id} to a human agent for a check-in.” |
Whereas having the agent name its accessible instruments is the way it exerts impression as soon as deployed, it’s the cognition core — answerable for the agent’s reasoning and execution — the place the precise “intelligence” takes place:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 |
# ========================================== # 3. THE AGENT’S COGNITION (Reasoning & Execution) # ========================================== class RetentionAgent: def __init__(self): print(“Connecting to Groq API (Llama 3.3 70B)…n”) # Mechanically picks up the GROQ_API_KEY surroundings variable self.shopper = Groq() self.model_name = “llama-3.3-70b-versatile”
def _reason(self, immediate): # We use the usual Chat Completions API chat_completion = self.shopper.chat.completions.create( messages=[ { “role”: “system”, “content”: “You are an autonomous customer retention agent. You must output exactly one word: either ‘call’ or ‘discount’.” }, { “role”: “user”, “content”: prompt } ], mannequin=self.model_name, temperature=0.0, # Zero temperature ensures deterministic, logical decisions ) return chat_completion.decisions[0].message.content material.strip().decrease()
def process_customer(self, customer_id, options): print(f“— Processing Buyer {customer_id} —“)
# Step A: Getting the prediction from the traditional ML pipeline churn_prob = ml_model.predict_proba([features])[0][1] spend_val, tickets_val = options print(f“ML Prediction: {churn_prob*100:.0f}% churn threat.”)
# Step B: Autonomous Guardrail – solely act if the danger is excessive if churn_prob < 0.5: return “Agent Determination: No motion wanted. Buyer is low threat.n”
# Step C: Agentic Reasoning (Context Injection) # A 70B mannequin from Groq handles this logic effortlessly, together with the easy math reasoning wanted on this use case. immediate = ( f“Buyer {customer_id} has a {churn_prob*100:.0f}% threat of churning. “ f“They at the moment spend ${spend_val:.2f} per 30 days and have filed {int(tickets_val)} assist tickets. “ f“Enterprise Rule: If a buyer has filed greater than 2 assist tickets, they’re annoyed and wish a human ‘name’. “ f“In any other case, they’re simply price-sensitive and we must always ship a ‘low cost’.” )
# The LLM “thinks” and decides on the software choice = self._reason(immediate) print(f“Agent Reasoning output: ‘{choice}'”)
# Step D: Device Execution (Routing to a selected agent’s “hand”) if “name” in choice: consequence = schedule_support_call(customer_id) elif “low cost” in choice: consequence = send_discount(customer_id) else: consequence = f“[Action Failed] Agent returned an unrecognized software title: {choice}”
return consequence + “n” |
Let’s briefly break down the code above:
- Utilizing object-oriented programming, we created a specialised agent for our goal area known as
RetentionAgent. Importantly, this agent is linked to an LLM that acts as its internal cognition engine. We particularly selected a Llama 3.3 mannequin served by Groq, which is light-weight sufficient to run feasibly in a pocket book however highly effective sufficient to reliably carry out the meant reasoning job. - The agent’s
_reason()technique prepares the immediate for the LLM and configures mannequin settings applicable to our state of affairs, comparable to setting temperature to zero for deterministic output. - The agent’s
process_customer()technique bridges the hole with the machine studying mannequin constructed earlier. It fetches buyer churn predictions and constructs a immediate that injects the prediction alongside different buyer knowledge, asking the LLM what motion to take. The core choice logic that triggers agent motion is dealt with right here.
As soon as all of the constructing blocks are in place, it’s time to run our hybrid ML-agentic pipeline. We instantiate the agent and take a look at it on three instance prospects. Pay shut consideration to the profiles of those three prospects and cross-reference them with the LLM immediate outlined contained in the agent’s reasoning technique:
|
# ========================================== # 4. RUN THE PIPELINE # ========================================== agent = RetentionAgent()
# Testing the pipeline on just a few particular profiles to see the routing in motion
# Take a look at Case 1: Average spend, low tickets -> Mannequin may predict low/average threat. # If excessive threat, agent ought to decide low cost. print(agent.process_customer(customer_id=101, options=[25.50, 1]))
# Take a look at Case 2: Average spend, excessive tickets -> Mannequin predicts excessive threat, Agent ought to schedule name. print(agent.process_customer(customer_id=102, options=[45.00, 5]))
# Take a look at Case 3: Excessive spend, zero tickets -> Mannequin predicts very low threat, Agent bypasses. print(agent.process_customer(customer_id=103, options=[140.00, 0])) |
Output:
|
Connecting to Groq API (Llama 3.3 70B)...
—– Processing Buyer 101 —– ML Prediction: 57% churn threat. Agent Reasoning output: ‘low cost’ [Action Executed] Despatched a 20% low cost code to Buyer 101.
—– Processing Buyer 102 —– ML Prediction: 88% churn threat. Agent Reasoning output: ‘name’ [Action Executed] Escalated Buyer 102 to a human agent for a test–in.
—– Processing Buyer 103 —– ML Prediction: 0% churn threat. Agent Determination: No motion wanted. Buyer is low threat. |
The outcomes align with what one would anticipate. That mentioned, bear in mind that the mannequin alternative issues: we chosen an LLM that’s well-suited to this job and set its temperature to zero to forestall non-deterministic habits, which is undesirable on this context. In the event you select a unique mannequin, your outcomes could fluctuate.
Closing Remarks
On this article, we constructed a hybrid pipeline step-by-step that mixes classical machine studying for buyer churn prediction with an agentic AI answer able to turning these predictions into an autonomous reasoning, decision-making, and motion workflow. This demonstrates bridge the hole between two key pillars of recent AI options in company and organizational environments.