
Once you deploy a mannequin to a GPU endpoint, the smallest unit of GPU you’ll be able to request is one entire accelerator.
This constraint can price you twice. First, you’ll be able to’t host extra fashions on an occasion than it has accelerators. An ml.p4d.24xlarge has eight A100s, so it holds eight fashions, whether or not each wants 40 GB or 14 GB. Second, and fewer apparent, it makes each deployment come right down to a alternative of which full GPU to deploy to. As your concurrency and immediate lengths develop, a full GPU on an older occasion stops being sufficient, however a full GPU on a more recent one is greater than your mannequin can use. You find yourself both under-served or paying for functionality you by no means attain.
Immediately, Amazon SageMaker Inference helps GPU partitioning, which makes use of NVIDIA Multi-Instance GPU (MIG) to divide a bodily GPU into impartial partitions. Every partition receives a set share of the GPU’s compute items and a devoted block of its reminiscence, with isolation enforced in {hardware}. That adjustments each constraints: you’ll be able to place a unique mannequin in every partition, and you’ll select a fraction of a more recent accelerator as a substitute of an entire certainly one of both technology.
This publish covers each. The primary half is the direct profit: deploy extra fashions than you’ve GPUs, with isolation between them. The second is the one prospects ask about when the query turns to price: how the granularity of partitioning helps you decide the right-sized unit, and what we measured after we did.
One factor to know earlier than you learn additional: GPU partitioning works on endpoints that use inference elements, the assemble you utilize to deploy a number of fashions to at least one endpoint and set the compute every mannequin will get. Partitioning builds straight on it. A partition is a useful resource a element asks for, in the identical place it already asks for CPU and reminiscence. For those who haven’t used inference elements, this publish introduces them. Single-model endpoints, serverless endpoints, and heterogeneous occasion swimming pools can’t be partitioned.
What prospects do at present, and why every choice falls quick
If in case you have extra fashions than accelerators, you’ve had three decisions.
Run fewer, bigger endpoints and batch more durable – This raises utilization, however solely when the fashions are interchangeable. A portfolio of fine-tuned variants or per-tenant fashions isn’t.
Use multi-model endpoints – These load and unload fashions from a shared GPU on demand, which inserts sparse, bursty visitors. However fashions share the machine with out isolation, so a heavy request for one mannequin impacts the others. A mannequin that isn’t loaded additionally pays a load penalty on first use.
Transfer to self-managed Kubernetes – That is the place prospects who want actual GPU partitioning have gone. MIG works there, however you tackle driver versioning, partition configuration, a tool plugin, scheduling, and protecting all of it constant throughout a fleet. That’s numerous work for a {hardware} functionality your situations have already got.
Why MIG
NVIDIA Multi-Occasion GPU (MIG) splits one GPU into as many as seven situations, relying on the GPU. Every occasion has its personal compute, cache, reminiscence and reminiscence bandwidth. As a result of the break up is in {hardware} quite than software program, you get ensures that different sharing strategies can’t give:
- Predictable latency – Every partition has devoted reminiscence bandwidth, so one mannequin’s visitors spike doesn’t present up in one other mannequin’s p99.
- Fault isolation – A crash or reminiscence error stays inside its partition as a substitute of taking down each mannequin on the GPU.
- Proper-sized capability – Small and mid-sized fashions get a slice that matches them as a substitute of an entire GPU. You’ll be able to combine slice sizes on one machine.
- No chilly begins – Each mannequin retains its personal partition and stays loaded, with no load penalty and no eviction.
- Tenant isolation – Reminiscence safety between partitions is enforced in {hardware}, which makes safety and compliance critiques less complicated.
- Dependable planning and chargeback – A partition performs the identical means no matter its neighbors, so load assessments predict manufacturing. GPU price additionally maps cleanly to a mannequin, workforce or tenant.
Partitioning has boundaries price figuring out up entrance. The utmost variety of partitions depends upon the accelerator and by no means exceeds seven. MIG itself solely permits a format to alter whereas its partitions are idle, and on SageMaker AI which means selecting a format if you create the endpoint. A mannequin that wants multiple GPU nonetheless wants entire gadgets. Inside these boundaries, you get the isolation of separate GPUs with out dedicating one to every mannequin.
Partitioning with out the platform work
Till now, getting MIG meant working the Kubernetes stack your self. GPU partitioning on Amazon SageMaker AI removes that step: you decide a partition profile in your mannequin, and SageMaker AI handles GPU configuration, placement and scaling. You get hardware-isolated GPU sharing on a managed endpoint, with out having to run the platform beneath it.
Salesforce has been a part of this work from the beginning, serving to outline the necessities and validating the preliminary implementation.
“NVIDIA MIG partitions a single GPU into a number of remoted situations, every with devoted compute and reminiscence assets. Salesforce sees this as an essential functionality as a result of many inference workloads don’t require a complete GPU. MIG would permit us to consolidate workloads safely, considerably enhance GPU utilization, cut back inference prices, and keep predictable efficiency and robust isolation.
This functionality would assist us scale AI Inference extra effectively throughout totally different use instances. Salesforce has helped outline necessities, validated the preliminary answer. We are actually making ready to validate the answer with consultant manufacturing workload and show sturdy buyer demand with AWS. We consider MIG assist would ship significant technical and enterprise worth for enterprise prospects.”
— Richard Chang, Software program Engineering Architect, Salesforce
The way it works
GPU partitioning provides two optionally available fields to API calls you already make. There aren’t any new API operations, no new useful resource varieties, and no new AWS Identification and Entry Administration (IAM) actions, and an endpoint that omits each fields behaves precisely because it does at present.
AcceleratorPartitionLayouts goes on a manufacturing variant in CreateEndpointConfig and declares how every accelerator is split:
An A100 has seven compute slices to divide. The previous format makes use of all seven, so every of the eight A100s on the p4d occasion carries three partitions and the endpoint gives 24, eight of every kind.
The carve applies uniformly. One format entry describes how one accelerator is split, and each accelerator on each occasion within the variant is split the identical means. The record isn’t positional, so an entry doesn’t map to a particular GPU.
AcceleratorPartitionType goes on an inference element and selects which partition the mannequin runs on:
Every element copy occupies one partition of the requested kind. With eight partitions of every kind on the occasion, elevating CopyCount locations extra copies on free partitions. That is helpful for a small mannequin serving excessive concurrency, the place a single course of leaves the GPU ready on requests.
NumberOfAcceleratorDevicesRequired is at all times 1 right here. With a partition kind set it means one partition quite than one accelerator. NumberOfCpuCoresRequired and MinMemoryRequiredInMb nonetheless describe host CPU and host reminiscence, as a result of GPU reminiscence comes from the partition kind.
Invocation doesn’t change. InvokeEndpoint addresses a mannequin by inference element title, and the partition it occupies by no means seems within the request.
Partitioning occurs whereas the endpoint is provisioned. When it reaches InService each accelerator is carved and the partitions are empty, which is a legitimate state as elements land on them afterward. In our testing, carving accelerators added roughly 17 seconds to provisioning. The remainder of the time is the same old occasion launch and container pull.
Partition profiles by GPU
The profiles out there to you’re a property of the GPU, so begin by discovering out which GPU your occasion kind carries and look it up in NVIDIA’s supported MIG profiles, which is the authority on the total profile set and the mixtures legitimate on one machine.
| Occasion household | Accelerator | GPU reminiscence | Granularity (compute / reminiscence) | Out there partition profiles | Max partitions per GPU |
| P4d | NVIDIA A100 | 40 GB | 7 / 8 | mig-1g.5gb, mig-1g.10gb (see driver observe), mig-2g.10gb, mig-3g.20gb, mig-4g.20gb, mig-7g.40gb | 7 |
| P5 | NVIDIA H100 | 80 GB | 7 / 8 | mig-1g.10gb, mig-1g.20gb, mig-2g.20gb, mig-3g.40gb, mig-4g.40gb, mig-7g.80gb | 7 |
| G7 | NVIDIA RTX PRO 4500 Blackwell | 32 GB | 2 / 2 | mig-1g.16gb, mig-2g.32gb | 2 |
| G7e | NVIDIA RTX PRO 6000 Blackwell Server Version | 96 GB | 4 / 4 | mig-1g.24gb, mig-2g.48gb, mig-4g.96gb | 4 |
Learn the profile title as compute items adopted by GPU reminiscence: mig-3g.40gb takes three compute items and 40 GB. The granularity column is what limits a format. An A100 and an H100 divide into sevenths on compute and eighths on reminiscence, whereas G7 divides into halves and G7e into quarters. Profile names differ between GPUs even the place the slice counts match, so don’t carry a format from one occasion household to a different with out checking it towards this desk.
Inside these limits you’ve actual alternative. On a P4d or P5 you’ll be able to carve seven of the smallest profile, or two 3g partitions, or the 4g plus 2g plus 1g format used within the earlier instance, or take the entire machine as one. On a G7e you’ll be able to take 4 of the smallest, or two 1g beside a 2g, or two 2g, or one entire machine. On a G7, both two partitions or one.
The 3g profile is the one to know, as a result of its two dimensions don’t match: it takes three of the seven compute items however 4 of the eight reminiscence items. Two of them fill the GPU and nothing else will match beside them.
The high-level rule: Each profile in your format should be one your GPU provides, and the compute and reminiscence items your profiles add as much as should not exceed what one machine gives. Each are checked if you create the endpoint configuration, and both one failing is a rejection quite than a fallback to a complete accelerator.
Driver observe for P4d: mig-1g.10gb requires an R525 or newer NVIDIA driver, and the default P4d picture ships 470.256.02. Request it on the default picture and the carve fails with out an error naming the profile. Set InferenceAmiVersion to al2023-ami-sagemaker-inference-gpu-4-1 on the manufacturing variant to get a picture on the 580 driver line, which provides it.
Selecting a format in your workload
Selecting properly is a separate query from selecting a format that’s merely accepted. A partition arms you compute and reminiscence in fastened proportions, and the 2 do totally different jobs throughout inference.
Compute items are what you want for prefill. Prefill reads the immediate and builds its illustration. That is the compute-heavy section, and it scales with the streaming multiprocessors, and so the TFLOPs, your partition holds. The longer your inputs and the extra prompts arriving without delay, the extra it governs how shortly you come a primary token.
Reminiscence items are what you want for decode and for capability. Producing tokens re-reads the mannequin weights on each step, so decode is bounded by reminiscence bandwidth quite than by math, and reminiscence additionally caps how a lot KV cache you’ll be able to maintain. That cap in flip units the context size you’ll be able to serve and what number of sequences you’ll be able to serve concurrently.
Virtually no actual workload workouts solely certainly one of these, so the aim isn’t to select a dimension however to decide on a mix that helps your use case. Select a profile whose proportions cowl your heaviest section whereas leaving the opposite adequately served. On the compute aspect, what issues is how lengthy your prompts are and what number of arrive without delay. On the reminiscence aspect, it’s your output size, your context window, and your concurrency.
Reminiscence is the better of the 2 to underestimate, as a result of a partition has to carry three issues and never simply the mannequin: the weights, which for an 8B mannequin at FP16 are about 16 GB. The KV cache, sized for the context size and the variety of concurrent sequences you plan to permit, which is the time period individuals pass over and the one which grows with visitors. And 1–2 GB of runtime overhead for the CUDA context and the serving course of. Add these up earlier than selecting a profile, as a result of a partition sized to the weights alone will load the mannequin after which fail beneath load, or quietly serve a a lot shorter context than you configured. For a concrete reference level, that very same 8B mannequin at FP16 comfortably serves an 8,000-token context on a 40 GB partition.
The place MIG provides probably the most worth
A portfolio of small and mid-size fashions – The direct case. High-quality-tuned variants, embedding fashions, rerankers, and classifiers that every go away most of an accelerator unused now share one.
Multi-tenant mannequin serving – Once you host a mannequin per buyer, MIG provides you a {hardware} boundary between them: a course of in a single partition can’t learn one other partition’s reminiscence or take its throughput. Scope the declare precisely, although. Fashions on the identical occasion nonetheless share host CPU, system reminiscence, storage, networking, and endpoint routing, so partitioning is an isolation mechanism for the GPU and never an entire tenancy boundary.
Multi-stage pipelines on one occasion – A transcription mannequin, a diarization mannequin, and a language mannequin, or an embedder, a reranker, and a generator. Every stage is a individually addressable element by itself partition, and a community hop between levels disappears.
A small mannequin within the request path – A security classifier or guardrail mannequin that has to run on each request however can not justify an accelerator, with predictable latency as a result of it isn’t time-slicing towards the principle mannequin.
Challengers and canaries – Run a candidate mannequin on a small partition beside the mannequin serving manufacturing visitors as a substitute of standing up a second endpoint.
Efficiency: A slice of a more recent GPU towards a complete older one
Along with bin-packing, the opposite profit you get is granularity on high-end GPUs: extra GPU choices to deploy a mannequin onto, and the selection of which one is yours. Each supported accelerator turns into a number of sizes quite than one, so the sensible means to consider it’s that every profile is a GPU choice in its personal proper, sitting alongside the entire accelerators you already select between. That issues most when you’re contemplating a bigger or newer occasion kind, as a result of shifting up stops being all-or-nothing: you’ll be able to take as a lot or as little of that larger GPU as your workload wants, at any of the sizes it publishes, as a substitute of paying for the entire accelerator.
To see whether or not that pays off, we in contrast one mig-3g.40gb partition of an H100 towards one entire, uncarved A100-40GB. The 2 have comparable GPU reminiscence, which makes it a clear solution to see how highly effective a slice of a extra superior occasion could be.
We used genai-bench to generate load, driving each endpoints from the identical consumer so the GPU is the one variable. Either side ran Llama-3.1-8B-Instruct on manufacturing SageMaker real-time endpoints, one mannequin reproduction every, with an equivalent container picture, tokenizer, and consumer configuration. Each had been invoked by means of the SageMaker AI native OpenAI-compatible route. We swept 5 visitors shapes, written D(enter tokens, output tokens) and starting from quick prompts to long-context summarization, every throughout a concurrency ladder from 2 to 512.
Determine 1: Mixture output tokens per second for one mig-3g.40gb partition of an H100 towards one full A100-40GB, throughout 5 visitors shapes and a concurrency ladder from 2 to 512
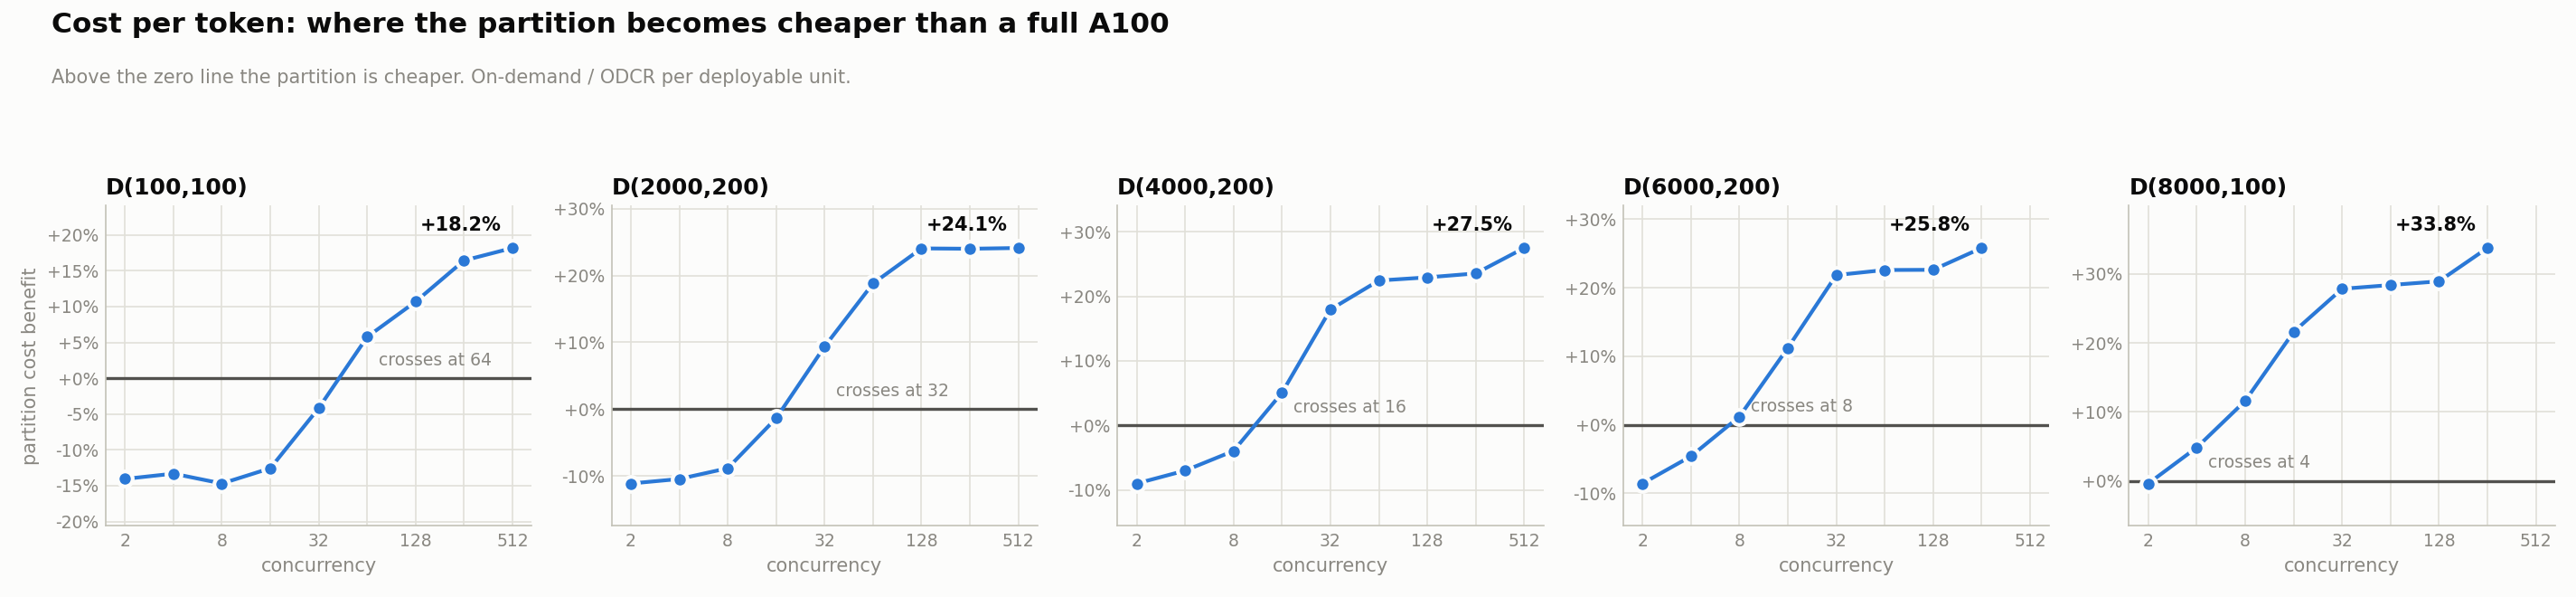
Determine 2: Partition price profit per million output tokens towards concurrency for a similar 5 visitors shapes
4 issues stand out.
- The partition is quicker in all places – It delivered extra output tokens per second in each state of affairs at each concurrency, by 53 % to 89 % on the load the place every state of affairs’s price profit is largest, and decrease inter-token latency in each one too, by 8.9 % to 42.1 %. The hole widens with load.
- Time to first token is decrease in each case, by 5.6 % to 47.5 %.
- On price it’s 18–34 % cheaper per million output tokens, above a crossover that strikes earlier as prompts lengthen. Concurrency 64 for 100-token prompts, 4 for 8,000-token prompts. Beneath the crossover the entire A100 is the cheaper unit. These costs are all on-demand, which on the time of study had been measured as $25.251286 per hour for an
ml.p4d.24xlargeand $63.296000 per hour for anml.p5.48xlargewithin the US West (Oregon) AWS Area. Purely for our personal evaluation, we derived the unit price by dividing the whole-instance price by the variety of items on it: 8 on the p4d, and 16 on the p5, the place our partition is half of a GPU. - On the high of the ladder on long-context visitors, the A100 stopped serving. On each the 6,000- and eight,000-token workloads it failed a 3rd to a half of its requests towards a serving-path deadline, whereas the partition failed none. That’s the reason these two panels finish sooner than the remainder.
Deal with this as a case-by-case comparability, not a verdict. The helpful psychological mannequin is to treat the out there GPU fractions as GPU varieties in their very own proper. Checklist them alongside entire accelerators, work out what your visitors really calls for of compute and of reminiscence, and examine them by yourself workload. For prime-concurrency, long-input visitors the partition received on each efficiency and price right here. For brief-input or low-concurrency workloads the entire A100 remained cheaper. Partitioning isn’t a one-size-fits-all reply. It provides you extra sizes to select from, so you’ll be able to decide the one that matches your workload.
What to know earlier than you decide to a format
Partitioning adjustments the form of an endpoint, and some properties are price understanding earlier than you design one.
A element’s partition kind is fastened for the lifetime of that element. Shifting a mannequin to a unique profile means creating a brand new element. Altering the endpoint’s carve means a brand new endpoint and a visitors migration, as a result of updating an endpoint configuration doesn’t re-carve hosts which can be already working. This makes partitioning a very good match for a steady portfolio and a poor one for a combination you reshuffle each day.
A requested profile has to exist within the endpoint’s format. There is no such thing as a fallback to a complete accelerator, so a element asking for a profile the variant didn’t declare is rejected.
Partitioning applies to real-time inference on inference element endpoints. Serverless endpoints and heterogeneous occasion swimming pools aren’t supported, and asynchronous invocation can not tackle an inference element, so async workloads are out of scope.
You’re billed for the total GPU occasion, as you’re at present. Partitioning raises how a lot of that occasion you should utilize. It doesn’t change its hourly value.
Lastly, a mannequin that genuinely wants a full accelerator, or multiple, ought to preserve having one. No partition spans accelerators.
Supported situations and Areas
GPU partitioning is out there on the P4d, P5, G7, and G7e occasion households. Assist is on the household degree, so smaller sizes inside a household are coated.
It’s out there within the following AWS Areas: US East (N. Virginia), US East (Ohio), US West (Oregon), Asia Pacific (Singapore), Asia Pacific (Tokyo), Europe (Frankfurt), and Europe (Eire).
Occasion availability varies by Area, so verify that your chosen occasion kind is obtainable in your Area and that you’ve got endpoint utilization quota for it.
Getting began
To partition a GPU endpoint, work out the reminiscence and compute every of your mannequin’s wants, decide the profiles that match, declare a format in your endpoint configuration, and deploy every mannequin as an inference element that requests a profile from that format. Nothing about the way you invoke your fashions adjustments.
For the API reference, the total profile tables for every occasion household, and a step-by-step walkthrough, see GPU partitioning within the Amazon SageMaker AI Developer Information.
To attempt it your self, run the GPU partitioning sample notebook, which deploys a number of fashions onto partitions of a single GPU endpoint.
The broader change is price protecting in thoughts as you intend capability. Each supported accelerator is now a number of sizes quite than one. Whether or not a partition of a more recent GPU or a complete accelerator of an older one is the fitting unit for a given mannequin is now not a query it’s essential reply by rounding up. It’s one you’ll be able to measure.
In regards to the authors