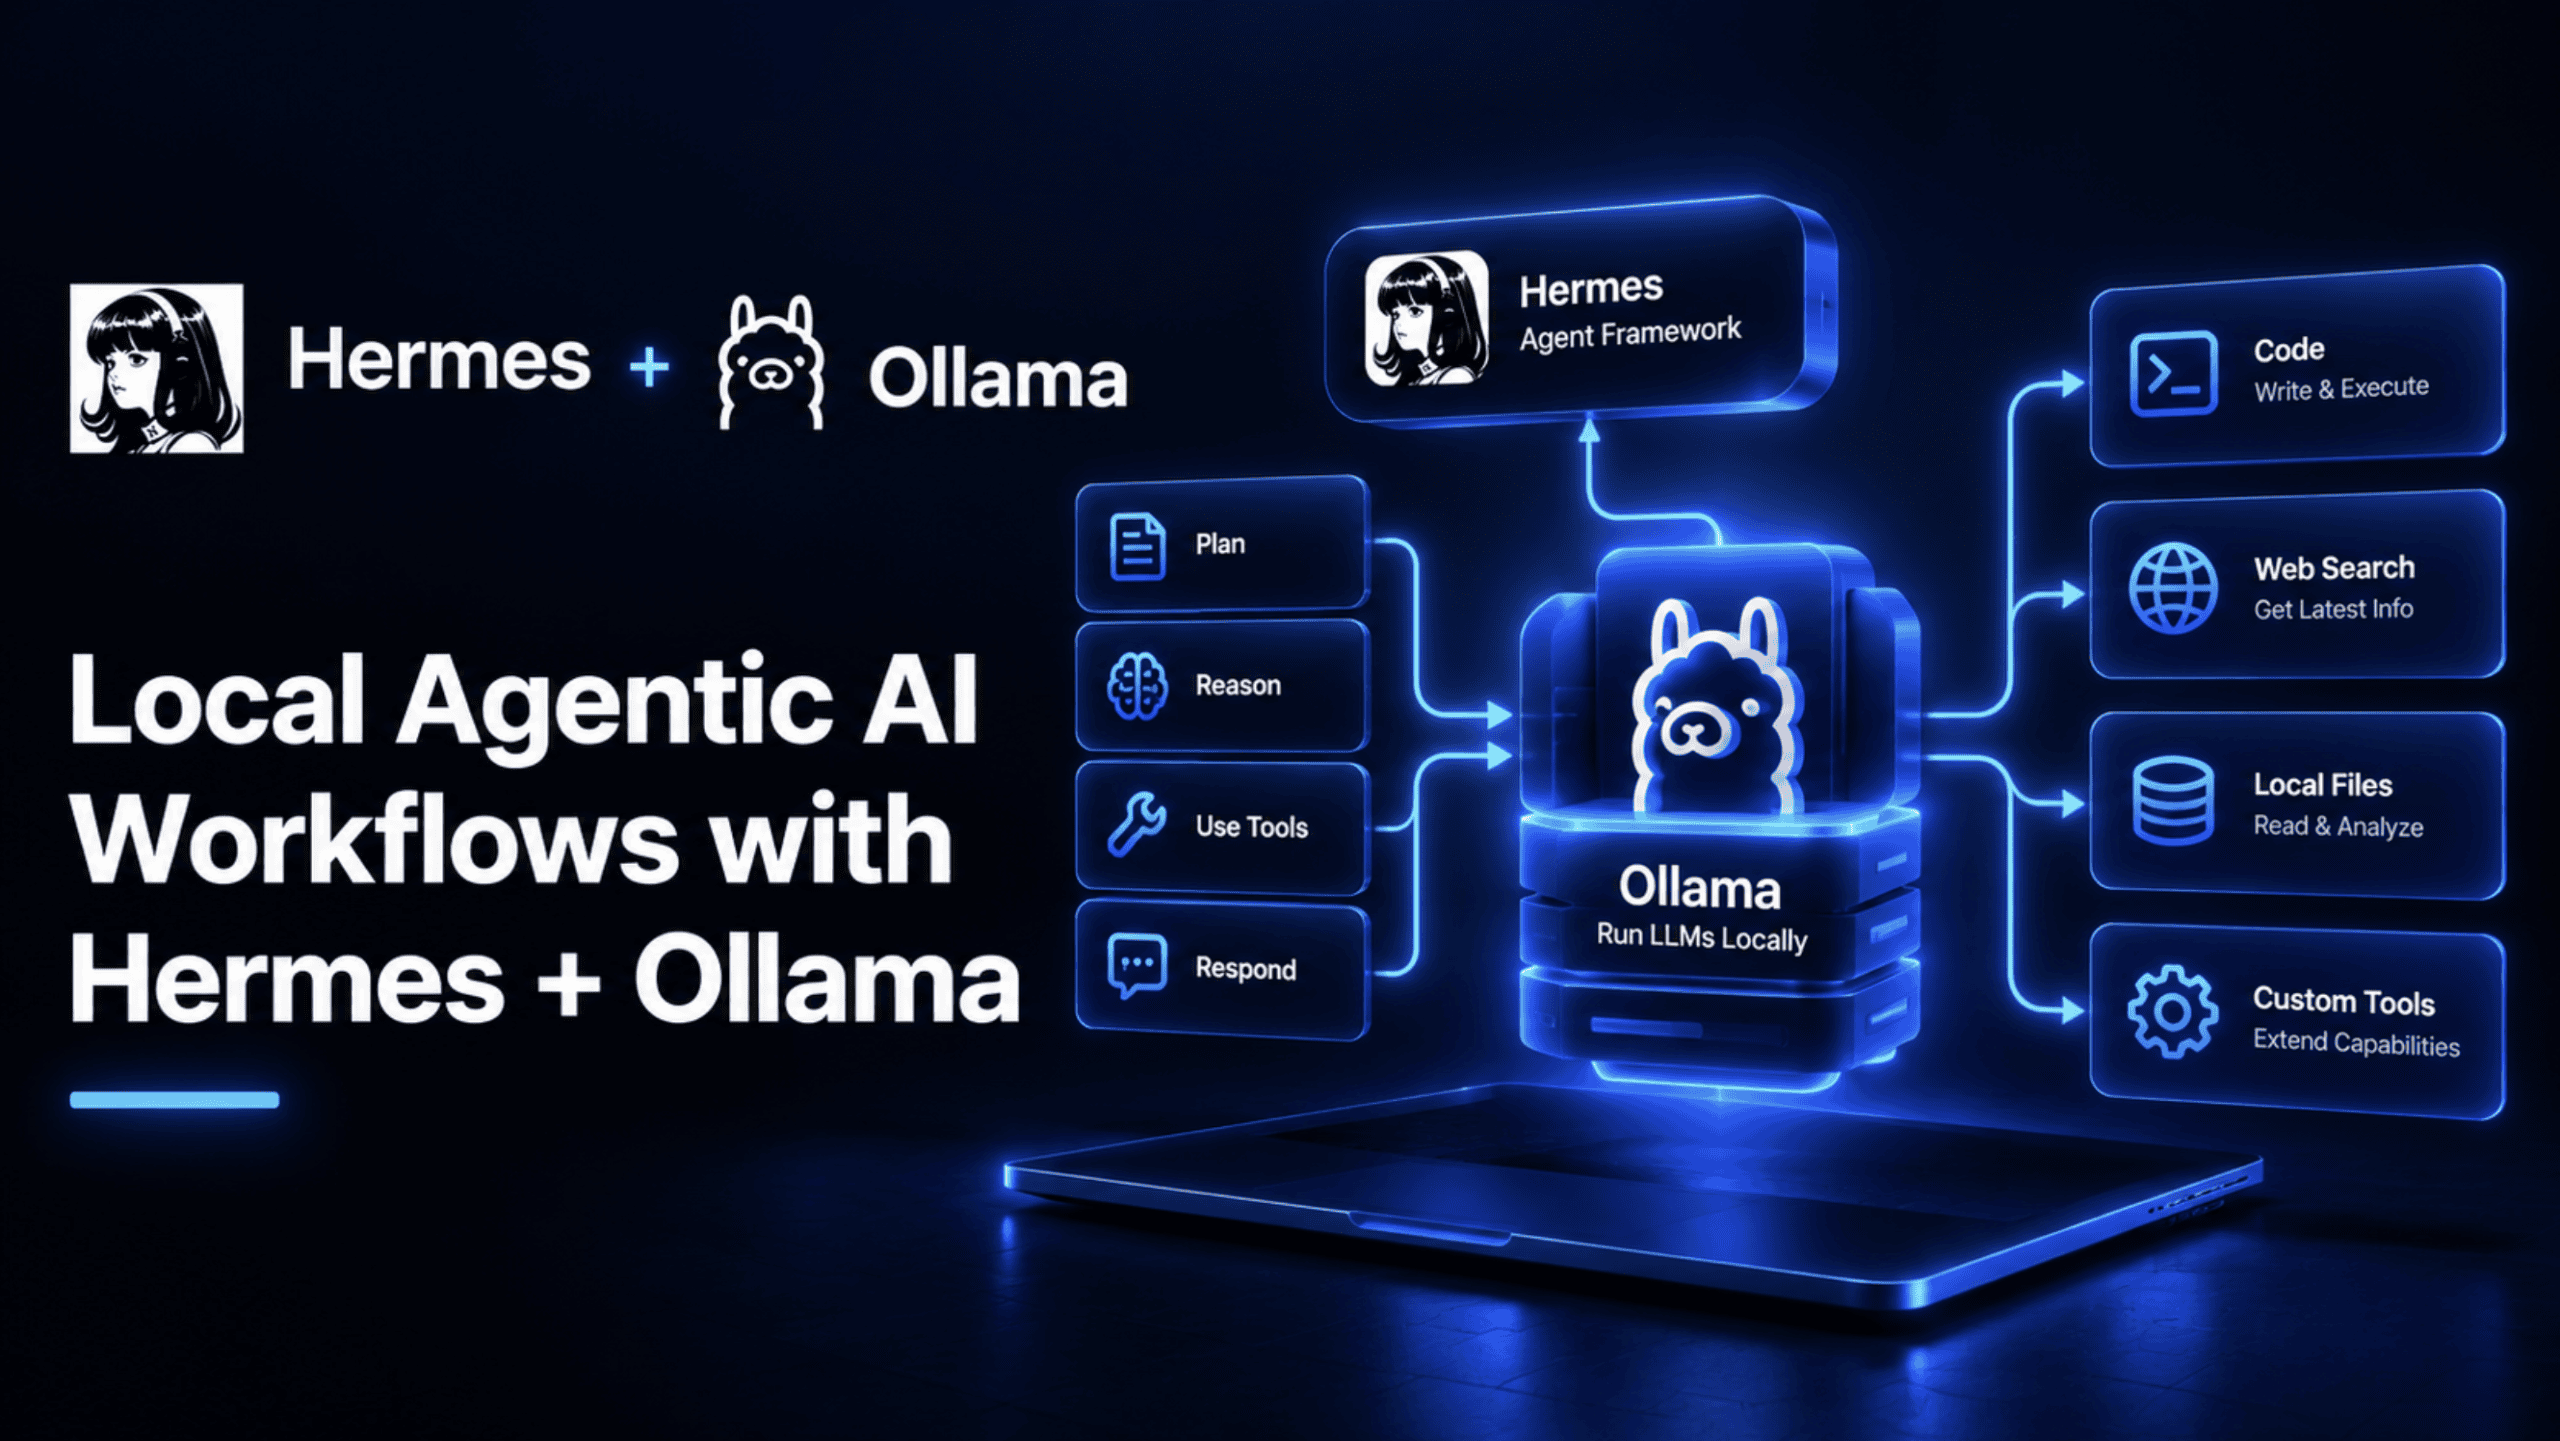

On this article, you’ll learn to construct a totally native, zero-cost agentic AI workflow utilizing Hermes Agent and Ollama, in order that your recordsdata, code, and conversations by no means depart your individual {hardware}.
Matters we’ll cowl embrace:
- The right way to set up Ollama, select the suitable native mannequin for agentic work, and confirm that the mannequin is responding accurately earlier than wiring the rest up.
- The right way to configure Hermes Agent to make use of your native Ollama endpoint, and methods to optimize context window measurement and mannequin loading for actual agentic duties.
- The right way to prolong the setup with a Telegram gateway for distant entry and a cloud fallback for questions the native mannequin can’t deal with effectively.
A typical coding session in opposition to a cloud AI API runs someplace between $0.60 and $0.80 relying on the supplier, and a heavier session can climb to $5 to $20, according to Nous Research’s own cost breakdown for agentic work. That provides up quick for a hobbyist, a scholar, or anybody operating frequent automation, and it comes with a second price that’s straightforward to miss: each file, each query, each line of code will get despatched to a 3rd social gathering’s servers.
This text builds the choice: a genuinely native, zero-cost agentic AI workflow utilizing Hermes Agent, an open-source AI agent from Nous Analysis, paired with Ollama for native mannequin serving.
What Is Hermes Agent?
Hermes Agent is an open-source AI agent built by Nous Research, launched beneath the MIT license and presently at model 0.21.1 as of this writing. It ships two methods: a local desktop app for macOS, Home windows, and Linux, and a terminal-first CLI you put in immediately. What separates it from a fundamental chat interface is real agentic functionality; it edits recordsdata, runs terminal instructions, browses the online, and might delegate work to remoted sub-agents with their very own conversations and instruments.
A couple of options matter particularly for this text. Persistent reminiscence means Hermes learns your initiatives over time and might auto-generate reusable abilities from the way it solved previous issues, reasonably than ranging from zero each session. Its messaging gateway connects the identical agent and the identical reminiscence to Telegram, Discord, Slack, WhatsApp, and electronic mail. And its sandboxing system helps 5 totally different isolation backends — native, Docker, SSH, Singularity, and Modal — so instructions it runs wouldn’t have to the touch your host system immediately for those who would reasonably they didn’t.
What Is Ollama?
Ollama is the layer beneath Hermes on this setup: a software that downloads, serves, and manages open-weight language fashions immediately by yourself {hardware}, exposing them by an area API that appears and behaves like an ordinary cloud LLM endpoint. That final element issues greater than it sounds: as a result of Ollama’s API is OpenAI-compatible at /v1/chat/completions, Hermes can speak to a mannequin operating completely in your laptop computer utilizing the very same integration path it might use for a cloud supplier like OpenAI or Anthropic — simply pointed at localhost as an alternative of the web.
The division of labor is clear: Ollama’s solely job is operating the mannequin and answering requests for it. Hermes’ job is being the precise agent — deciding when to name a software, enhancing a file, operating a command, looking the online, and deciphering what comes again. Neither one replaces the opposite, and this tutorial wants each.
What We’re Constructing
The concrete challenge for this text is a personal, zero-cost native assistant that may arrange and reply questions on an actual folder of recordsdata in your machine, search the online when a query genuinely wants present data, and — as soon as the core setup works — keep reachable out of your telephone through a Telegram bot if you find yourself away out of your desk. As a closing layer, it should have a cloud fallback configured so genuinely arduous questions nonetheless get answered effectively, whereas the opposite 90% of on a regular basis use prices nothing and by no means leaves your machine.
Each part from right here builds one actual piece of that challenge, within the order you’d really construct it.
What You Want
{Hardware} necessities scale with the mannequin you intend to run, and it’s value realizing each ends of the vary earlier than selecting.
| Element | Minimal | Really helpful |
|---|---|---|
| RAM | 8 GB (for 3B fashions) | 32+ GB (for 27B+ fashions) |
| Storage | 5 GB free | 30+ GB (for a number of fashions) |
| CPU | 4 cores | 8+ cores |
| GPU | Not required | NVIDIA GPU with 8+ GB VRAM |
CPU-only setups genuinely work; they’re simply slower. A 9B mannequin on a contemporary 8-core CPU runs at roughly 10 tokens per second, whereas a 31B mannequin on CPU drops to about 2 to five tokens per second, that means every response can take 30 to 120 seconds. That’s usable for a background assistant, much less nice for an interactive back-and-forth, which is value factoring into which mannequin you choose.
Set up Ollama and Pull a Mannequin
Set up Ollama with its official set up script:
|
curl –fsSL https://ollama.com/set up.sh | sh |
Verify it’s really operating:
|
ollama —model curl http://localhost:11434/api/tags # Ought to return {“fashions”:[]} |
Anticipated output:
|
$ ollama —model ollama model is 0.33.2
$ curl http://localhost:11434/api/tags {“fashions”:[]} |
The primary command checks that the binary is put in accurately. The second hits Ollama’s native API immediately, and an empty fashions array is the anticipated, appropriate response at this level; it confirms the server is listening — you simply haven’t downloaded a mannequin into it but.
Now pull a mannequin. That is the one most consequential selection in the entire setup, as a result of not each mannequin can really act as an agent:
| Mannequin | Dimension on Disk | RAM Wanted | Instrument Calling | Greatest For |
|---|---|---|---|---|
| gemma4:31b | ~20 GB | 24+ GB | Sure | Very best quality, robust software use and reasoning |
| gemma2:27b | ~16 GB | 20+ GB | No | Conversational duties, no software use |
| gemma2:9b | ~5 GB | 8+ GB | No | Quick chat, Q&A, can’t name instruments |
| llama3.2:3b | ~2 GB | 4+ GB | No | Light-weight fast solutions solely |
That “Instrument Calling” column is the entire ballgame for this challenge. Hermes is an agentic assistant particularly as a result of it may possibly name instruments, edit a file, run a command, search the online, and a model without tool-call support can only chat back at you — it can’t really take an motion in your behalf, regardless of how effectively it writes. For the file-organizing, web-searching assistant this text is constructing, meaning gemma4:31b is the actual place to begin, not the smaller choices.
As soon as it’s downloaded, affirm the mannequin itself really solutions accurately:
|
curl http://localhost:11434/v1/chat/completions –H “Content material-Sort: utility/json” –d ‘{ “mannequin”: “gemma4:31b”, “messages”: [{“role”: “user”, “content”: “Say hello”}], “max_tokens”: 50 }’ |
Anticipated output:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 |
{ “id”: “chatcmpl-123”, “object”: “chat.completion”, “created”: 1735689600, “mannequin”: “gemma4:31b”, “decisions”: [ { “index”: 0, “message”: { “role”: “assistant”, “content”: “Hello! How can I help you today?” }, “finish_reason”: “stop” } ], “utilization”: { “prompt_tokens”: 10, “completion_tokens”: 9, “total_tokens”: 19 } } |
This sends an actual chat completion request in the identical JSON form an OpenAI-style API expects, which is precisely the purpose: you might be confirming this endpoint behaves like some other LLM API earlier than wiring Hermes as much as it. The response follows Ollama’s documented OpenAI-compatible format precisely; decisions[0].message.content material is the precise reply textual content, and this is identical area Hermes itself reads beneath the hood.
Configure Hermes
With Ollama serving a mannequin, level Hermes at it. The guided path is the setup wizard:
When it asks for a supplier, select Customized Endpoint and enter http://localhost:11434/v1 as the bottom URL, depart the API key empty (Ollama doesn’t test for one), and set the mannequin to gemma4:31b.
The direct path is enhancing ~/.hermes/config.yaml your self:
|
mannequin: default: “gemma4:31b” supplier: “customized” base_url: “http://localhost:11434/v1” |
supplier: "customized" is what tells Hermes to deal with this as a generic OpenAI-compatible endpoint reasonably than on the lookout for a particular supplier’s authentication scheme. base_url is Ollama’s native deal with, and default units which pulled mannequin Hermes really sends requests to.
Begin Utilizing Hermes
Launch it:
Anticipated output:
|
Hermes Agent v0.21.1 Linked to: gemma4:31b (customized endpoint: http://localhost:11434/v1) Reminiscence: loaded (0 abilities, 0 previous periods)
You: _ |
For the file-organizing challenge from the sooner part, listed here are actual prompts to attempt in opposition to an precise challenge folder:
|
You: Checklist all Python recordsdata in this listing and rely the strains of code in every
You: Learn the README.md and summarize what this challenge does
You: Create a Python script that fetches the climate for Ho Chi Minh Metropolis |
Anticipated output (for the primary immediate, shortened):
|
Hermes: I‘ll listing the Python recordsdata and rely their strains.
[running: find . –name “*.py” –exec wc –l {} ;]
Discovered 4 Python recordsdata: agent.py 182 strains utils.py 64 strains test_agent.py 103 strains config.py 21 strains
Complete: 370 strains throughout 4 recordsdata. |
Every of those workout routines a unique actual functionality — the primary makes use of the terminal and filesystem instruments collectively, the second reads and causes over an actual file’s content material, and the third has the agent write and will optionally run a contemporary script. None of this entails a cloud name; Hermes makes use of the terminal software, file operations, and your native mannequin for all three, which is your entire level of this setup.
Selecting the Proper Mannequin for Your Process
Not each request wants the total 31B mannequin, and operating it for a fast factual query wastes time you don’t want to spend.
| Process | Really helpful Mannequin | Why |
|---|---|---|
| File edits, code, terminal instructions | gemma4:31b | Solely mannequin right here with dependable software calling |
| Fast Q&A, no software use wanted | gemma2:9b | Quick responses for conversational duties |
| Light-weight chat | llama3.2:3b | Quickest, however very restricted functionality |
Swap fashions mid-session with out restarting something:
Anticipated output:
|
Switched to gemma2:9b. Word: this mannequin does not assist software calling, file and terminal actions will be unavailable till you swap again. |
It is a genuinely sensible behavior value constructing early — preserve the large tool-calling mannequin as your default for the file and internet work this challenge really wants, and swap all the way down to a lighter mannequin for a fast aspect query, then swap again. Ollama hundreds the lively mannequin into reminiscence on demand and routinely unloads idle ones, so this switching prices you time on the following load, not disk house sitting unused.
Optimize for Velocity
Three actual levers, within the order most individuals really want them.
Enhance Ollama’s context window. Ollama defaults to a 2,048-token context, which is way too small for agentic work — Hermes requires at the very least 64,000 tokens to operate correctly with software schemas and file content material in play:
|
cat > /tmp/Modelfile << ‘EOF’ FROM gemma4:31b PARAMETER num_ctx 64000 EOF
ollama create gemma4–64k –f /tmp/Modelfile |
A Modelfile is Ollama’s personal format for customizing a mannequin with out re-downloading it. FROM names the bottom mannequin, and PARAMETER num_ctx 64000 overrides its context window. This produces a brand new named mannequin, gemma4-64k, which you then set because the default in your Hermes config as an alternative of the bottom gemma4:31b.
Hold the mannequin loaded. By default, Ollama unloads a mannequin after 5 minutes of inactivity, that means the following request pays a full reload price:
|
curl http://localhost:11434/api/generate –d ‘{“mannequin”: “gemma4:31b”, “keep_alive”: “24h”}’ |
This single request tells Ollama to carry this mannequin in reminiscence for twenty-four hours no matter idle time, which issues most for the Telegram gateway within the subsequent part — a bot that has to reload a 20 GB mannequin on each incoming message can be unusable.
Use GPU offloading, when you’ve got one. Ollama routinely offloads mannequin layers to an obtainable NVIDIA GPU with no configuration wanted. Verify what is definitely taking place with:
This reveals which mannequin is presently loaded and the way a lot of it landed on the GPU versus CPU, following Ollama’s documented ps output format. Even a partial offload — roughly 40 layers on a 12 GB GPU for a 31B model, with the rest on CPU — provides an actual, noticeable speedup over CPU-only.
Optionally available: Run as a Gateway Bot
With the core agent working, expose it to Telegram so it’s reachable out of your telephone, nonetheless operating completely by yourself {hardware}.
Create a bot by @BotFather on Telegram and get its token, then add it to ~/.hermes/config.yaml:
|
mannequin: default: “gemma4:31b” supplier: “customized” base_url: “http://localhost:11434/v1”
platforms: telegram: enabled: true token: “YOUR_TELEGRAM_BOT_TOKEN” |
Then begin the gateway as an alternative of the common CLI session:
Anticipated output:
|
Hermes Gateway v0.21.1 Mannequin: gemma4:31b (customized endpoint: http://localhost:11434/v1) Telegram: related as @your_bot_name Listening for messages... |
The platforms.telegram block is additive — it sits alongside the identical mannequin configuration reasonably than changing it, which is precisely why the file-organizing assistant you constructed earlier is identical agent now answering you on Telegram: identical reminiscence, identical mannequin, totally different floor.
Optionally available: Set Up Fallbacks
Native fashions can genuinely wrestle on the toughest questions, and reasonably than accepting a foul reply, you possibly can configure a cloud mannequin as a fallback that solely prompts when it’s really wanted:
|
mannequin: default: “gemma4:31b” supplier: “customized” base_url: “http://localhost:11434/v1”
fallback_providers: – supplier: openrouter mannequin: anthropic/claude–sonnet–4 |
fallback_providers is a listing, evaluated solely when the first mannequin fails or repeatedly produces a malformed response — not on each request. That’s what retains the associated fee mannequin sincere: the large majority of everyday use stays free and local, and only the genuinely hard cases reach a paid API, which is the precise level of constructing a hybrid setup reasonably than an all-local or all-cloud one.
Wrapping Up
What you could have operating on the finish of this text is an actual, full native workflow: Ollama serving a genuinely tool-capable mannequin by yourself {hardware}, Hermes utilizing that mannequin to learn your recordsdata, run instructions, and search the online with zero API price and 0 information leaving your machine, reachable out of your telephone by the Telegram gateway if you find yourself away out of your desk, with a cloud mannequin ready quietly in reserve for the uncommon query native {hardware} can’t deal with effectively.
That’s the precise form of local-first setup — not all-or-nothing between free-but-limited and capable-but-expensive, however a system the place the free path handles nearly the whole lot and the paid path solely ever will get referred to as in when it has genuinely earned its price.