
Generative AI inference is uniquely laborious: fashions are tens to a whole lot of gigabytes, latency necessities are measured in tokens per second, chilly begins can span a number of minutes as containers and weights switch, GPU capability is constrained, and conventional monitoring instruments expose not one of the token-level alerts that matter in manufacturing.
Amazon SageMaker AI provides clients the power to deploy AI fashions and eat them by the occasion (as an alternative of by the token), utilizing two paths: managed endpoints for groups that need AWS to deal with infrastructure and operations, and Amazon SageMaker HyperPod Inference for groups that want Kubernetes-native management over devoted GPU clusters. Yr-to-date in 2026, SageMaker AI delivered 13 new capabilities throughout these two paths and this put up walks by way of these capabilities and advantages to enterprises, startups and public sector.
Select the deployment that matches your workload
The desk beneath compares the 2 deployment paths throughout seven dimensions.
| Dimension | Endpoints | HyperPod |
| Infrastructure | Absolutely managed by AWS | Managed Kubernetes stack |
| Deploy goal | Console, SDK, CLI | kubectl, Terraform, Console, CLI, SDK |
| Scaling | Managed auto scaling with Amazon CloudWatch | Auto scaling with Karpenter, KEDA, CloudWatch |
| Customization and Management | Customizable on the container and mannequin layers | Extra customizability with Node degree entry, frameworks and AMI. |
| API protocol | OpenAI suitable with SageMaker endpoint | HTTP, gRPC and customized load balancer functionality |
| Greatest for | Quick and absolutely managed deployment with minimal ops overhead | Kubernetes-based, train-to-serve multi-cloud/hybrid-cloud deployments |
| Corresponding Launches: | ||
| Launches | Inference suggestions, Capability Conscious Inference, OpenAI API, Container Caching, Observability, Async Inference Inline Payloads, Prefix-Conscious Routing | Simplified Operator, Tiered KV Cache, Information Seize, Efficiency Options, Disaggregated Prefill and Decode for HyperPod Inference, Mannequin Caching |
Determine 1: Two inference paths delivered in 2026
SageMaker AI endpoints: From mannequin to manufacturing in hours
Managed SageMaker Inference endpoints are the sooner path for groups that need AWS to deal with GPU provisioning, scaling, and operational monitoring. You carry the mannequin and outline the efficiency goal. SageMaker handles the remaining. The seven launches year-to-date in 2026 beneath deal with deployment, capability, integration, scaling, observability, and async simplification.
Inference suggestions and benchmarking (April 2026)
Weblog: Amazon SageMaker AI now helps optimized generative AI inference suggestions
Selecting the best occasion sort, serving container, and optimization settings for a generative AI mannequin usually takes two to 3 weeks of handbook benchmarking towards 1000+ mixtures, requiring experience most groups shouldn’t have in-house. Inference suggestions automate this end-to-end.
Prospects specify a mannequin and efficiency purpose (price, latency, or throughput). SageMaker then runs a three-step course of:
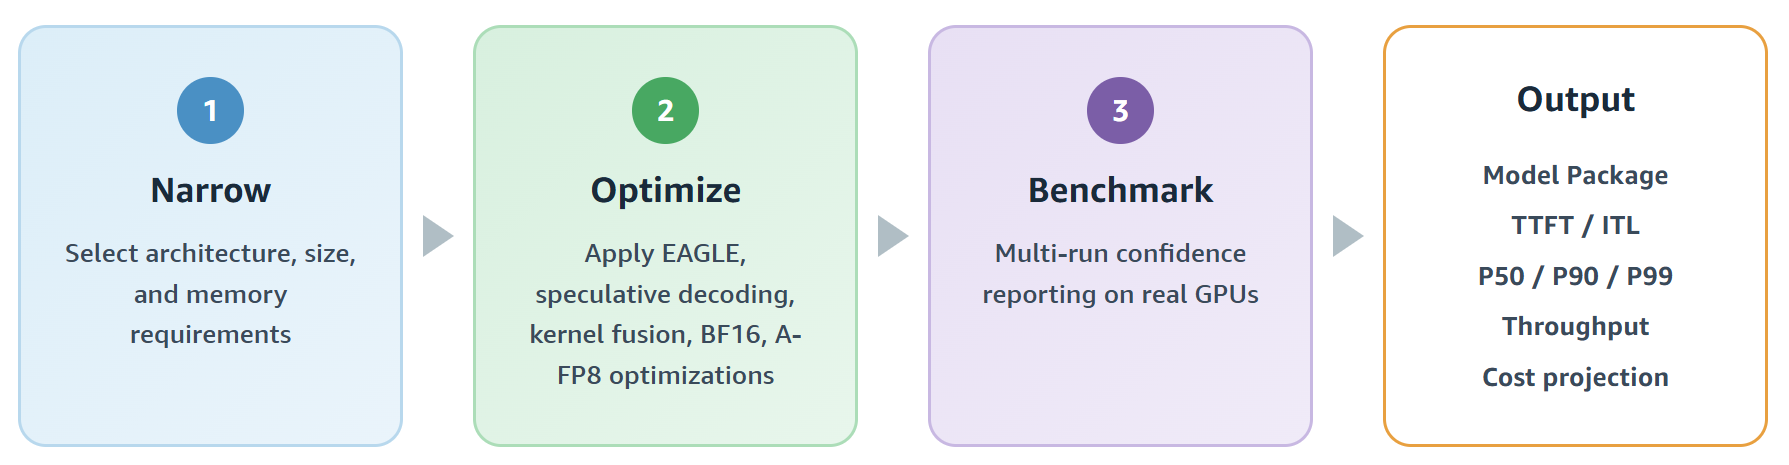
Determine 2: Inference suggestions 3-step course of
- Slender. Filter the occasion sort house by analyzing mannequin structure, measurement, and reminiscence necessities.
- Optimize. Apply goal-aligned methods: EAGLE 3.0 speculative decoding for throughput, kernel tuning for latency, tensor parallelism based mostly on mannequin measurement.
- Benchmark. Run NVIDIA AIPerf on actual GPU infrastructure with statistically rigorous multi-run confidence reporting.
The output is a SageMaker Mannequin Bundle with deployment-ready configurations and validated metrics: time to first token (TTFT), inter-token latency (ITL), P50/P90/P99 latency percentiles, throughput, and price projection. In a demonstrated instance, throughput optimization on GPT-OSS-20B delivered 2x tokens per second on the similar request latency. There is no such thing as a further price for producing suggestions. Prospects with ML Reservations can benchmark on reserved capability at no further cost, and inference recommender can be used to guage different occasion sorts.
Capability-aware occasion swimming pools (Might 2026)
Weblog: Capability-aware inference: automated occasion fallback for SageMaker AI endpoints
When a SageMaker endpoint required a single occasion sort, a capability scarcity meant the endpoint failed earlier than serving a single request. Occasion swimming pools deal with that single level of failure.
Prospects outline a prioritized record of as much as 5 occasion sorts. SageMaker mechanically works by way of the record at endpoint creation, throughout scale-out, and through scale-in. At creation, SageMaker tries the first-choice sort and falls again instantly if capability is unavailable. Throughout scale-out, the subsequent obtainable sort within the precedence record absorbs demand. Throughout scale-in, fallback situations are eliminated first, so the fleet traits again towards most well-liked {hardware} as capability opens up.
Per-instance-type CloudWatch metric dimensions allow weighted scaling insurance policies for heterogeneous fleets. Every pool entry can reference a separate optimized mannequin configuration (tensor parallelism on high-memory situations, speculative decoding on mid-tier, quantization on smaller fallbacks), and inference suggestions can generate these per-hardware configurations mechanically. Supported for single-model, inference element, and async endpoints in all industrial AWS Areas.
OpenAI-compatible APIs (Might 2026)
Weblog: Saying OpenAI-compatible API assist for Amazon SageMaker AI endpoints
Purposes constructed on the OpenAI SDK, LangChain, or Strands Brokers beforehand required customized shopper adapters and authentication rewrites to work with SageMaker-hosted fashions. That migration price was an actual barrier.
SageMaker endpoints now expose an /openai/v1 path supporting Chat Completions with streaming. Migration requires altering solely the endpoint URL. SDK calls, streaming logic, and immediate formatting stay similar. Authentication makes use of bearer tokens generated from current AWS credentials, legitimate for as much as 12 hours, eradicating SigV4 signing complexity.
Multi-model endpoints permit internet hosting a number of fashions, every callable by way of the identical OpenAI SDK with impartial useful resource allocation. For agentic workloads, AI brokers can run totally on customer-owned GPU infrastructure utilizing the identical OpenAI-compatible interface they have been constructed on. Obtainable in 14 AWS Areas, with assist for vLLM and SGLang AWS Deep Studying Containers and customized containers implementing the /v1/chat/completions path.
Container caching (June 2026)
Weblog: Introducing container caching in Amazon SageMaker AI for sooner mannequin scaling
Throughout inference auto scaling occasions, new situations responding to site visitors spikes beforehand needed to pull the total container picture from Amazon Elastic Container Registry (Amazon ECR) earlier than serving requests. For giant serving containers exceeding 10 GB, that pull alone added a number of minutes of lifeless time to each scale-out occasion.
Container caching pre-pulls photographs mechanically, so new situations launch with the container already obtainable regionally. Zero configuration, no code adjustments, no container modifications. It prompts mechanically on supported accelerator occasion sorts. With Qwen3-8B on ml.g6.2xlarge utilizing the LMI container (17.7 GB compressed), end-to-end startup latency dropped from 525 seconds to 258 seconds, a 51% discount. Mannequin obtain time additionally improved, from 168 seconds to 77 seconds, as a result of the picture is not competing for community bandwidth. Early entry clients noticed enhancements starting from 38% to 65%.
Container caching is the third layer in a three-part scaling optimization suite:
| Layer | Optimization | Impression |
| Detection | Sub-minute CloudWatch metrics | Triggers scale-up 6x sooner than commonplace 1-minute metrics |
| Present situations | Occasion-store knowledge caching | Removes picture pull and mannequin obtain for situations already working |
| New situations | Container picture caching | Avoids picture pull time; 51% startup latency discount demonstrated |
Inference observability and CloudWatch Insights dashboard (June 2026)
Weblog: Monitor and debug generative AI inference with SageMaker detailed metrics and insights dashboard on CloudWatch
Token-level latency, KV cache strain, GPU reminiscence traits, and inference element placement throughout Availability Zones are alerts that scattered CloudWatch metrics couldn’t floor collectively, forcing groups to correlate issues manually after customers had already been affected.
SageMaker now emits 100+ detailed inference metrics by way of native OpenTelemetry, paired with a pre-built Insights dashboard in Amazon CloudWatch. Zero instrumentation required. New endpoints have observability enabled by default, with metrics flowing inside two minutes of reaching InService standing. The dashboard covers three areas:
- Efficiency. Time to first token (TTFT), inter-token latency (ITL), throughput, mannequin latency vs. system overhead, KV cache utilization, and queue depth.
- Capability. GPU utilization, reminiscence, temperature, and disk throughout the fleet, with honeycomb visualizations for at-a-glance occasion well being.
- Reliability. Availability Zone distribution with threat scoring, chilly begin anatomy (mannequin obtain, GPU load, container begin phases), and scaling occasion historical past.
A PromQL-compatible endpoint lets groups question SageMaker metrics straight from Amazon Managed Grafana or a PromQL-compatible device by way of SigV4 authentication.
Async inference inline payloads (June 2026)
Weblog: Amazon SageMaker AI async inference now helps inline request payloads
Async inference beforehand required importing each enter payload to Amazon Easy Storage Service (Amazon S3) earlier than invoking the endpoint, even for a easy JSON immediate of some hundred bytes, including structure complexity and latency on each request.
The InvokeEndpointAsync API now accepts a Physique parameter with payloads as much as 128,000 bytes straight within the request, eradicating the S3 pre-staging step for the overwhelming majority of async workloads. Key advantages: one fewer community round-trip per request, no enter bucket provisioning or IAM s3:PutObject grants, fast measurement and parameter validation, and avoidance of the S3 PUT cost per invocation. Absolutely backward suitable. Present InputLocation workflows proceed unchanged. Obtainable in 31 AWS Areas.
Prefix-aware routing
Useful resource: Cut back LLM latency with prefix-aware routing on Amazon SageMaker Inference
A brand new routing technique that reduces LLM latency by directing requests with shared immediate prefixes to the identical occasion. In lots of LLM purposes, a big portion of the immediate (system directions, retrieved paperwork, dialog historical past) is repeated throughout requests. Usually, every occasion recomputes these shared tokens from scratch, losing GPU sources.
Prefix-aware routing solves this through the use of the start of every request as a fingerprint to persistently route related prompts to the identical occasion, maximizing KV cache reuse. It contains built-in safeguards for overload safety and steady conduct throughout scaling occasions.
Benchmarks on Llama 3.1 70B throughout 7 situations confirmed vital positive aspects: for long-context workloads (8,000-token prefixes), P90 TTFT dropped by 33–37%, P50 TTFT by 71–77%, and KV cache hit charges jumped from ~25% to 82%. Quick-context workloads additionally improved, with P90 TTFT decreased by 24–37%. The routing overhead is minimal, including just one.3–1.9 milliseconds per request.
SageMaker now provides three routing methods: RANDOM (default), LEAST_OUTSTANDING_REQUESTS, and the brand new PREFIX_AWARE. The function is good for RAG purposes, multi-turn conversations, templated bots, and code completion situations.
Enabling it requires solely setting RoutingStrategy, PrefixLength, and ConcurrencyThreshold within the endpoint configuration. No adjustments to mannequin containers or serving frameworks are wanted. It additionally helps multi-tenant prefix isolation, inference parts, and dynamic LoRA adapters. The function is accessible in the present day on SageMaker real-time inference endpoints.
HyperPod Inference: Manufacturing-grade inference in your Kubernetes clusters
HyperPod Inference extends HyperPod’s cluster resilience into the serving layer for groups who want Kubernetes-native management. It’s constructed for practitioners who need to personal their GPU infrastructure whereas nonetheless getting AWS-managed reliability on high. The six launches year-to-date in 2026 beneath deal with deployment, latency, compliance, and compute specialization.
Simplified Inference Operator on EKS (April 2026)
Blogs: Unlock environment friendly mannequin deployment: Simplified Inference Operator setup on Amazon SageMaker HyperPod | Greatest practices to run inference on Amazon SageMaker HyperPod
Deploying an LLM on Kubernetes usually requires writing and sustaining Deployments, Providers, ConfigMaps, HorizontalPodAutoscaler configs, and well being examine wiring for every mannequin. For groups managing dozens of fashions, that handcrafted infrastructure turns into an engineering burden in itself.
The Simplified Inference Operator is a local EKS add-on that installs in a single step by way of the AWS console, CLI, SDK, kubectl, or Terraform. As soon as put in, groups deploy fashions by submitting a single customized useful resource definition as an alternative of a stack of low-level Kubernetes objects. Key capabilities embody:
- Multi-instance sort fallback. Precedence-ordered occasion record. The operator tries every in sequence, so fashions attain serving standing with out handbook intervention.
- Constructed-in autoscaling. Native integration with CloudWatch, Amazon Managed Service for Prometheus, and KEDA for event-driven scaling.
- EKS add-on lifecycle. AWS manages model upgrades, compatibility checks, and well being monitoring as a part of the cluster lifecycle.
- JumpStart integration. Deploy standard basis fashions straight from SageMaker JumpStart by way of the identical operator interface.
Managed tiered KV cache and clever routing
Weblog: Managed tiered KV cache and clever routing for Amazon SageMaker HyperPod
For long-context and multi-turn workloads, LLMs recompute key-value consideration values for shared prefixes on each request. With out caching, that redundant computation accumulates straight as latency and GPU price.
HyperPod Inference manages a two-tier KV cache. The L1 tier lives in CPU reminiscence on every node for low-latency native reuse. The L2 tier makes use of Redis for cross-node sharing, so a cached prefix computed by one mannequin pod may be reused by different pods within the fleet. Clever routing retains the cache efficient by directing requests to the suitable situations:
- Prefix-aware routing. Routes requests with shared system prompts or doc prefixes to situations most definitely to have a cache hit.
- KV-aware routing. Use real-time cache state to path to situations with highest cache occupancy for the incoming request.
- Spherical-robin. Normal load distribution for workloads the place cache reuse isn’t a precedence.
Collectively, tiered caching and clever routing ship as much as 40% latency discount for long-context and multi-turn workloads in comparison with a non-cached baseline.
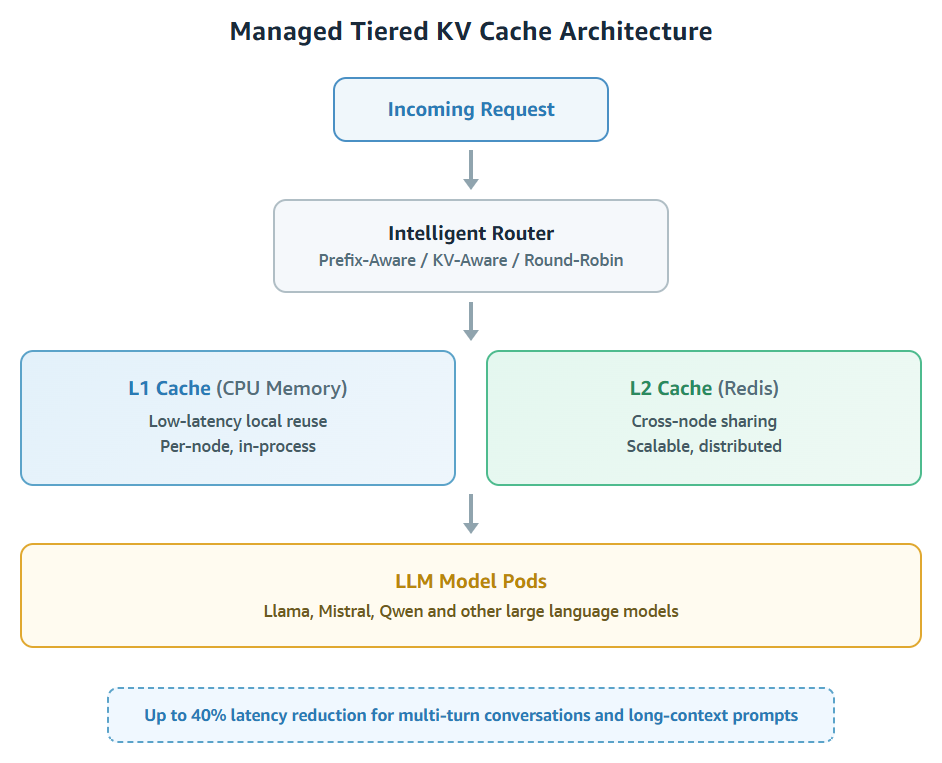
Determine 3: Two-tier KV cache with clever routing in HyperPod Inference
Information seize (Might 2026)
Assets: Amazon SageMaker HyperPod knowledge seize for inference workloads (What’s New) | Enhancing enterprise inference on HyperPod with knowledge seize, Hugging Face, NVMe, and Route 53 integration
Regulated enterprises want tamper-evident logs of inference exercise for compliance, drift monitoring, and offline analysis dataset building. Constructing that logging infrastructure throughout a number of request paths from scratch is non-trivial.
HyperPod Inference knowledge seize gives three seize factors enabled by way of the customized useful resource definition (CRD): the SageMaker endpoint (full request and response on the utility boundary), the ALB (load balancer site visitors for routing visibility and latency measurement), and the mannequin pod (request and response on the container boundary for model-level debugging). Captured knowledge flows to Amazon S3 with no customized sidecar containers or utility instrumentation required. Groups can allow seize selectively at any of the three factors to maintain storage prices proportional to precise wants.
Disaggregated prefill and decode (July 2026)
Assets: Disaggregated prefill and decode for LLM inference on SageMaker HyperPod | Amazon SageMaker HyperPod now helps disaggregated prefill and decode (What’s New)
When prefill and decode share the identical GPU pool, an extended prefill for a posh immediate blocks token technology for each concurrent person within the queue. Underneath blended site visitors, this makes per-token latency unpredictable in proportion to request complexity.
Disaggregated Prefill and Decode (DPD), shipped in Inference Operator v3.2, separates these phases onto distinct GPU swimming pools. Prefill GPUs deal with immediate processing. As soon as the KV cache for a request is prepared, it transfers to the decode pool over EFA utilizing GPU-Direct RDMA, a direct reminiscence switch that bypasses the CPU totally. Decode GPUs then generate output tokens with out interference from incoming prefill work. Every pool scales independently: if prefill throughput is the bottleneck, extra prefill GPUs may be added with out touching the decode fleet.
Validated on Llama 3.3 70B below blended site visitors, DPD produced measurably extra constant TTFT and ITL distributions in comparison with colocated prefill and decode. Operators specify separate occasion swimming pools for prefill and decode nodes within the customized useful resource definition. The Inference Operator manages EFA configuration and KV cache switch mechanically.
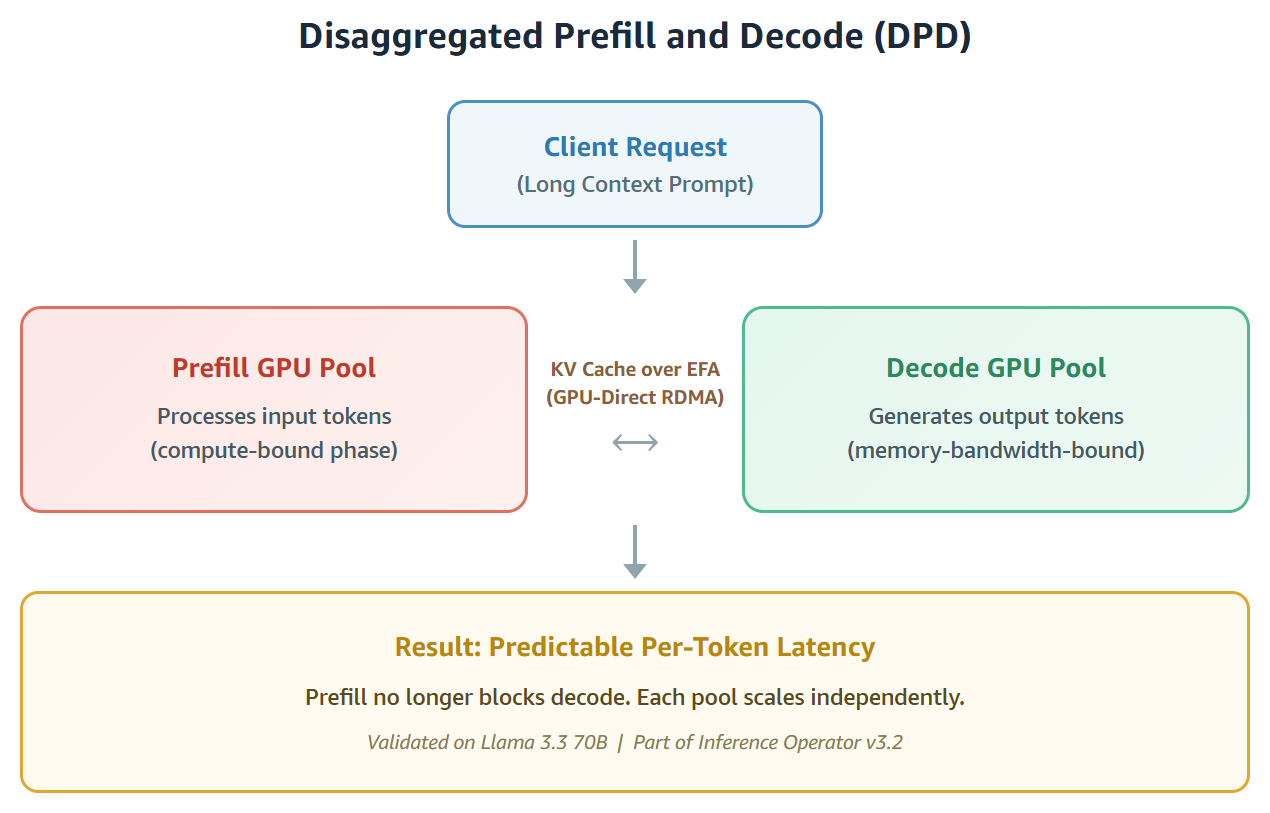
Determine 4: Disaggregated prefill and decode structure with EFA KV cache switch
Efficiency options with Hugging Face, NVMe, and Route 53 (July 2026)
Assets: Enhancing enterprise inference on Amazon SageMaker HyperPod with knowledge seize, Hugging Face, NVMe, and Route 53 integration
Amazon SageMaker HyperPod introduces new capabilities that improve deployment flexibility, efficiency, and safety for enterprise generative AI inference. Hugging Face Hub Integration enables you to deploy fashions straight with out pre-staging weights to S3, with assist for gated fashions, revision pinning, and token isolation throughout vLLM, TGI, and SGLang runtimes. Native NVMe Mannequin Loading reduces cold-start latency by studying weights from node-local storage as an alternative of pulling over the community—excellent for autoscaling and scale-from-zero situations. When NVMe isn’t obtainable, automated fallback to cloud storage facilitates reliability. Amazon Route 53 DNS Administration mechanically creates, updates, and cleans up DNS data for customized inference domains by way of easy CRD configuration. Customized Service Accounts with IRSA present pod-level IAM permissions, giving infrastructure groups fine-grained management over safety boundaries. Collectively, these options assist groups deploy AI purposes sooner with out compromising governance or operational visibility.
Amazon SageMaker HyperPod with mannequin caching
Assets: Cut back inference chilly begins on Amazon SageMaker HyperPod with mannequin caching
When deploying massive language fashions on Amazon SageMaker HyperPod, chilly begins create vital delays as pods should obtain mannequin weights from distant storage and pull container photographs from Amazon ECR earlier than serving requests. This drawback compounds throughout scale-out occasions when a number of pods begin concurrently.
SageMaker HyperPod now provides mannequin caching, which addresses this by way of two complementary mechanisms. The weights cache pre-downloads mannequin weights to native NVMe storage on every node, enabling reads at roughly 7 GB/s as an alternative of ready for distant downloads. The picture cache pre-pulls inference container photographs onto nodes by way of a DaemonSet, saving 5 to 7 minutes per pod begin. Each caches use most well-liked (not required) scheduling, so pods can nonetheless begin on uncached nodes with a swish fallback.
The function is managed by way of two Customized Useful resource Definitions (CRDs): ModelDataCacheConfig for weights and ModelImageCache for container photographs. The operator handles the total lifecycle mechanically, together with cache invalidation when mannequin sources change.
Enabling caching requires including a modelCacheConfig part to your current InferenceEndpointConfig or JumpStartModel useful resource, with toggles for weights and picture caching independently. It helps most mannequin sources together with Amazon S3, Amazon FSx for Lustre, and Hugging Face Hub.
Benchmarks present round 60% sooner scale-out for fashions starting from 57 GB to 145 GB. Key limitations embody per-node storage (every node maintains its personal copy), NVMe capability constraints, and the truth that supply updates on the similar path should not auto-detected. Cleanup is automated while you delete the guardian useful resource. The function is now usually obtainable in all supported HyperPod areas.
The compound worth: 13 launches throughout the inference stack
Our function launches give attention to decreasing time-to-market, letting clients use state-of-the-art capabilities out of the field with sturdy price-performance. Every of those launches addresses a definite friction level throughout the inference lifecycle, from first deployment resolution to manufacturing operations:
- Inference Suggestions (April 2026). Automates occasion choice, optimization, and benchmarking. Cuts weeks of handbook work to hours.
- Capability-Conscious Occasion Swimming pools (Might 2026). As much as 5 occasion sorts with automated fallback at creation, scale-out, and scale-in. No handbook retry cycles.
- OpenAI-Suitable APIs (Might 2026). SageMaker endpoints change into a drop-in backend for OpenAI SDK, LangChain, or Strands Brokers purposes.
- Container Caching (June 2026). 51% startup latency discount demonstrated. Zero configuration. Prompts mechanically on supported situations.
- Inference Observability Dashboard (June 2026). 100+ metrics by way of OpenTelemetry in a pre-built CloudWatch dashboard overlaying efficiency, capability, and reliability.
- Async Inference Inline Payloads (June 2026). 128 KB inline physique parameter avoids necessary S3 pre-staging for async workloads. Obtainable in 31 Areas.
- Simplified Inference Operator on EKS (April 2026). Single EKS add-on set up. Full lifecycle administration. Multi-instance fallback and built-in autoscaling by way of CloudWatch, Amazon Managed Service for Prometheus, and KEDA.
- Managed Tiered KV Cache and Clever Routing. L1 (CPU reminiscence) and L2 (Redis) caching with prefix-aware and KV-aware routing. As much as 40% latency discount.
- Information Seize (Might 2026). Three seize factors (endpoint, ALB, mannequin pod) enabled by way of CRD. Compliance-ready logging to S3 with no customized infrastructure.
- Disaggregated Prefill and Decode (July 2026). Separate GPU swimming pools for prefill and decode. KV cache switch over EFA/GPU-Direct RDMA. Predictable ITL below concurrent load on Llama 3.3 70B.
- Efficiency Options (July 2026): Enhancing enterprise inference on Amazon SageMaker HyperPod with knowledge seize, Hugging Face, NVMe, and Route 53 integration.
- Amazon SageMaker HyperPod with mannequin caching (Sep 2026): Pre-load mannequin weights and container photographs on native NVMe to chop chilly begin occasions by as much as 60% on SageMaker HyperPod.
- Prefix-Conscious Routing (Sep 2026): Route repeated immediate prefixes to the identical occasion to maximise KV cache reuse, minimize time-to-first-token by as much as 77%, and enhance throughput throughout your SageMaker fleet.
From deployment to scaling to operations, these launches cowl each layer of the inference stack, throughout each managed endpoints and Kubernetes-native clusters. Aggressive benefit in AI inference more and more comes not from selecting the very best mannequin, however from working probably the most environment friendly inference stack. Utilizing the capabilities described on this put up doesn’t require a crew of AI infrastructure consultants or researchers. The AWS Expertise-Primarily based Acceleration program brings these capabilities to enterprises and startups to assist them configure and optimize instance-based AI inference. It really works by understanding your inference workloads, knowledge modalities, SLAs, and price targets, working benchmark evaluations, and configuring your inference stack to run AI inference at scale.
What’s subsequent
Funding continues throughout each managed endpoints and HyperPod Inference in 2026. On the managed endpoint facet, the main target is deeper in AWS AI panorama integration. On the HyperPod Inference facet, the roadmap contains further routing methods, broader mannequin serving framework assist, and expanded multi-region networking capabilities. Documentation and getting-started guides for all capabilities coated right here can be found within the Amazon SageMaker Developer Information. Begin deploying.
References
In regards to the authors