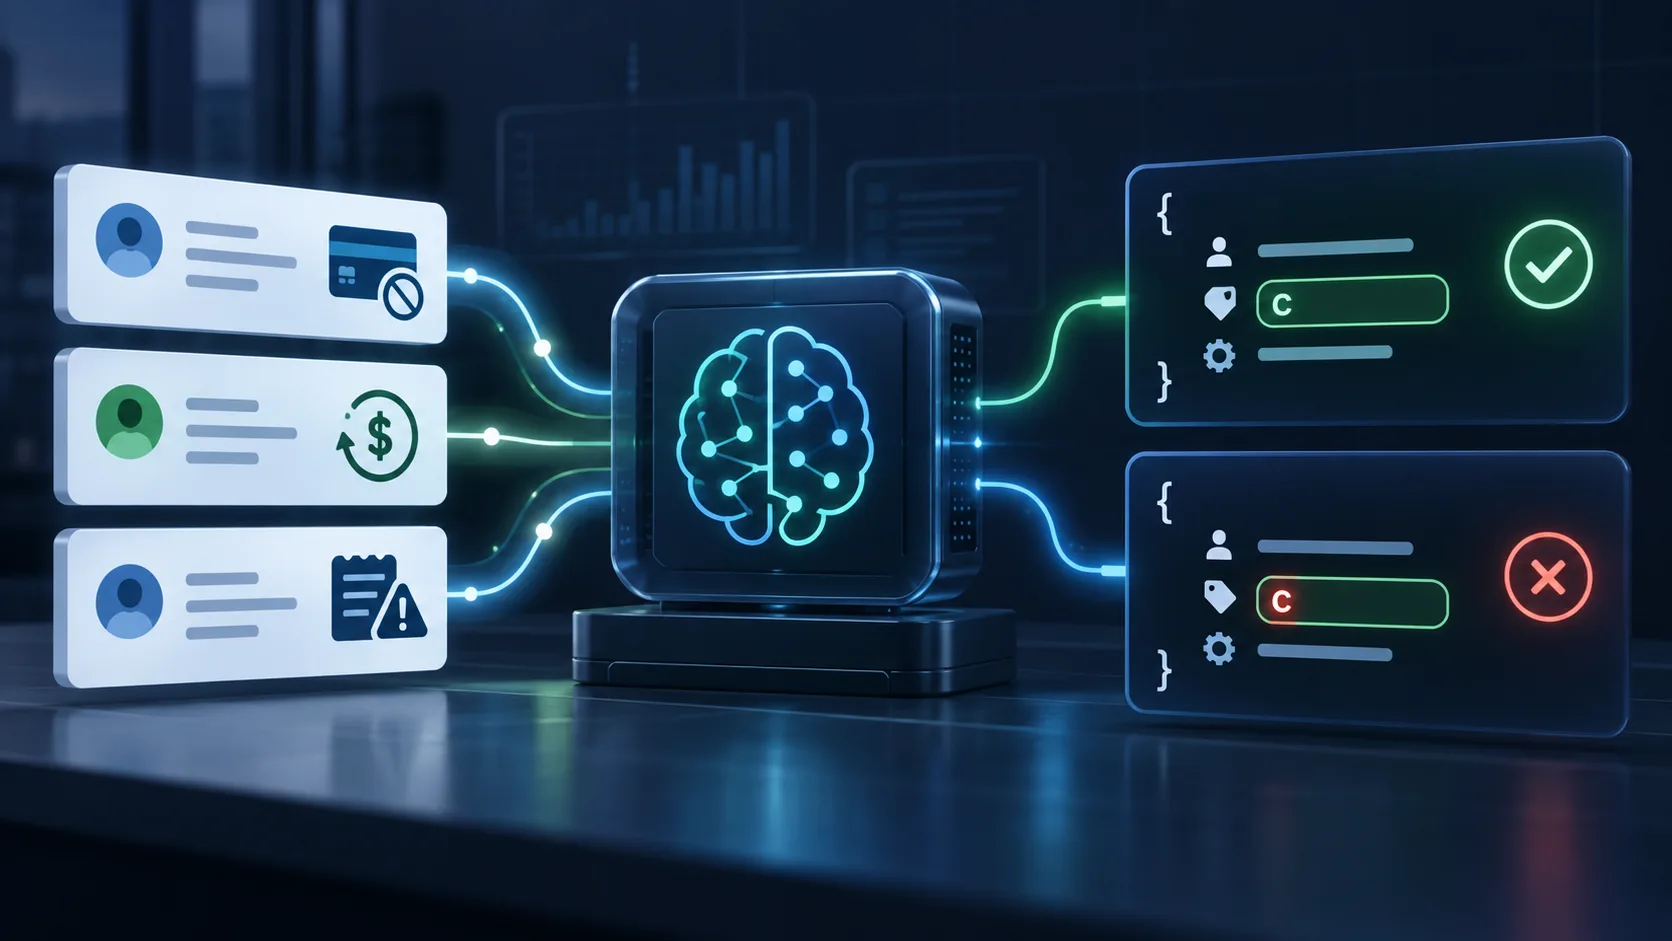

Image a help inbox for a financial institution. Each message that is available in must be sorted right into a class, a misplaced card, a refund request, a fallacious cost, and despatched to the fitting crew.
Now image that sorting job handed to an AI mannequin as a substitute of an individual. The mannequin reads the message and fingers again a brief word in a set format, a bit like a type with the identical bins each time, so the remainder of this system can learn it routinely and resolve what to do subsequent. No human has to interpret free textual content.
That fastened format is often a small block of pc readable textual content known as JSON, quick for JavaScript Object Notation. Consider it as labeled bins on a type. One field known as intent holds the class. One other known as precedence holds how pressing it’s.
This system studying the mannequin’s reply doesn’t perceive English. It appears for these actual bins, spelled precisely the best way it expects, each single time. If a field goes lacking, or a label is spelled barely in a different way than this system expects, this system has no technique to discover by itself. It simply quietly stops working for that one message, whereas the whole lot on the floor nonetheless appears tremendous.
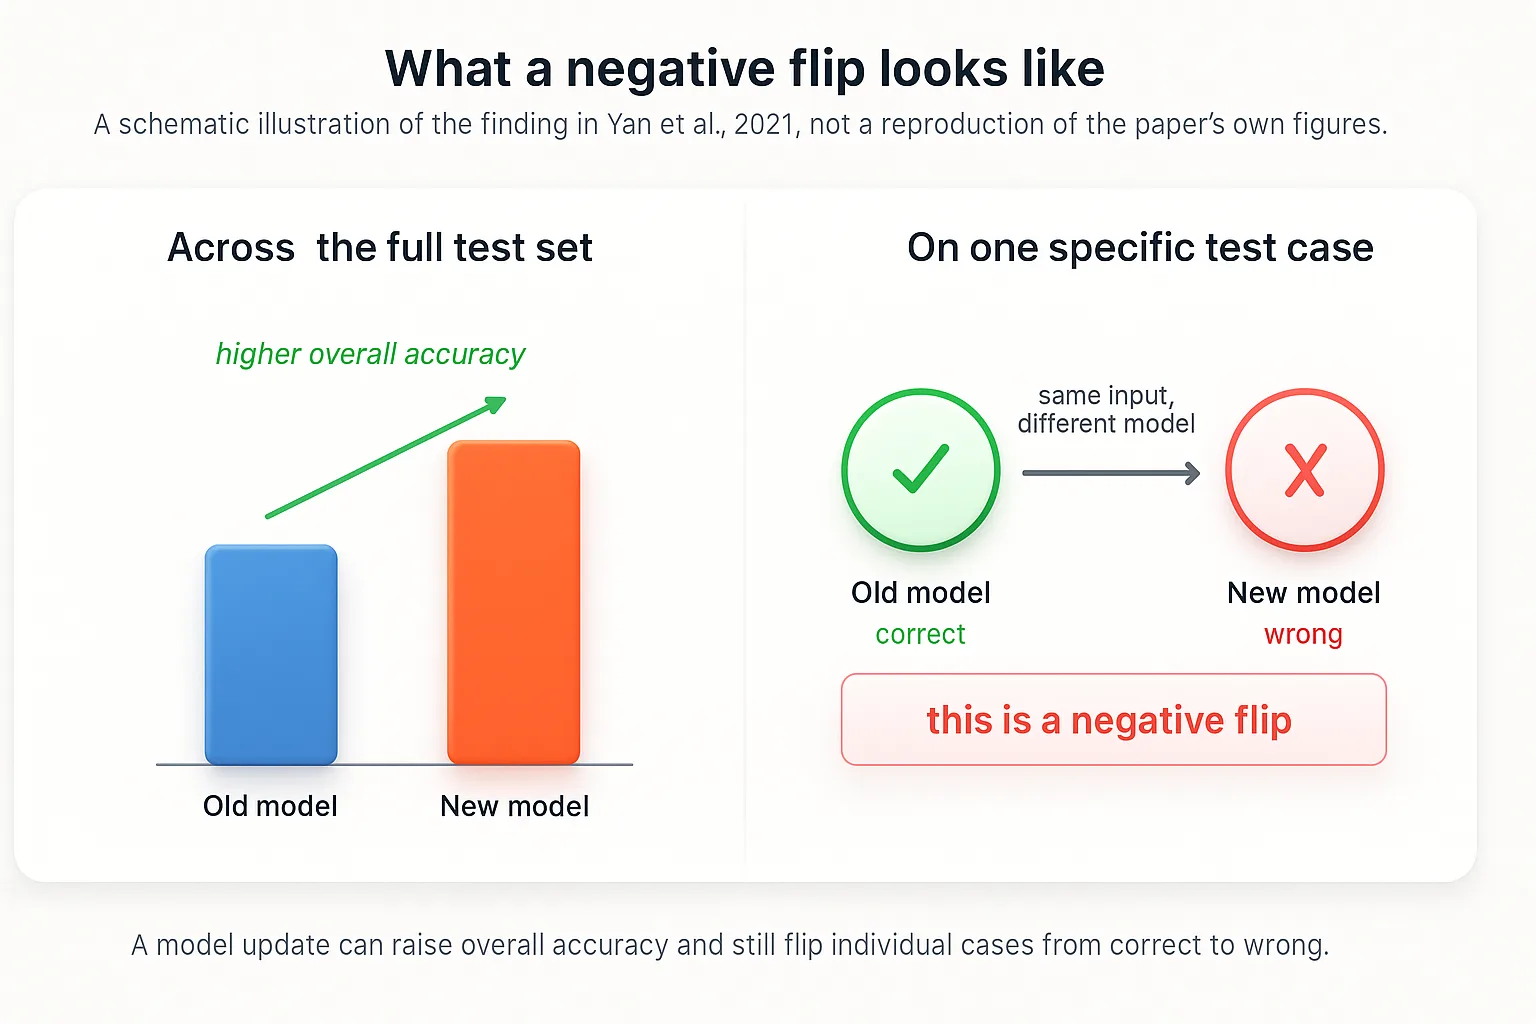
AI corporations launch new mannequin variations continuously, and deciding which LLM to make use of for a given job often comes down to at least one quantity from the AI testing groups already run, how usually it picks the fitting class. That single rating can go up whereas one thing else, the precise form of the reply, quietly will get worse, and a rising common has no technique to warn you.
With plain prompting, you merely write:
“Return your reply as JSON.”
The mannequin should return:
That additional sentence can break code that expects JSON solely. The mannequin may omit a area or use a price this system doesn’t anticipate.
Structured Outputs is a stricter function that makes the mannequin comply with a predefined JSON construction, corresponding to requiring intent, precedence, and needs_human. It may possibly stop many formatting issues, however the software nonetheless must examine whether or not the values and determination are right.
I ran an actual LLM regression check on one small, actual software, as a substitute of trusting the accuracy quantity alone. I constructed a help triage assistant, gave it 47 actual buyer messages from a public banking dataset, and ran the very same messages via three actual variations of an OpenAI mannequin, an older one, the one I’m treating because the mannequin presently in manufacturing, and a more recent candidate being thought of as a substitute.
I anticipated the newer mannequin to decide on the right class extra usually, however I additionally anxious that it would sometimes ignore the precise format this system requires. As a substitute, the newer mannequin adopted the format each time. The manufacturing mannequin made the formatting mistake. It did so quietly, on each refund query within the pattern, spelling one label Request_refund with a capital R as a substitute of the lowercase request_refund the remainder of the system expects.
A human studying the reply would name it right. A program matching labels precisely would silently drop each a type of tickets.
That’s the downside this text is about: a mannequin can sound right to an individual and nonetheless be fallacious for the software program that makes use of its reply.
What this undertaking builds, and why it makes use of Weave
Earlier than writing any code, it helps to have one clear image of what will get constructed and the way its items match collectively.
This undertaking does 5 issues:
-
Weave information what occurs when the applying runs: the query, the directions, the mannequin, the response, and the timing.
-
The directions given to the mannequin are saved with a model quantity, so older and newer directions might be in contrast.
-
The true buyer questions are saved as a check dataset, so each mannequin solutions the identical examples.
-
A strict checker exams every response for actual necessities, corresponding to legitimate JSON, required fields, allowed labels, and the right class.
-
A second AI mannequin reads every response and provides it a high quality rating, extra like a human reviewer would.
The strict checker appears for actual machine necessities. The second AI choose evaluates the reply extra like a reader. Utilizing each helps reveal issues that both checker would possibly miss.
Every of these concepts will get defined correctly because it comes up. For now, begin with Weave itself, since the whole lot else on this article is recorded inside it.
Weave is a device from Weights & Biases (W&B) for watching what an AI software really does whereas it runs. Add one line, @weave.op(), above any Python operate, and each single name to that operate will get saved routinely, the precise textual content that went in, the precise textual content that got here again, and the way lengthy it took.
Weave calls certainly one of these saved information a hint, and it shops each hint in a undertaking you’ll be able to open and browse in an internet web page, the identical method a photograph app retains a timeline of each photograph you are taking.
A hint is just not solely helpful for debugging a damaged run after the actual fact. As soon as an software has been answering actual questions for some time, its saved traces are additionally a prepared made supply of actual examples, which issues later on this article, because the identical 47 actual questions that hint the applying additionally turn out to be the dataset it will get examined in opposition to.
The applying itself is intentionally small, one operate, triage_message(textual content, mannequin, prompt_ref), that reads one actual buyer message and asks a mannequin to reply with a JSON object formed like this:
4 bins, each time. intent names the class. precedence is low, medium, or excessive. needs_human is true or false, and it decides whether or not the message will get escalated to an individual as a substitute of dealt with routinely. reply is the quick message the client really sees.
Solely two issues change throughout the remainder of this text: which mannequin solutions, and which model of the directions or the grading guidelines is lively. The applying logic itself by no means modifications, which is what makes the comparisons later on this article honest.
One alternative about how the mannequin will get requested issues sufficient to clarify now. The request to OpenAI makes use of plain prompted JSON, which means the mannequin is solely informed in phrases to answer on this form. It doesn’t use OpenAI’s stricter Structured Outputs function, the one already talked about above, which may power a mannequin’s reply into a set form by development.
That’s deliberate, not an oversight. Utilizing the strict function right here would have hidden among the very failures this text is constructed to search for, an invalid response, additional textual content wrapped across the JSON, or a mislabeled area. Later within the article, upon getting seen what really broke, there may be an sincere take a look at precisely which of these failures the strict function would and wouldn’t have caught.
The true buyer messages come from BANKING77, a public dataset from a 2020 analysis paper by Iñigo Casanueva and coauthors at PolyAI (CC BY 4.0 license). It accommodates 13,083 actual banking customer support questions, every labeled by hand with certainly one of 77 tremendous grained classes, a card that by no means arrived, a refund that by no means confirmed up, a fee the client doesn’t acknowledge, and so forth.
High quality grained means a lot of these 77 classes sound shut sufficient to genuinely confuse a mannequin, which is strictly the property that makes this dataset helpful right here. A mannequin that may solely inform the simple circumstances aside is just not being examined very laborious.
Setup
This undertaking was written and run with Python 3.11 and Weave:
You want an OpenAI software programming interface (API) key, and a free Weights & Biases account for Weave. Run wandb login as soon as within the activated surroundings, or set a WANDB_API_KEY surroundings variable. Save an OPENAI_API_KEY the identical method, both as an surroundings variable or in a .env file subsequent to the script under.
One small model word. This undertaking was run in opposition to weave==0.52.40. Weave printed a discover on each run saying that actual model had been recalled over a technical concern and recommending an improve. The recall didn’t change something within the outcomes right here, however set up the present launch as a substitute of pinning an outdated one, pip set up -U weave, until you’ve got a selected motive to not.
The whole script
Every little thing on this article, the traced software, the 2 variations of its directions, the dataset, the strict rule based mostly grader, the AI grader, and the mannequin comparability, lives in a single script. Put it aside as banking77_regression.py:
Run the steps so as, every one constructing on the outputs of the final:
Every command does one job:
-
fetchdownloads the BANKING77 check questions used within the article. -
smokeruns the primary immediate on six questions so we will catch apparent issues earlier than the total analysis. -
datasetsaves the improved immediate and publishes the reusable Weave Dataset. -
considerruns all three fashions in opposition to the identical 47 questions and information the outputs and scores. -
judge_checkcompares the AI choose with the strict checker. -
refine_judgepublishes a clearer judging rubric and runs the analysis once more. -
judge_check_v2checks whether or not the revised choose now agrees with the strict checker. -
contractcompares the manufacturing stand in and the candidate on actual output necessities. -
sorted_diffskinds mannequin rating variations so the most important modifications are simple to examine first.
The remainder of this text explains what these runs produced, in plain phrases, utilizing the actual output saved alongside the best way.
Why the directions wanted a second model
The smoke step exists for a motive price explaining earlier than anything. Earlier than trusting one set of directions with 47 actual buyer messages throughout three fashions, run it on a small handful first and really learn what comes again.
That first try, PROMPT_V1, informed the mannequin the JSON form and the allowed class labels, but it surely by no means informed the mannequin the rule for deciding needs_human and precedence. It left that judgment name totally as much as the mannequin.
On six smoke check examples, the JSON formatting and the class alternative had been already excellent, 6 out of 6. The escalation determination was right on solely 2 out of 6. The failures weren’t random guesses both.
On the message “I nonetheless haven’t acquired my new card, I ordered over per week in the past,” the right class, a card that has not arrived, is supposed to be dealt with routinely underneath the rule this undertaking defines. The mannequin answered that it wanted a human instantly and marked it medium precedence.
That may be a completely cheap learn of the phrases, the message does sound a bit pissed off. It is usually the fallacious reply for a program that wants one fastened rule utilized the identical method each time, not a rule that shifts relying on tone.
PROMPT_V2 fixes this by spelling the rule out instantly. It names precisely which classes require an individual and excessive precedence, and states that each different class should use low or medium, by no means excessive, irrespective of how the message sounds.
Rerun on the identical six examples, the escalation determination was right on 6 out of 6, with the JSON formatting and class alternative unchanged. Each variations of the directions stayed saved in Weave underneath the identical title, a small immediate registry {that a} reader can open and examine aspect by aspect, not a declare to tackle religion.
Turning actual manufacturing traces into an LLM eval dataset
A Weave Dataset is a saved, versioned listing of rows, and as soon as it exists, a Weave Analysis can run any software in opposition to each row and grade what comes again. This undertaking’s dataset holds 47 actual BANKING77 questions throughout 20 of the dataset’s 77 actual classes.
These 20 weren’t picked at random. They type 5 teams of classes that sound shut sufficient to genuinely confuse a mannequin, card issues, switch issues, refund issues, unrecognized funds, and id checks, plus a couple of standalone safety and billing classes.
23 of the 47 questions are supposed to escalate to an individual underneath the fastened rule, and 24 will not be, a intentionally even break up. Every row carries the actual query textual content, the actual right class, whether or not it ought to escalate, and the total listing of 77 legitimate class labels the mannequin is allowed to select from.
Two totally different graders, checking two various things
Each reply on this undertaking will get graded twice, by two very totally different sorts of checker, and the distinction between them issues for the whole lot that follows. One checker, contract_scorer, follows a set rule with no room for interpretation, the identical method a type processing machine both finds a barcode in the fitting spot or doesn’t.
It parses the uncooked textual content as JSON, tries a few widespread fallback strategies if the primary try fails, after which checks a brief listing of sure or no questions.
Are all 4 fields current? Is the class one of many 77 actual allowed labels? Does it match the right reply? Is the precedence an allowed worth? Does the escalation determination match the rule?
None of that requires judgment. A area is both there or it’s not.
The second checker is a graded AI choose, a separate mannequin name that reads the client’s message, the right reply, the escalation rule, and the primary mannequin’s uncooked response, then fingers again a rating from 0 to 10 with a brief clarification, nearer to a second particular person studying the reply and forming an opinion.
Its scoring guidelines had been written solely after studying actual responses from the smoke check, not guessed prematurely, they usually comply with the identical priorities because the strict checker on function.
Damaged output or a disallowed class caps the rating at 2. A fallacious class or a damaged escalation rule caps it at 5. Solely a response that’s legitimate, accurately labeled, and accurately escalated will get judged on how good the precise reply textual content is.
The choose runs on a separate mannequin, gpt-4.1, one that isn’t any of the three fashions being in contrast, so it’s by no means grading its circle of relatives’s work.
Evaluating three actual LLM mannequin variations
A Weave Analysis ties the dataset, the applying, and each graders collectively in a single run. Three mannequin decisions stand in for an actual AI mannequin choice determination a crew would possibly face:
-
gpt-4o-mini, standing in for an older mannequin nonetheless operating in some legacy code path. -
gpt-4.1-mini, handled right here because the mannequin presently in manufacturing. -
gpt-5-mini, the newer mannequin a crew is contemplating deploying as a substitute.
Operating the total comparability, utilizing the corrected grading guidelines from the subsequent part, produced this actual outcome, computed from all 47 questions per mannequin:
|
what was checked |
older (gpt-4o-mini) |
manufacturing (gpt-4.1-mini) |
candidate (gpt-5-mini) |
|---|---|---|---|
|
legitimate JSON |
1.000 |
1.000 |
1.000 |
|
all 4 fields current |
1.000 |
1.000 |
1.000 |
|
class label allowed |
1.000 |
0.936 |
1.000 |
|
class right |
0.723 |
0.766 |
0.915 |
|
precedence worth allowed |
1.000 |
1.000 |
1.000 |
|
escalation determination right |
0.957 |
0.957 |
0.979 |
|
common AI choose rating (0 to 10) |
6.57 |
7.79 |
9.34 |
|
common reply time (seconds) |
2.13 |
3.11 |
8.86 |
A quantity near 1.000 means almost each one of many 47 solutions handed that examine.
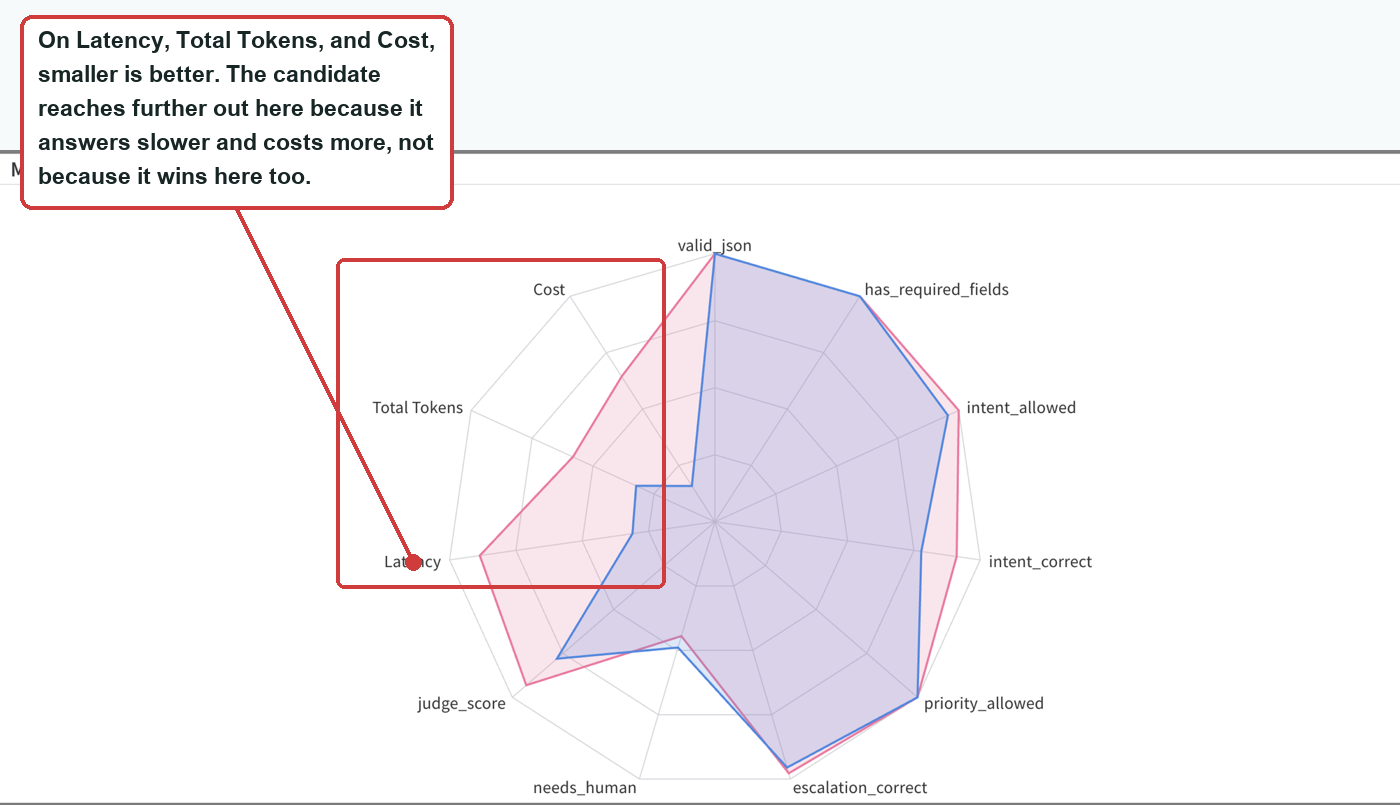
Each certainly one of these runs is seen and comparable in Weave’s personal dashboard.
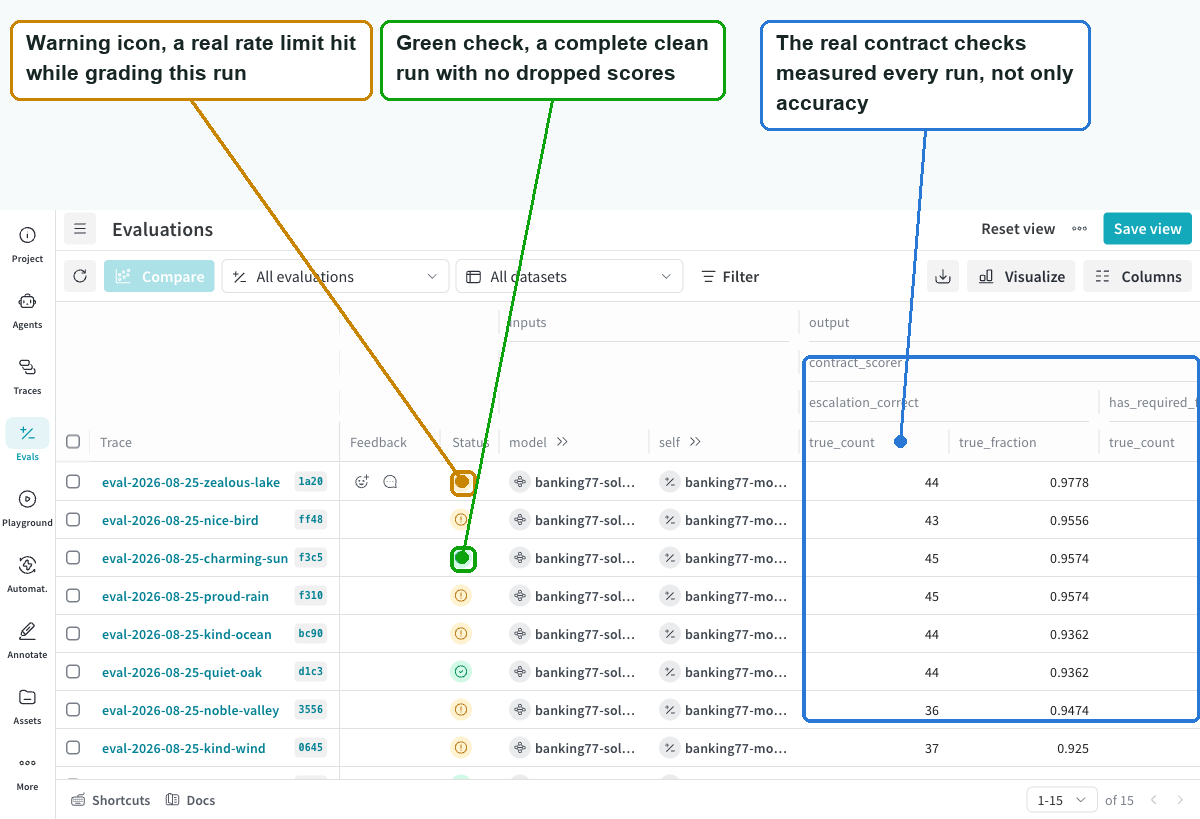
Checking whether or not the AI choose can really be trusted
Earlier than trusting any rating an AI choose fingers out, it helps to examine its work in opposition to one thing that can’t be argued with, which is strictly what the strict rule based mostly checker is for. The primary model of the choose’s scoring guidelines, run in opposition to all three fashions, disagreed with the strict checker 4 occasions on the older mannequin, 3 occasions on manufacturing, and 6 occasions on the candidate.
Each a type of disagreements had the identical form. The choose scored a response as solely partly right though the strict checker mentioned the class and the escalation determination had been each proper.
Studying the choose’s personal written explanations confirmed precisely why. The choose had learn the rule “not escalate, and never use excessive precedence” as if it meant one single particular precedence worth was required, and it was marking a response fallacious only for selecting medium as a substitute of low, though the rule by no means requested for one particular worth between the 2.
That may be a actual, fixable misreading, not a obscure sense that one thing was off.
The corrected model of the principles, JUDGE_PROMPT_V2, states plainly that low and medium are each right for a routine case, and neither counts as a mismatch. Rerunning the identical 47 questions per mannequin in opposition to the corrected choose dropped the disagreements to zero for the older mannequin and the candidate mannequin.
Manufacturing nonetheless confirmed 4 disagreements afterward, and it will have been simple to imagine the choose merely wanted yet one more repair. It didn’t. Studying these 4 circumstances one after the other turned up one thing else totally, which is the precise level of the subsequent part.
Sorting by the dimensions of the disagreement as a substitute of studying each reply
Forty seven questions throughout three fashions provides as much as 141 separate graded solutions, greater than anybody desires to learn line by line. Sorting by how far aside two fashions’ scores are turns that pile into a brief listing, price beginning with the most important disagreements and dealing down from there.
Sorting the older and candidate fashions this fashion places a number of excellent swings on the high, the older mannequin scoring 3 out of 10, the candidate scoring 10 out of 10, on the very same query.
Considered one of them exhibits the sample clearly. For the message “How do I find my card?”, the right class is a card that has not arrived but. The older mannequin, gpt-4o-mini, answered with a special, actual class about linking a card, a genuinely believable misreading in case you are not holding the total listing of 77 labels in entrance of you, the phrase “find” does sound a bit like a linking query out of context.
The newer mannequin, gpt-5-mini, answered accurately. Nothing about this pair has something to do with formatting. Each solutions had been legitimate JSON with all 4 fields current.
This distinction is about which mannequin really understood the message accurately, on a dataset constructed particularly to incorporate classes that sound alike.
What really occurred when manufacturing was examined in opposition to the candidate
That is the comparability the entire undertaking was actually constructed for. Deal with gpt-4.1-mini because the mannequin presently in manufacturing, and gpt-5-mini because the candidate being thought of to switch it, then examine each measurement, not solely the general choose rating.
The candidate matched or beat manufacturing on each single one, together with each formatting examine. Neither mannequin ever produced invalid JSON or overlooked a area, each had been excellent there.
However the row for allowed class labels tells a special story. Manufacturing scored 0.936. Each different fashions scored an ideal 1.000. Manufacturing is the one with an actual formatting downside right here, not the candidate.
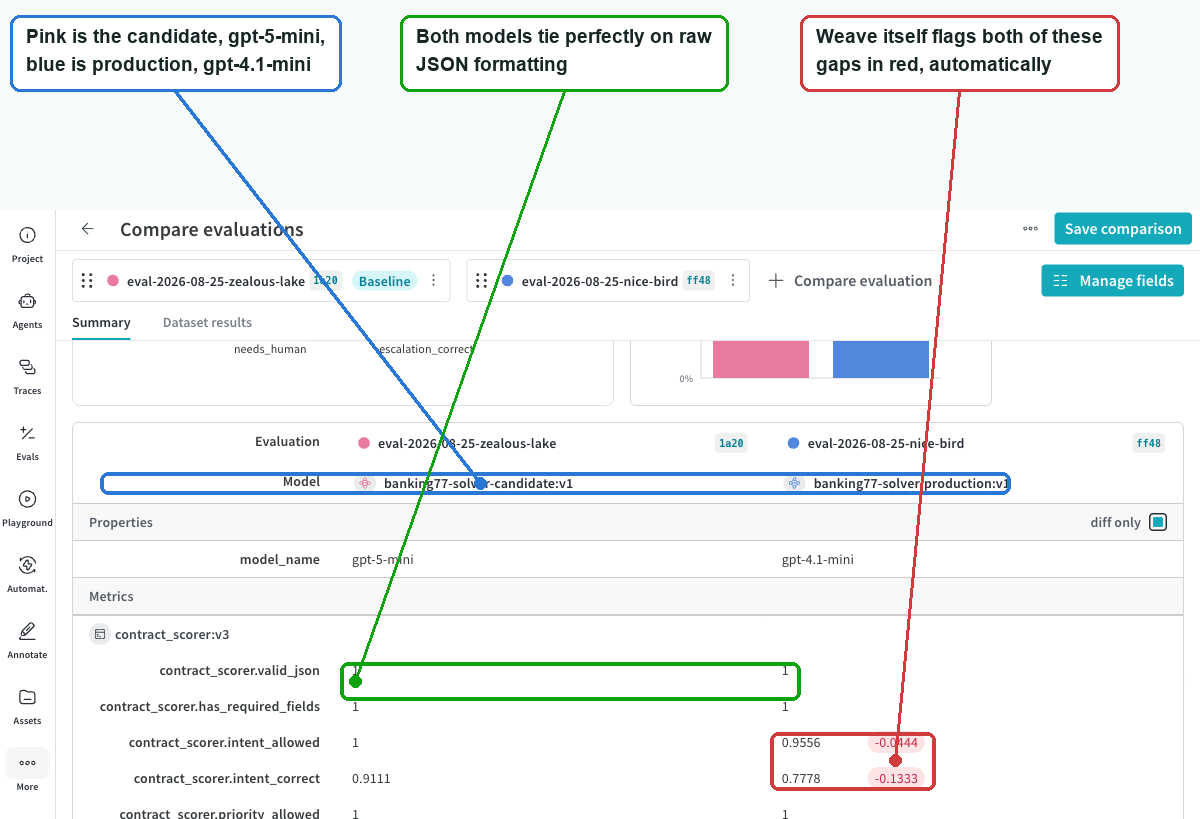
The trigger is restricted, and it repeats identically throughout each refund query within the pattern. On three separate actual buyer messages, all asking a few refund, gpt-4.1-mini answered with the class spelled "Request_refund", a capital R.
The true BANKING77 label, and the worth written in each row of the dataset, is lowercase, request_refund. A program checking that label the best way actual software program really does, an actual match, would silently fail to route each single certainly one of these tickets, though the reply textual content beneath reads simply tremendous.
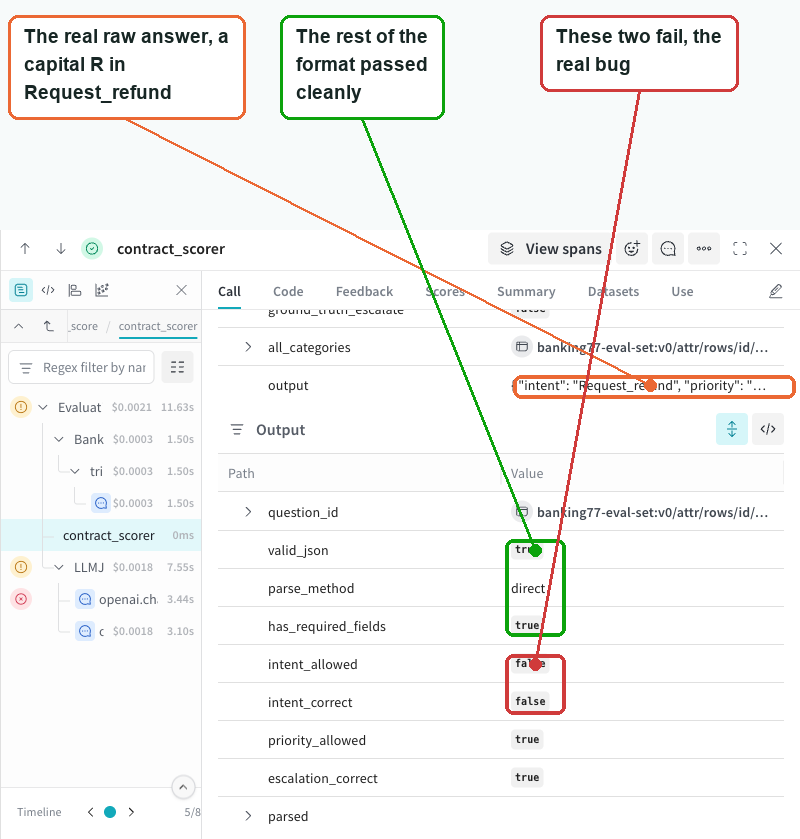
The AI choose gave that response a 9, and its personal written clarification mentioned plainly, “the right intent (case sensitivity is just not penalized),” naming the precise factor it was selecting to disregard. The strict checker disagreed, accurately, as a result of "Request_refund" merely is just not one of many 77 actual class labels in any respect, and an actual match examine is exactly what routing code in an actual system really runs.
The identical capital R behavior confirmed up on two different actual refund questions within the pattern, not solely this one, and each gpt-4o-mini and gpt-5-mini wrote the right lowercase label on all three.
This one particular behavior is an actual, already delivery formatting bug within the mannequin presently in manufacturing. The candidate didn’t introduce it. It was solely seen in any respect as a result of one thing else existed to check it in opposition to.
This deserves to be mentioned plainly, because the sincere outcome issues greater than a tidy one. This undertaking didn’t discover the sample it set out in search of. The candidate by no means broke a rule manufacturing was following accurately.
The undertaking nonetheless earned its value, as a result of a check constructed to catch a brand new downside caught an outdated one as a substitute, on a bug an individual skimming the reply would by no means discover, because the reply itself reads as utterly right.
Yet another actual case is price together with exactly as a result of it complicates the story as a substitute of wrapping it up neatly. For the message “The place can I view my PIN?”, the right class ought to have triggered escalation.
All three fashions, together with the newer one, answered with a special class about altering a PIN, and marked it as not needing an individual, an affordable sounding guess that misses the purpose. It’s the solely query in the entire pattern the place the newer mannequin acquired each the class and the escalation determination fallacious without delay.
Studying the message once more, it genuinely reads extra like a request to view or change a PIN than a report of 1 being blocked, which is price treating as a potential labeling query within the unique dataset, not solely a shared mannequin mistake.
An identical case turned up contained in the 4 leftover choose disagreements on manufacturing. One buyer described a declined card buy, and the dataset’s personal reply for that query was a class a few declined switch, whereas gpt-4.1-mini answered with a special, actual, defensible class a few declined card fee.
Public datasets are constructed by folks, and their labels will not be past query. An sincere undertaking says so when it finds a case like that, as a substitute of quietly counting it as yet one more mannequin mistake.
The total loop, and what it doesn’t show
Put collectively finish to finish, this undertaking is one repeatable loop for regression testing an LLM earlier than it replaces one already in manufacturing. Hint a small actual software with Weave. Repair its directions as soon as an actual smoke check finds an actual hole.
Flip actual traces right into a dataset. Construct two graders, one strict and one which reads for which means, and examine them in opposition to one another. Run a full comparability throughout three fashions.
Type the outcomes by how a lot they disagree as a substitute of studying each row. Lastly, run the one comparability an actual deployment determination really depends upon, the mannequin already stay in opposition to the one being thought of to switch it.
One sincere query stays open, and it’s price sitting with reasonably than resolving too neatly. The AI choose learn straight previous the capital letter distinction in Request_refund as a result of it was grading for which means, and the strict checker caught it as a result of it was not. That hole, a choose that reads extra kindly than the precise rule an actual system depends upon, is near unavoidable for any grader constructed to learn like an individual.
If a undertaking solely had an AI choose, with no strict rule based mostly checker operating alongside it, how would anybody ever catch a bug like this one, a solution that appears clearly right and is silently, mechanically fallacious beneath?
What this particular undertaking did show is narrower than a verdict on which mannequin is best typically, and extra helpful due to it. On one small software, throughout 47 actual buyer messages, the newer mannequin by no means misplaced to the one already operating in manufacturing, on formatting or on accuracy.
Essentially the most helpful factor this undertaking discovered was probably not concerning the future mannequin being thought of in any respect. It was concerning the one already stay, and the one motive to see it was constructing one thing to check it in opposition to.
Sources
-
Iñigo Casanueva, Tadas Temcinas, Daniela Gerz, Matthew Henderson, and Ivan Vulić, Efficient Intent Detection with Dual Sentence Encoders, Proceedings of the 2nd Workshop on Pure Language Processing (NLP) for Conversational AI, Affiliation for Computational Linguistics (ACL), 2020. Introduces the actual BANKING77 dataset used all through this text.
-
Sijie Yan, Yuanjun Xiong, Kaustav Kundu, Shuo Yang, Siqi Deng, Meng Wang, Wei Xia, and Stefano Soatto, Positive-Congruent Training: Towards Regression-Free Model Updates, Convention on Laptop Imaginative and prescient and Sample Recognition (CVPR), 2021. Introduces the unfavorable flip, the discovering that motivated this undertaking’s unique speculation.
-
OpenAI, Introducing Structured Outputs in the API, official product announcement. The supply for this text’s opening declare concerning the unreliability of plain prompted JSON.
-
Weights & Biases, Store and track versions of prompts, Weave documentation.
-
Weights & Biases, Build an evaluation, Weave documentation.
-
Weights & Biases, Track application versions with models, Weave documentation.