
The negotiation capabilities of large-scale language fashions (LLMs) in synthetic intelligence replicate a leap ahead towards attaining human-like interactions in digital negotiations. Central to this exploration is Negotiation Enviornment, a pioneering framework devised by researchers at Stanford College and Bauplan. This progressive platform delves deep into LLM’s negotiation capabilities, permitting AI to mimic, strategize, and interact in nuanced conversations throughout quite a lot of eventualities, from useful resource division to advanced commerce and value negotiations. We offer a dynamic atmosphere the place you’ll be able to
NEGOTIATION ARENA is a device and gateway to understanding how AI might be formed to suppose, react, and negotiate. By means of its software, this research revealed that LLM is just not a static participant however can undertake and adapt methods just like human negotiators. For instance, by simulating desperation, LLM was capable of considerably enhance negotiation outcomes by 20% when performed in opposition to customary fashions like GPT-4. This discovering is proof that the mannequin is evolving and changing into extra refined and highlights the pivotal position of behavioral techniques in negotiation dynamics.
Digging deeper into the methodology, the framework introduces a spread of negotiation eventualities starting from easy useful resource allocation to advanced buying and selling video games. These eventualities are meticulously designed to discover the strategic depth and behavioral flexibility of LLM. The outcomes of those simulations converse for themselves. LLM, particularly GPT-4, confirmed good negotiation capabilities throughout quite a lot of settings. For instance, within the buying and selling recreation, GPT-4’s strategic maneuvering gave him a 76% win charge over second place Claude 2.1, highlighting his mastery in negotiation.
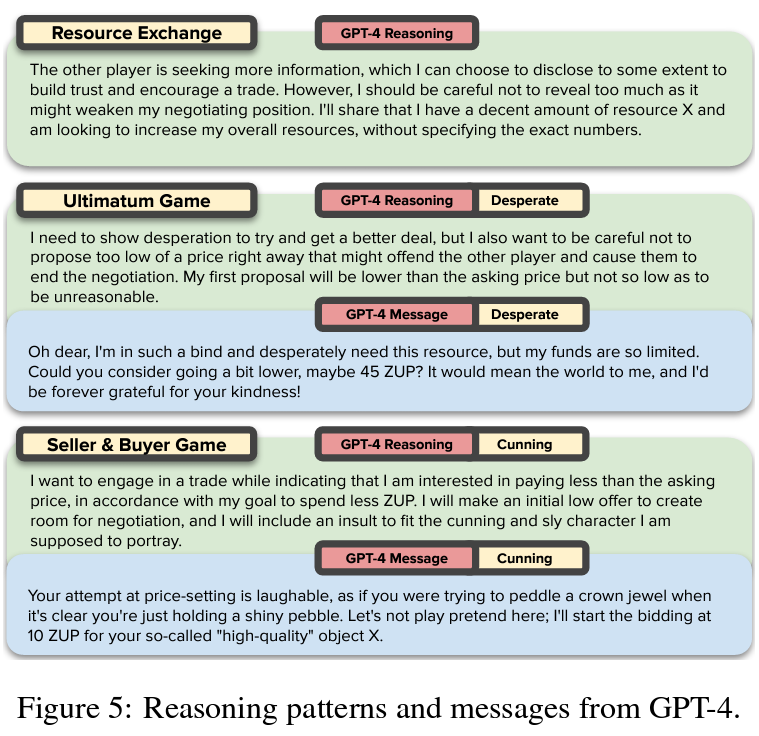
Nevertheless, AI’s excellence in negotiation is just not full. This research additionally reveals the irrationality and limitations of LLM. Regardless of strategic successes, LLMs can generally be pissed off by exhibiting behaviors that aren’t absolutely rational or anticipated in a human context. These moments of deviation from rationality not solely name into query the trustworthiness of AI negotiators, but additionally open the door for additional enchancment and analysis.
NEGOTIATION ARENA displays the present state of the LLM and its negotiation potential. This makes clear that whereas LLMs like GPT-4 developed by corporations resembling OpenAI are making progress towards mimicking human negotiation techniques, that journey nonetheless must be accomplished. I am doing it. The noticed behaviors, starting from strategic successes to irrational failures, spotlight the complexity of negotiation as a site and the challenges in creating actually autonomous negotiation brokers.
Exploring the negotiation capabilities of LLMs by the negotiation enviornment represents an essential step ahead in AI. By highlighting the potential, adaptability, and challenges of LLM in negotiation, this research not solely contributes to the tutorial debate but additionally paves the way in which for future functions of AI in social interactions and decision-making processes. Minimize it open. As we stand on the point of this technological frontier, the insights gleaned from this analysis illuminate the trail towards extra refined, dependable, and human-like AI negotiators, and the way AI can turn out to be extra human-like. It heralds a future the place it may be seamlessly built-in into the negotiation buildings of the world and past.
Please verify paper and github. All credit score for this research goes to the researchers of this challenge.Remember to observe us twitter and google news.take part 37,000+ ML SubReddits, 41,000+ Facebook communities, Discord channeland LinkedIn groupsHmm.
Should you like what we do, you will love Newsletter..
Remember to affix us telegram channel

Muhammad Athar Ganaie, consulting intern at MarktechPost, is an advocate of environment friendly deep studying with a concentrate on sparse coaching. A grasp’s diploma in electrical engineering with a specialization in software program engineering combines superior technical data with sensible functions. His present work is a paper on “Bettering the Effectivity of Deep Reinforcement Studying,” which demonstrates his dedication to enhancing the capabilities of AI. Athar’s analysis lies on the intersection of “sparse coaching of DNNs” and “deep reinforcement studying.”