
Tremendous-tuning is the method of constant to coach a pretrained massive language mannequin (LLM) on an organization’s personal information so it adapts to a particular area, job, or fashion slightly than counting on general-purpose data alone. For companies, the worth is twofold. A fine-tuned mannequin delivers measurably higher accuracy on domain-specific work whereas decreasing prices: a smaller specialised mannequin can match or exceed a frontier mannequin in your job at a fraction of the per-token inference value. These financial savings compound throughout thousands and thousands of requests. Tremendous-tuning has subsequently turn into a vital course of for companies trying to get extra worth from LLMs at decrease prices.
Parameter-efficient fine-tuning (PEFT) strategies like Low-Rank Adaptation (LoRA) have emerged as a sensible resolution for fine-tuning LLMs to downstream duties, decreasing GPU capability necessities by updating solely a small subset of LLM parameters. LoRA goals to strike a stability between effectivity and expressiveness, nonetheless, the low-rank nature of the load replace inherently limits the illustration energy of LoRA fine-tuned fashions, doubtlessly compromising efficiency on complicated duties. This trade-off hampers the power of LoRA strategies to seize complicated patterns wanted for numerous duties. To handle these challenges, Full Tremendous-Tuning (FFT) updates mannequin parameters concurrently, overcoming the low-rank limitations so LLMs can absolutely soak up complicated domain-specific data.
Amazon SageMaker AI Serverless Mannequin Customization now helps Full Tremendous-Tuning (FFT), so you may obtain superior mannequin high quality with out managing infrastructure. There isn’t any GPU provisioning, cluster setup, or distributed-training configuration required. On this submit, we discover when and the place FFT persistently outperforms LoRA throughout key benchmarks, look at the spectral properties of mannequin weight matrices that designate this high quality hole, present sensible hyperparameter tuning tips backed by managed experiments utilizing SageMaker AI Serverless Mannequin Customization, and present you the best way to get began with FFT on SageMaker AI.
Full Tremendous-Tuning: Why it issues
Mannequin customization varieties like LoRA scale back trainable parameters by freezing the pre-trained mannequin’s weights and injecting small, separate pairs of substitute matrices (referred to as low-rank matrices) into the mannequin layers. This works nicely for easy variations, however the low-rank construction inherently limits the illustration energy of the fine-tuned mannequin. As duties develop extra complicated and datasets scale past tens of 1000’s of examples, LoRA hits an accuracy plateau the place rising rank (and thus trainable parameters) fails to bridge the accuracy hole with customary fine-tuning. This plateau reveals that the efficiency hole isn’t merely due to fewer parameters. It’s attributable to rank deficiency itself. The low-rank replace can’t seize the total complexity of the load adjustments wanted for deep job adaptation.
Nonetheless, for complicated duties and domains the place massive, good-quality datasets exist, full-rank fine-tuning excels by updating mannequin parameters concurrently. FFT modifies the mannequin’s weight matrix uniformly, utilizing the total representational capability of the mannequin’s weight matrices slightly than proscribing updates to a small subspace, and with out introducing the abrupt, localized distortions attribute of low-rank strategies. The result’s stronger mannequin convergence, higher activation alignment throughout mannequin layers, and a mannequin that faithfully captures each the goal job distribution and the richness of its pre-trained data. FFT’s high quality benefit grows with dataset scale: at 100K+ coaching examples, FFT achieved 90.0 p.c on LLM-as-Decide semantic correctness throughout code technology duties, as proven within the following chart.
Determine 1: LLM-as-Decide semantic correctness by coaching technique as coaching information scales to 100K+ examples
Moreover, the next radar chart supplies a holistic view: the bottom mannequin (internal polygon) reveals persistently low scores throughout all axes. LoRA (center polygon) reveals sturdy, balanced enchancment. FFT (outer polygon) extends additional on each dimension, with notably pronounced leads on BLEU and ROUGE-2 scores. This multi-dimensional high quality lead confirms that it isn’t a metric-specific artifact however a elementary benefit of full-rank optimization.
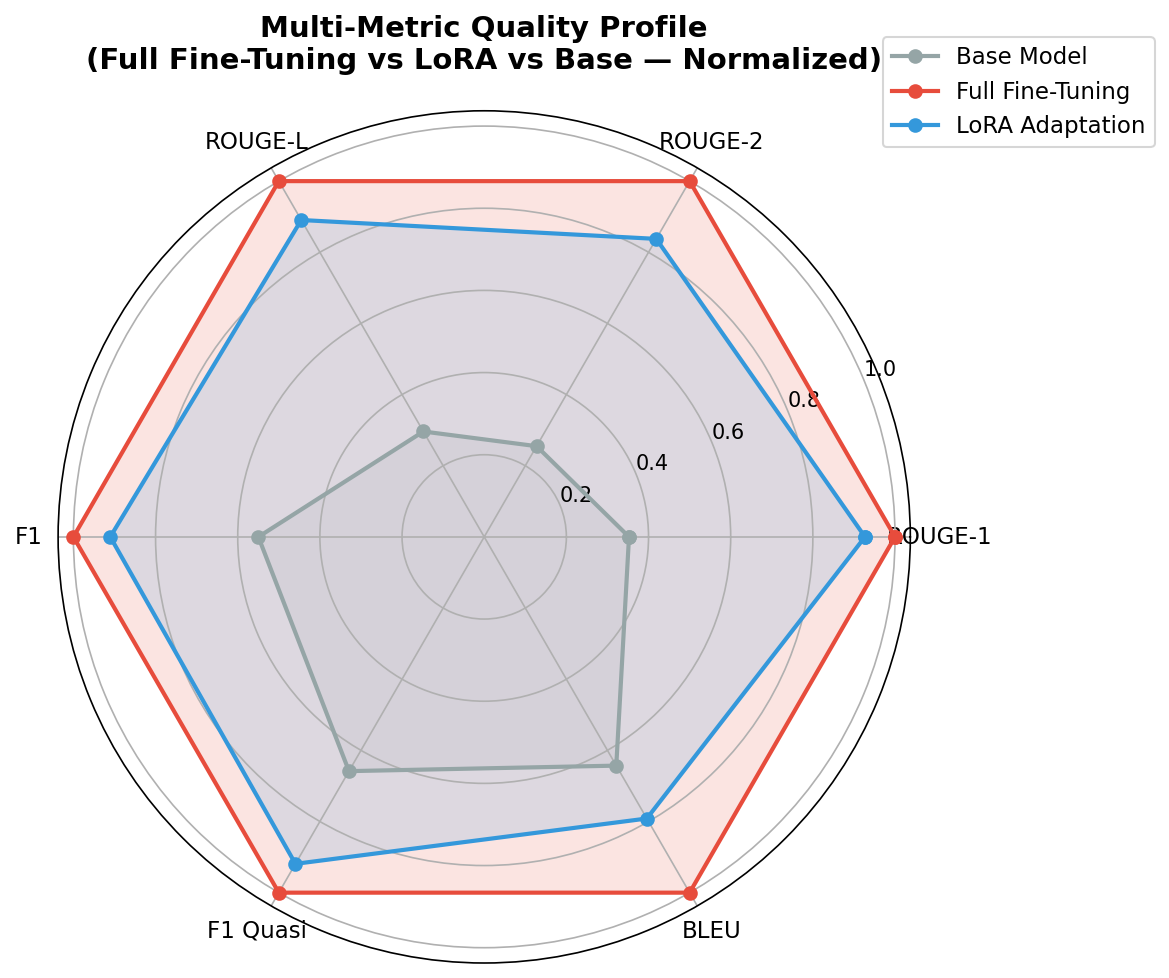
Determine 2: Radar chart evaluating the bottom mannequin, LoRA, and FFT throughout high quality dimensions
The small print of how we arrived at these outcomes, the coding datasets used for mannequin customization, and the experimentation course of are defined intimately within the following sections.
Experimentation and benchmark outcomes
On this submit we used the Supervised Tremendous-Tuning (SFT) method on a Qwen3-4B base mannequin provided inside Amazon SageMaker AI Studio and carried out all of the fine-tuning experiments utilizing SageMaker AI Serverless Mannequin Customization throughout LoRA and FFT coaching strategies. Inside every experiment, each strategies obtained the identical prompts, targets, and analysis code.
Dataset: Code technology 110K instruction pairs
For all of the experimentation, we fine-tuned the Qwen3-4B base mannequin on the Magicoder-Evol-Instruct-110K dataset, a curated corpus of 110,000 coding instruction-response pairs spanning algorithm design, debugging, information constructions, and methods programming. We utilized a 90/5/5 cut up to the dataset: 99,000 information for coaching, 5,500 for validation to watch convergence and coaching loss in the course of the customization job, and 5,500 reserved as a held-out take a look at set for unbiased analysis of the ultimate mannequin, as registered in SageMaker AI dataset belongings and proven within the following determine.
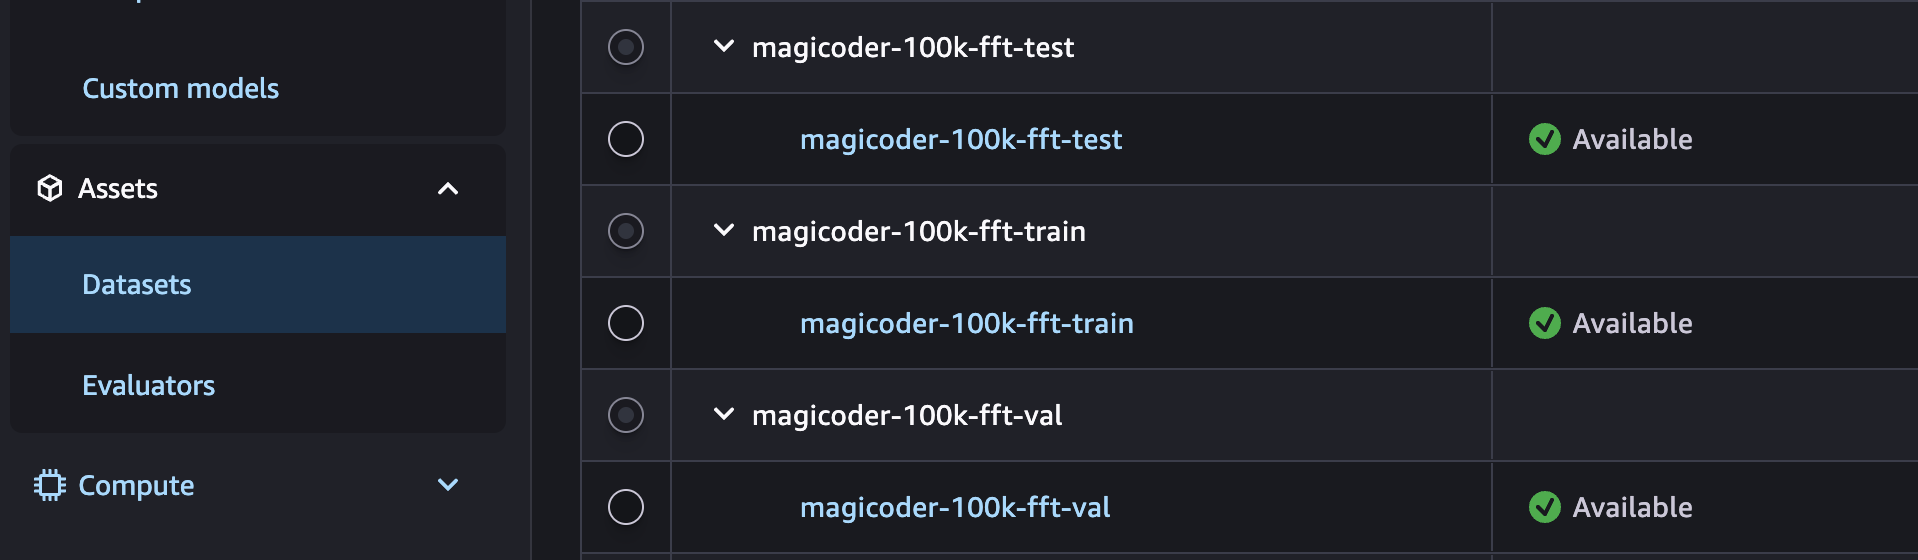
Determine 3: The 110K instruction-pair dataset registered in SageMaker AI dataset belongings
Serverless Mannequin Customization job
All of the mannequin customization experiments on this submit had been carried out on Amazon SageMaker AI Serverless Mannequin Customization. Serverless Mannequin Customization on SageMaker AI lets information scientists and machine studying (ML) engineers deal with mannequin fine-tuning with out managing infrastructure or GPU capability planning. You specify the bottom mannequin, dataset, and hyperparameters, and the service handles compute allocation and checkpoint administration robotically in a serverless vogue. The next code snippet reveals one such experiment for launching a Full Tremendous-Tuning (FFT) job on Serverless Mannequin Customization utilizing the SageMaker Python SDK.
The code triggers a serverless mannequin customization job, proven within the following screenshot, with coaching efficiency metrics tracked within the job and viewable within the linked MLflow app.
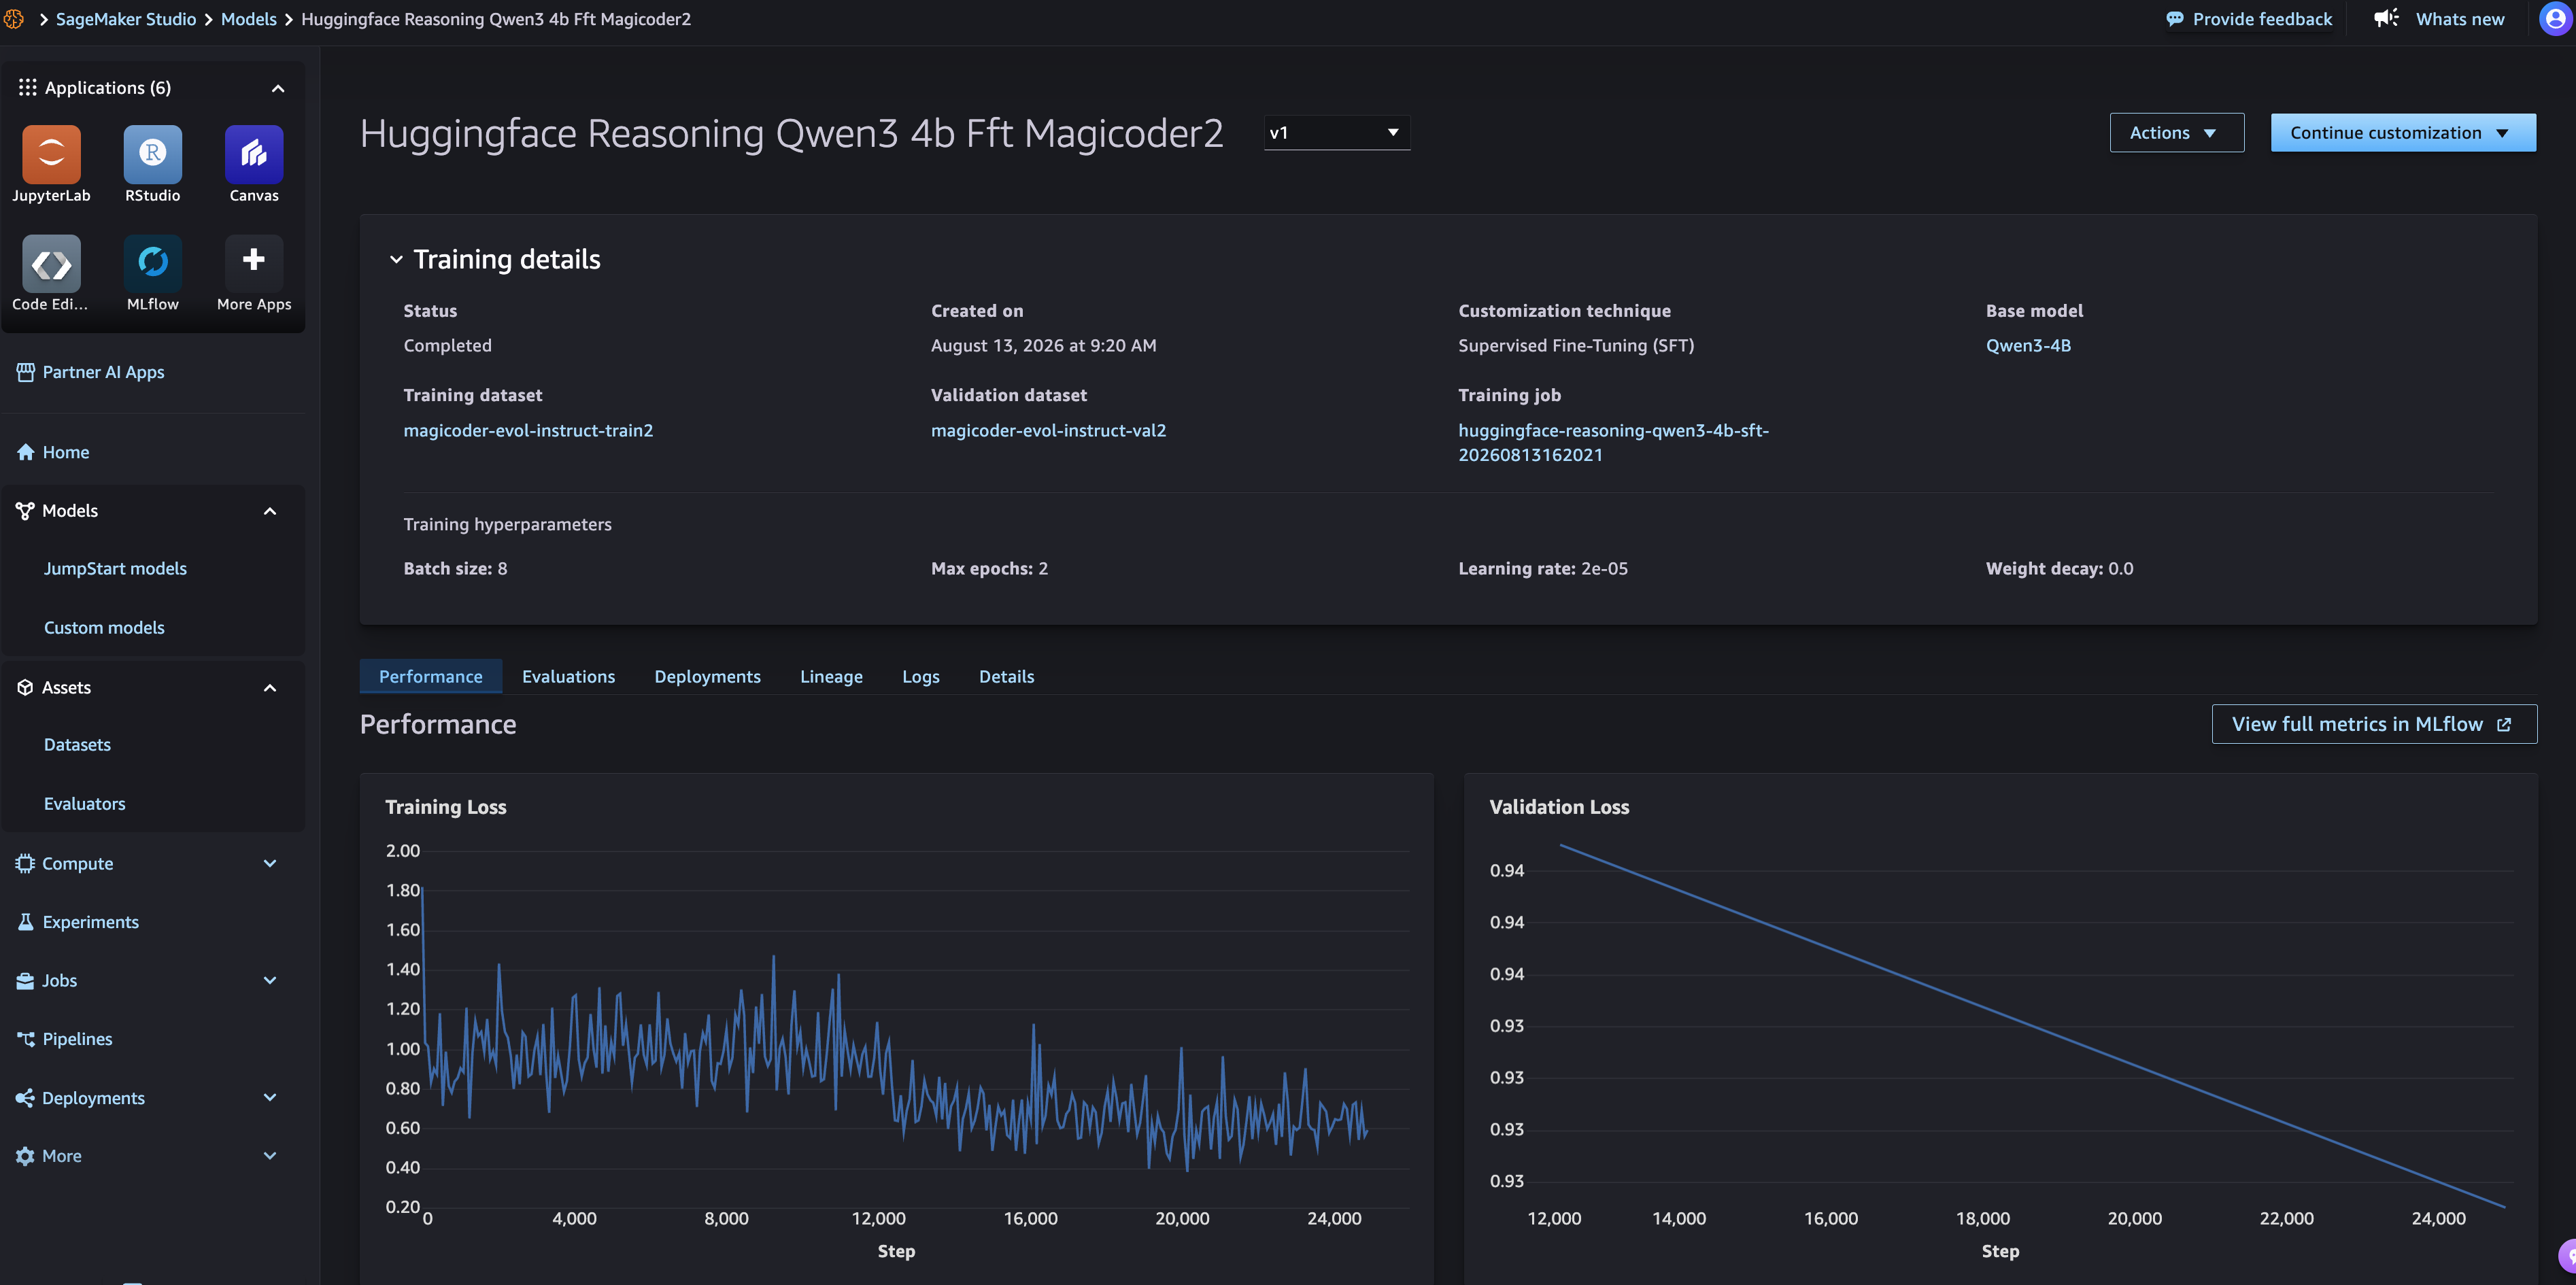
Determine 4: Serverless mannequin customization job with coaching metrics tracked in MLflow
Switching from Full Tremendous-Tuning to LoRA requires just one change: set TrainingType.FULL to TrainingType.LORA. The remainder of the code stays equivalent:
Mannequin analysis and benchmarking
We examined the ensuing personalized fashions throughout three numerous analysis strategies constructed into SageMaker AI Serverless Mannequin Customization: LLM-as-Decide, PRIMECODE, and MMLU, proven within the following picture. Every targets a special dimension of mannequin high quality: semantic correctness, code technology constancy, and basic data retention. Collectively they supply a complete image of the mannequin customization high quality.
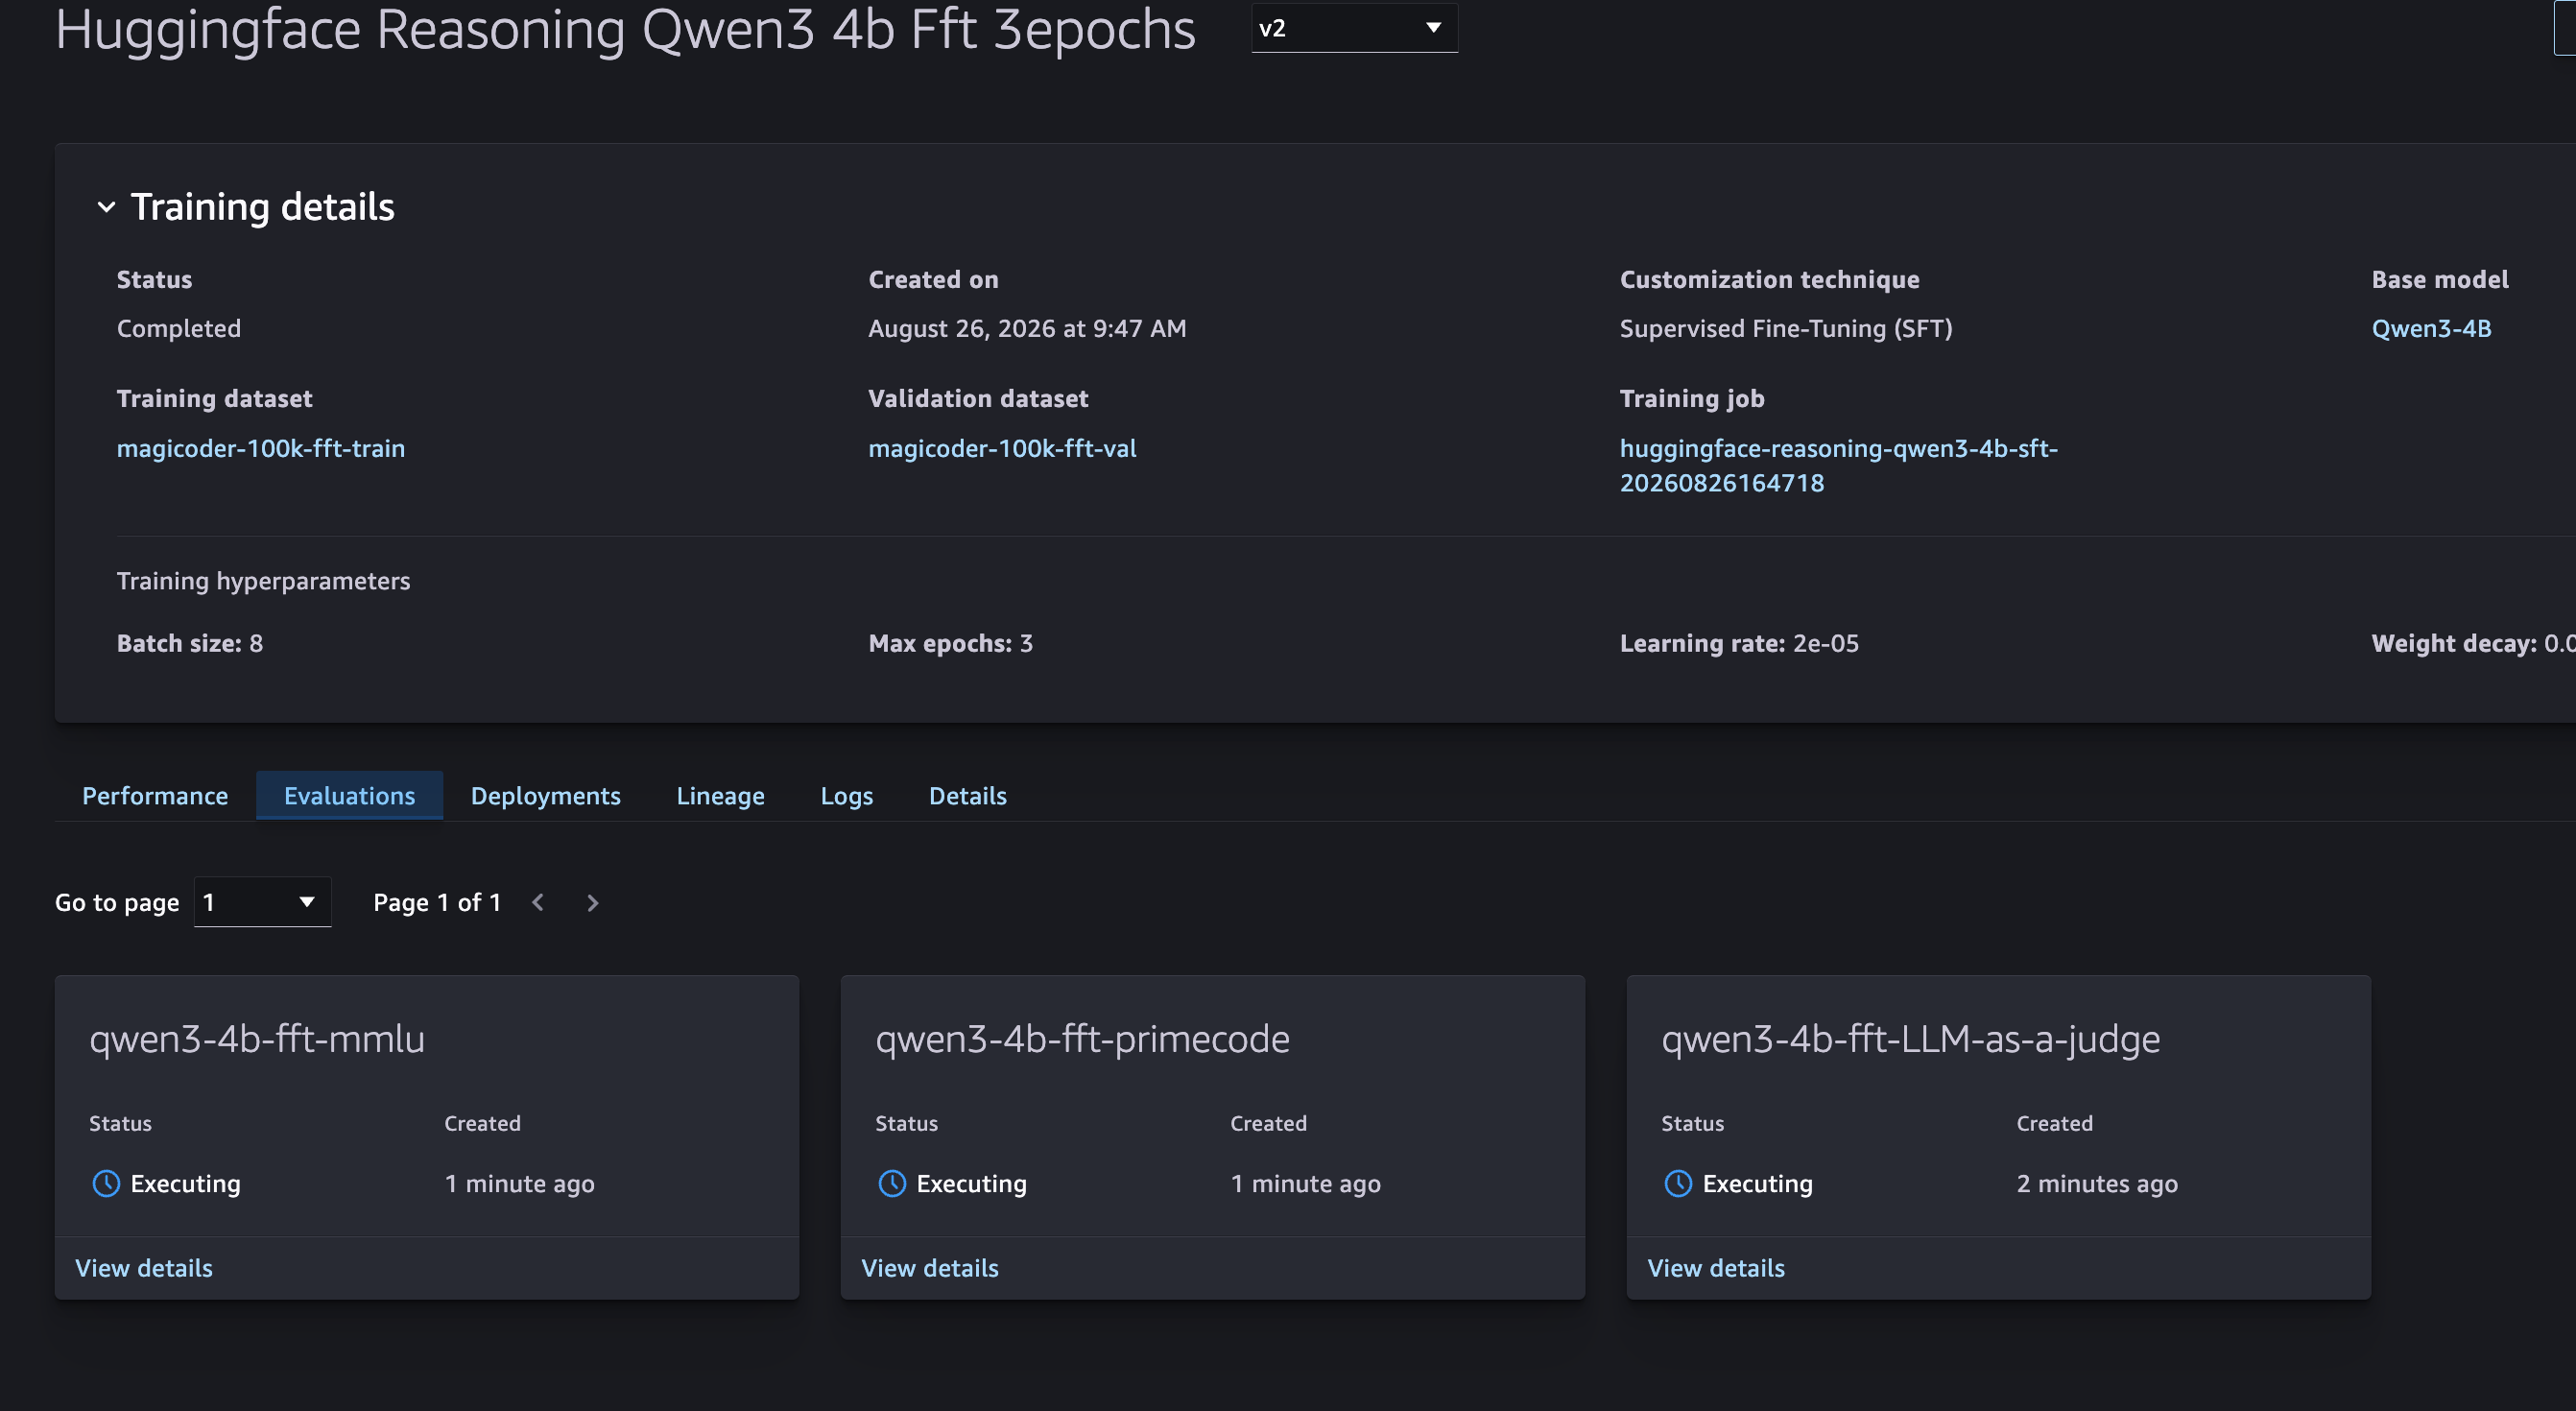
Determine 5: The three built-in analysis strategies in SageMaker AI Serverless Mannequin Customization
The LLM-as-Decide metric makes use of a frontier mannequin (on this submit, Amazon Nova Professional) as an automatic evaluator that reads the mannequin’s generated code alongside the unique immediate and judges whether or not the answer is logically right. On serverless mannequin customization you may consider each the personalized mannequin alongside the bottom mannequin, as proven within the following determine.
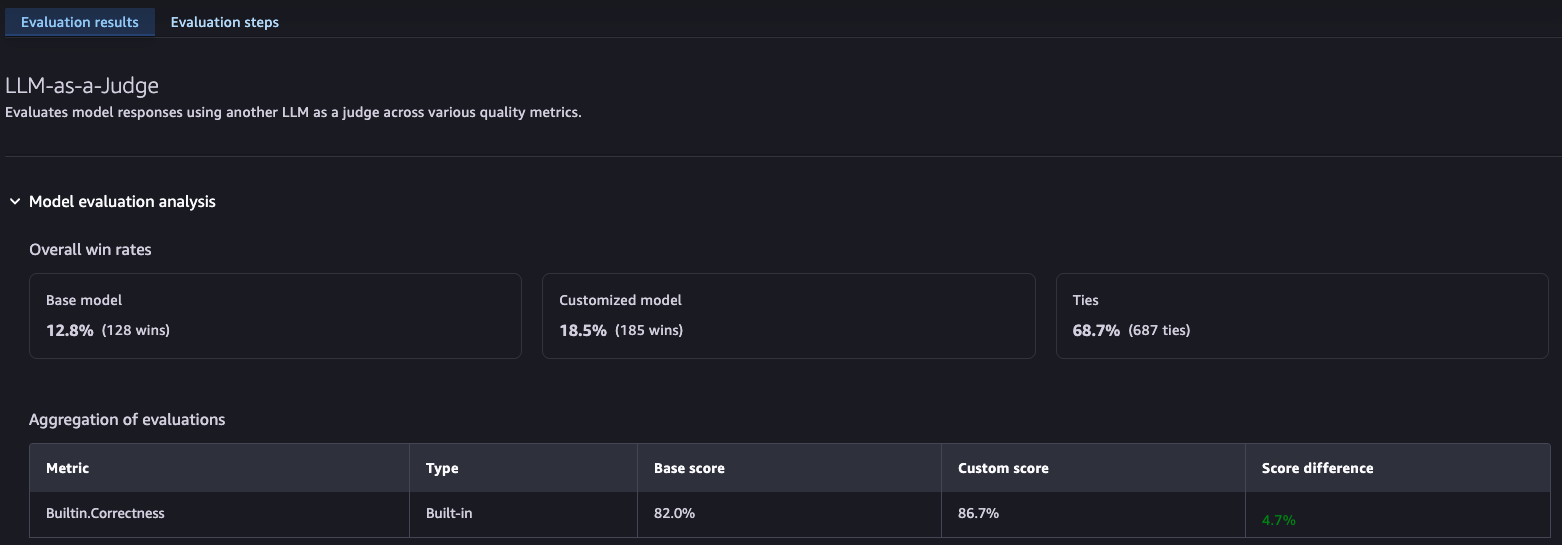
Determine 6: LLM-as-Decide analysis evaluating the personalized mannequin and the bottom mannequin
PRIMECODE is a customized scorer analysis that measures how carefully the mannequin’s generated code matches reference options utilizing deterministic text-similarity metrics: BLEU (n-gram precision), ROUGE-1/2/L (recall-oriented overlap), and F1 (precision-recall stability). These metrics are absolutely reproducible, making them excellent for managed ablation research. We used PRIMECODE as our major metric for surface-level code high quality as a result of it quantifies how nicely the mannequin has realized the coding patterns, formatting conventions, and implementation fashion current within the coaching information. A excessive BLEU rating means the mannequin generates code that appears structurally much like expert-written options, as proven within the following outcomes.
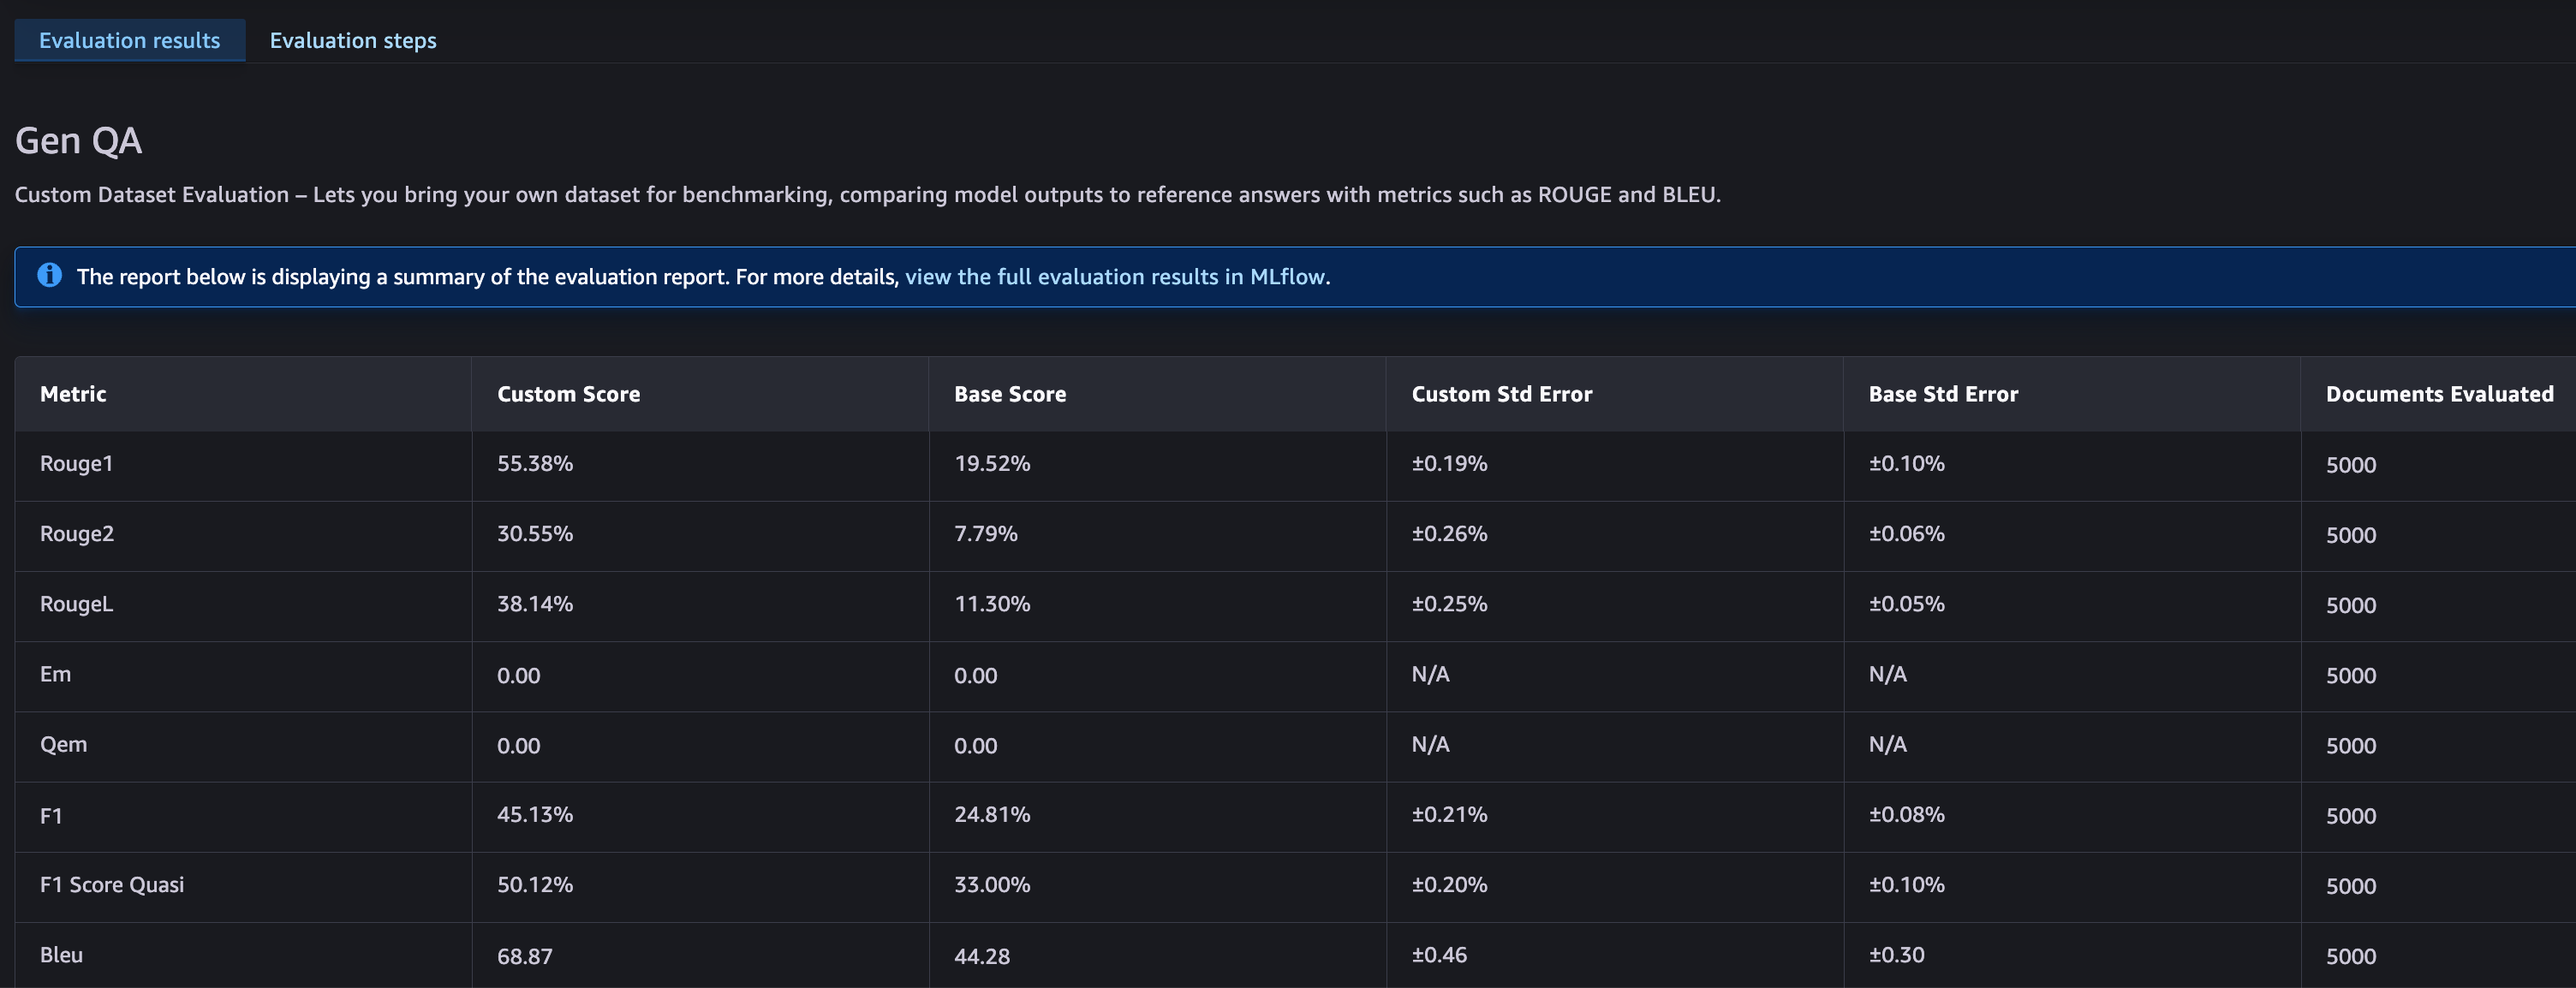
Determine 7: PRIMECODE text-similarity scores for the personalized mannequin
MMLU (Large Multitask Language Understanding) is a built-in benchmark that checks the mannequin throughout 57 educational topics from summary algebra and anatomy to Diet and Philosophy. It measures whether or not the mannequin retains its broad basic data after domain-specific fine-tuning, as proven within the following determine. We used MMLU as our forgetting detection guardrail. Tremendous-tuning on code can overwrite basic capabilities saved within the mannequin’s weights. By monitoring MMLU accuracy earlier than and after fine-tuning, we will quantify precisely how a lot basic data the mannequin sacrifices for code technology enchancment, and whether or not our hyperparameter selections speed up or mitigate this trade-off.
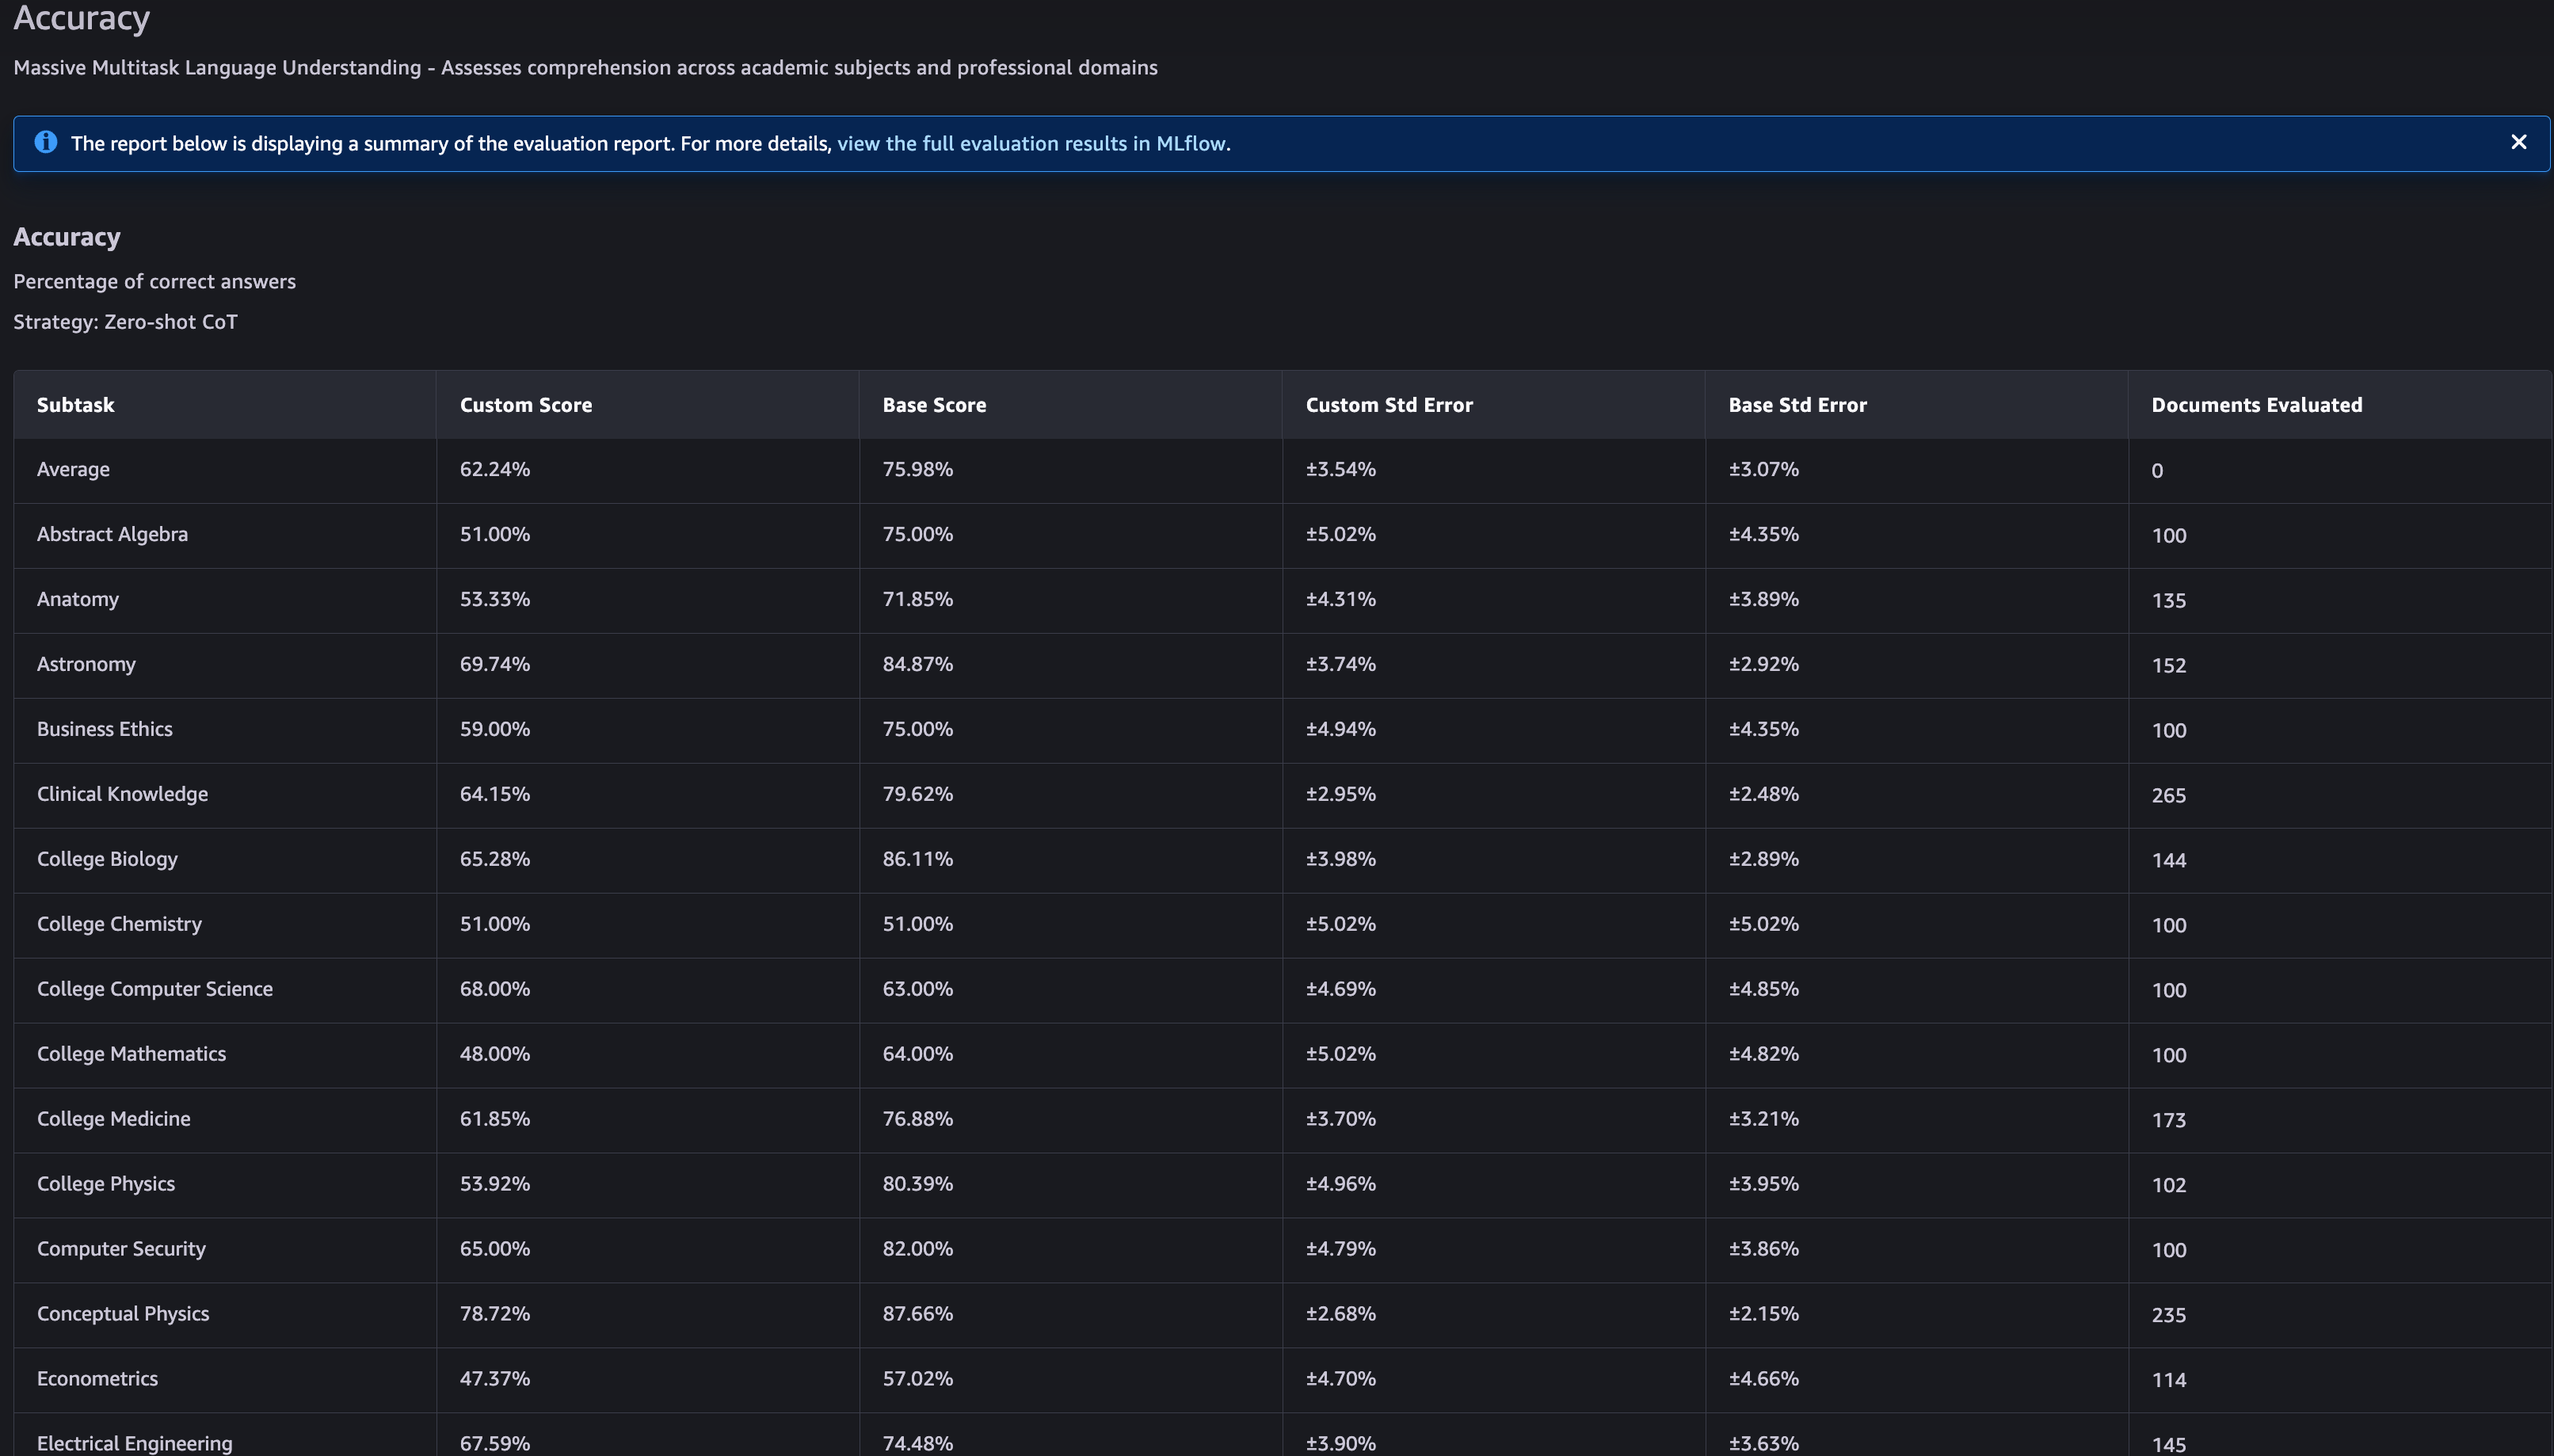
Determine 8: MMLU accuracy earlier than and after fine-tuning
Speedy experimentation at scale
The convenience of setup and use of SageMaker AI Serverless Mannequin Customization allow us to carry out speedy experimentation with out re-provisioning infrastructure. We modified coaching varieties between LoRA and FFT, swept hyperparameters, and examined throughout a number of base fashions. Over a short while window, we ran tens of mannequin customization experiments throughout a number of supported base fashions (Qwen3-4B, DeepSeek-R1-1.5B, Nemotron-30B, Gemma-4-26B), systematically ablating studying charge, batch dimension, warmup ratio, epoch rely, and dataset scale. Every experiment, from job submission to analysis outcomes, accomplished in a couple of hours and the ensuing fine-tuned fashions had been robotically registered in SageMaker Mannequin Registry as versioned Mannequin Packages, prepared for assessment or deployment.
Hyperparameter choices
SageMaker AI Serverless Mannequin Customization helps many hyperparameters. On this part, we clarify a couple of vital ones, knowledgeable by the collection of experiments that we ran throughout a number of hyperparameter configurations inside the beforehand talked about code technology job. Whereas efficient values will differ by job, the patterns noticed throughout these experiments present helpful beginning factors when configuring FFT mannequin customization jobs. For extra details about the hyperparameters which you can configure earlier than launching an FFT mannequin customization job, see the hyperparameters documentation web page.
1. learning_rate
In full fine-tuning, the training charge controls how aggressively each weight is up to date. Not like LoRA, the place solely small adapter matrices change, an FFT studying charge that’s too excessive completely overwrites pretrained data. In our experiments, the next LR × dataset-size threat map reveals that an LR of 2e-5 on a big dataset (over 100 thousand) was the protected zone.
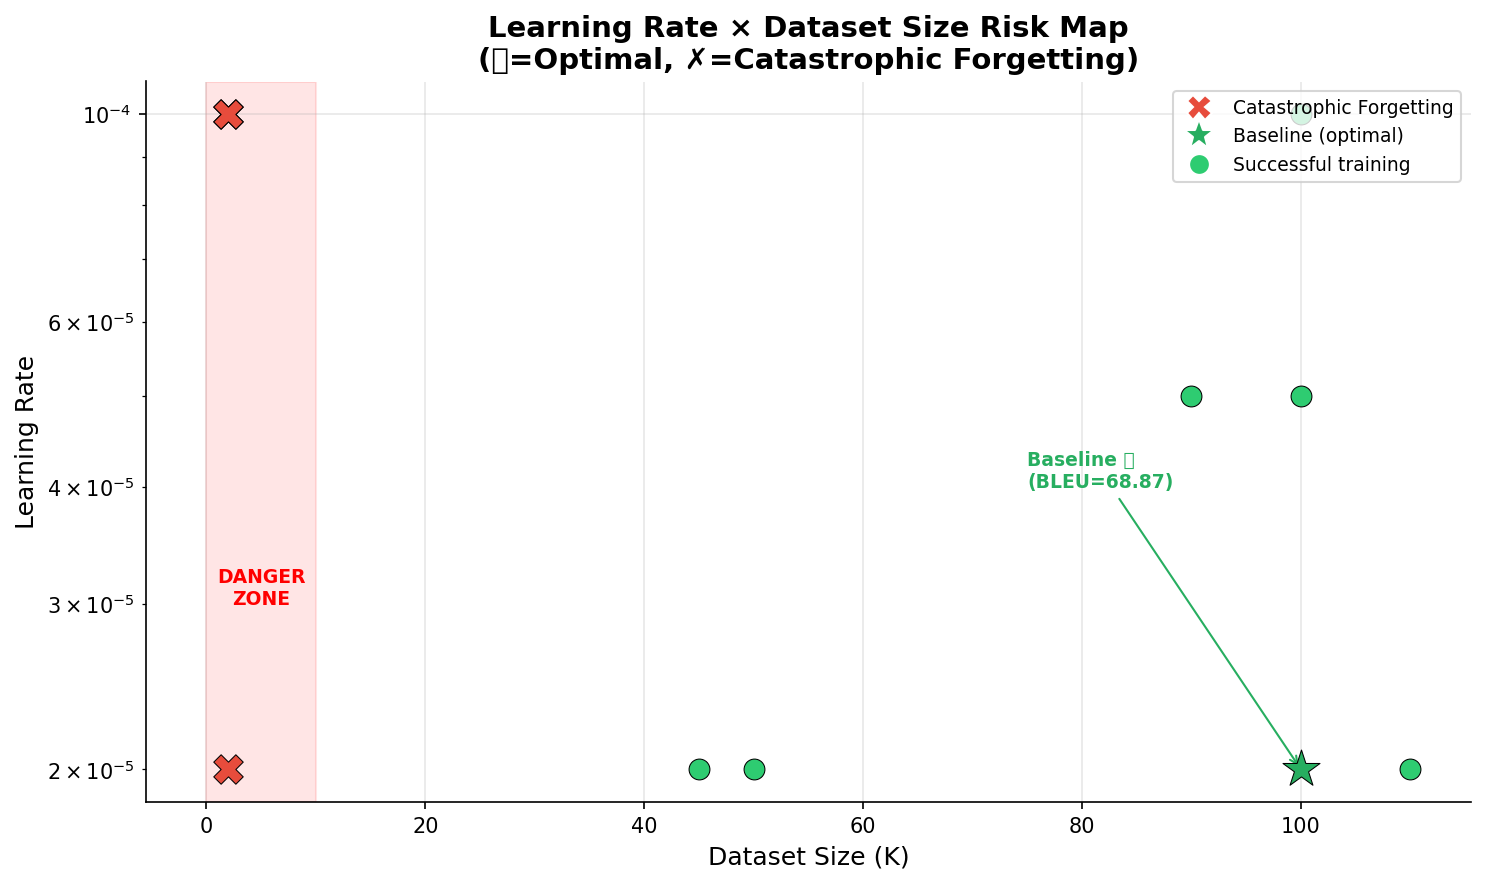
Determine 9: Studying charge and dataset-size threat map for full fine-tuning
2. max_epochs
Epoch rely in FFT is basically a forgetting query, not a loss-curve query. Coaching loss will preserve falling and your held-out validation will look wholesome as a result of it shares a distribution with coaching information, however capabilities on every thing you didn’t practice on quietly degrade. The LLM-as-Decide correctness rating rose to 90.0 p.c at 3 epochs, and lengthening past 3 epochs degraded each variant we experimented with.
3. global_batch_size
Batch dimension determines what number of examples contribute to every gradient step. At a set studying charge, smaller batches produce extra noisy updates that behave very similar to a better studying charge, rising forgetting threat. Bigger batches scale back noise but additionally scale back the variety of optimization steps, doubtlessly underfitting.
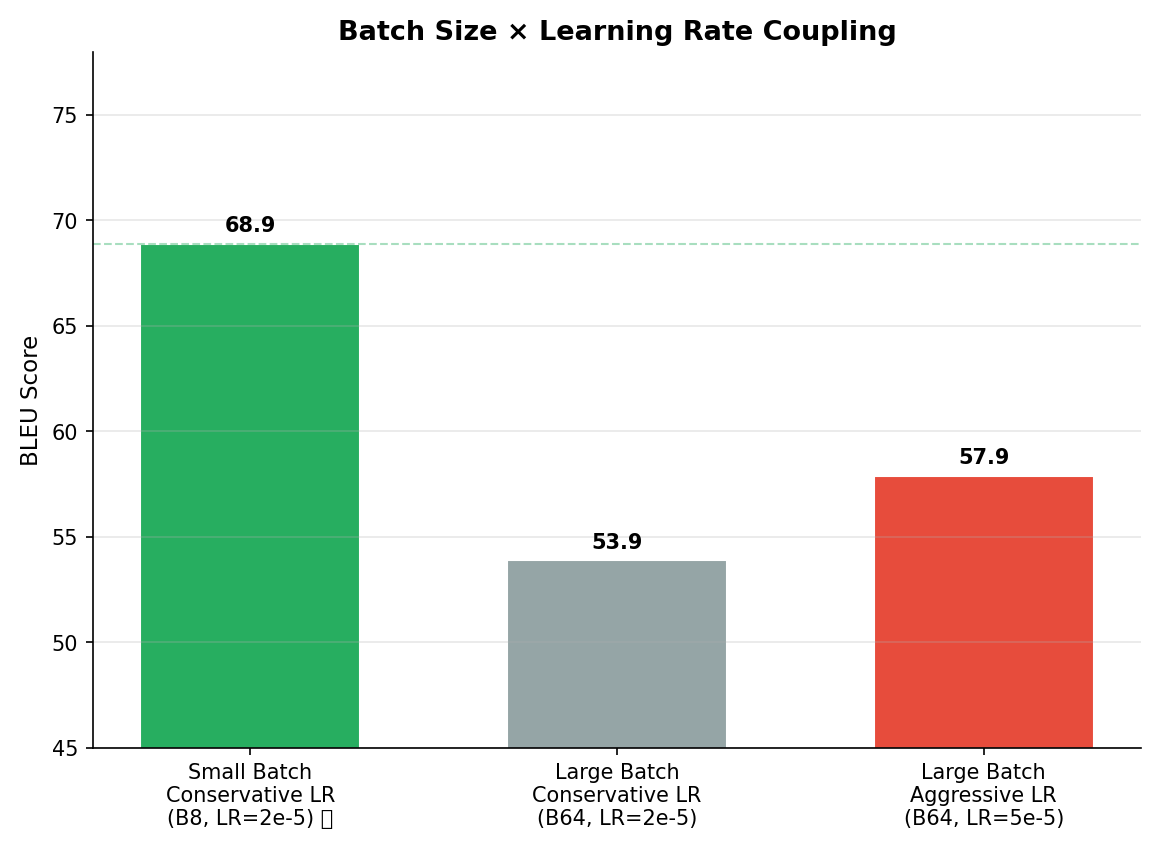
Determine 10: Impact of world batch dimension on mannequin high quality
Catastrophic forgetting threat
FFT modifies each parameter within the mannequin, together with the parameters that encode basic data acquired throughout pre-training. When fine-tuning pushes these parameters too aggressively towards a slim area, the mannequin can “neglect” its broader capabilities, a phenomenon referred to as catastrophic forgetting. We examined for this systematically utilizing MMLU, measuring basic data retention throughout all our fine-tuning configurations. A baseline configuration with warmup=5 p.c, batch dimension 8, and LR=2e-5 greatest preserved basic data (MMLU), as proven within the following determine.
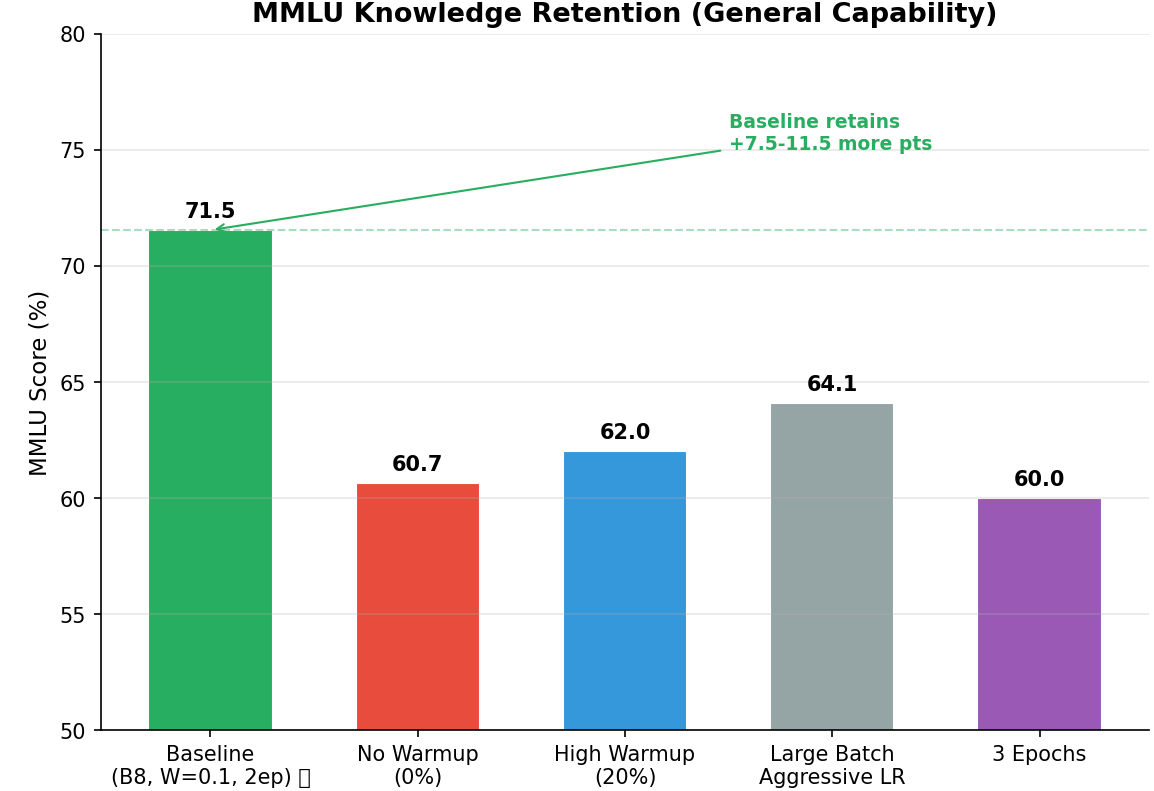
Determine 11: MMLU general-knowledge retention throughout hyperparameter configurations
Therefore, it is very important observe that FFT isn’t universally superior to LoRA, and its effectiveness is extraordinarily delicate to hyperparameter selections. For instance, in our experiments, each FFT and LoRA underperformed the bottom mannequin on MATH precise match, underscoring the problem of preserving reasoning capabilities throughout domain-specific fine-tuning. Aggressive studying charges (LR ≥ 5e-5) in FFT proved notably damaging, inflicting MATH scores to plummet to 2–3 p.c and MMLU accuracy to drop to three.6 p.c, clear proof of catastrophic forgetting. Moreover, LoRA barely outperformed FFT on the LLM-as-Decide metric (81.5 p.c in comparison with 79.5 p.c), demonstrating that parameter-efficient strategies can nonetheless maintain an edge on subjective high quality assessments. These findings reinforce that the selection between FFT and LoRA needs to be guided by cautious experimentation, dataset traits, and a transparent understanding of the trade-offs concerned.
Conclusion
With Full Tremendous-Tuning on Amazon SageMaker AI Serverless Mannequin Customization, your mannequin can absolutely soak up domain-specific data when job complexity and information scale demand it. In case your use case requires deep adaptation, similar to specialised reasoning, code technology, or domain-specific language understanding, and you’ve got enough high-quality coaching information, FFT delivers measurably stronger outcomes.
You will get began with FFT on SageMaker AI Serverless Mannequin Customization with serverless coaching, built-in analysis, and with out infrastructure or compute capability planning, so you may focus in your information and hyperparameter selections. You need to use the SageMaker Python SDK to configure and launch your coaching and analysis jobs programmatically. You’ll be able to see the documentation for supported base fashions accessible for Full Tremendous-Tuning on Serverless Mannequin Customization.
Concerning the creator