
Reinforcement studying (RL) post-training is turning into a typical step in constructing succesful language mannequin brokers. Fashions be taught to motive and act throughout sequences of steps by producing trajectories, receiving rewards, and updating their coverage based mostly on outcomes. Operating this at scale, throughout a number of nodes with tons of of GPU-hours of rollouts per coaching run, requires persistent cluster infrastructure. That infrastructure must maintain lengthy jobs, get well from {hardware} failures with out shedding progress, and supply visibility into coaching dynamics as they unfold.
Amazon SageMaker HyperPod supplies this infrastructure for large-scale machine studying (ML) workloads on Amazon Elastic Kubernetes Service (Amazon EKS). By its cluster resiliency options, it constantly screens node well being and mechanically replaces defective nodes, so a {hardware} failure doesn’t take the cluster down with it. Paired with checkpointing, a coaching job can decide up from its final saved step as a substitute of restarting from scratch. This issues for lengthy multi-node RL runs, the place a single {hardware} failure would in any other case value hours of rollout progress. Mixed with the Ray capabilities on HyperPod, you may create Ray clusters from SageMaker Studio, submit jobs remotely utilizing safe connections, and monitor coaching by way of pre-built Amazon Managed Grafana dashboards that the HyperPod Observability EKS add-on provisions for you.
On this publish, we present the right way to use these capabilities to run SkyRL, an open-source RL framework, to coach a Qwen3-VL-8B vision-language mannequin to navigate visible mazes utilizing Group Relative Coverage Optimization (GRPO) on SageMaker HyperPod. Ranging from the VisGym SFT checkpoint, a supervised fine-tuning (SFT) start line, GRPO post-training on HyperPod improves the maze remedy charge from 43.75% to greater than 95% on a hard and fast 64-maze analysis set.
Stipulations
To observe this walkthrough, you want:
- A SageMaker HyperPod cluster with Amazon EKS orchestration that has at the least 3 ml.g7e.12xlarge cases and one ml.r5d.16xlarge occasion.
- The next Kubernetes operators put in in your cluster: KubeRay operator, HyperPod Observability EKS add-on, and HyperPod Ray Endpoint Operator (for distant job submission). See the Ray on HyperPod getting began information.
- The Amazon FSx for Lustre CSI driver put in on the cluster. You additionally want an Amazon FSx for Lustre filesystem, a PersistentVolume backed by that filesystem, and a PersistentVolumeClaim (ReadWriteMany) that the pods can mount. The coaching job makes use of this at
/sharedfor checkpoint storage, Low-Rank Adaptation (LoRA) adapter synchronization, and analysis output. - A SageMaker Studio area with permissions to hook up with your HyperPod cluster. See organising SageMaker Studio for Ray.
- The
toolkit-for-ray-on-sagemaker-aiPython package deal put in.
Background
This part evaluations the reinforcement studying ideas behind the coaching and the cluster topology the walkthrough makes use of.
Multi-turn RL and GRPO
Commonplace single-turn RL assigns a reward to a single mannequin output. Multi-turn RL as a substitute trains an agent over an entire sequence of steps, the place it observes a state, acts, will get suggestions, and strikes on to the subsequent state. The coverage learns from the reward amassed over all the episode slightly than from anybody step.
Contemplate the instance downside of navigating a 2D maze. One episode is a single run at a maze, and every flip is one transfer: the mannequin seems on the present image of the maze, chooses a course or decides to cease, and the atmosphere sends again the up to date view. Rewards are sparse, so the mannequin earns 1.0 solely when it really reaches the objective throughout the transfer restrict and nothing in any other case. There isn’t any move-by-move reply key to coach in opposition to, since whether or not a transfer was good relies on the strikes round it.
That is the place SkyRL’s Group Relative Coverage Optimization (GRPO) is available in. For every beginning place, the agent runs the maze a number of instances below the present coverage, and GRPO grades these runs in opposition to each other, reinforcing those that beat the group’s common and pushing down those that path it. That within-group comparability is the entire coaching sign, which lets GRPO work with out a separate critic or worth mannequin.
Coaching topology
The answer mentioned right here runs SkyRL on a HyperPod Ray cluster with three GPU employee nodes and a CPU head node. SkyRL colocates inference and coaching on the identical GPUs: vLLM engines generate rollouts (full maze episodes) whereas a coverage mannequin sharded with Absolutely Sharded Knowledge Parallel (FSDP) handles gradient updates. After every optimizer step, up to date LoRA adapter weights sync from the coaching ranks to the inference engines by way of Amazon FSx for Lustre shared storage.
These are the occasion varieties we used. Different GPU cases and cluster sizes work as properly, offered the employees have sufficient GPU reminiscence for the mannequin.
- Staff: 3x
ml.g7e.12xlarge(2x NVIDIA RTX PRO 6000 Blackwell GPUs every, 6 GPUs whole). - Head:
ml.r5d.16xlarge(512 GB RAM, manages Ray GCS, dashboard, and LoRA adapter consolidation). - Coverage mannequin:
Qwen3-VL-8Bwith LoRA (rank 32), sharded throughout the 6 GPUs utilizing PyTorch FSDP. - Rollout engines: 6 colocated vLLM cases, one per GPU.
- Shared storage: Amazon FSx for Lustre at
/shared, used for LoRA sync and analysis output.
HyperPod supplies the cluster infrastructure: the Ray cluster is created from SageMaker Studio, job submission makes use of the sagemaker_ray:// protocol, and coaching metrics movement mechanically into pre-built Amazon Managed Grafana dashboards by way of the HyperPod Observability add-on.
Determine 1: RayCluster topology on Amazon SageMaker HyperPod, with one CPU head node and three GPU employee nodes that colocate FSDP coverage shards and vLLM rollout engines over a shared Amazon FSx for Lustre filesystem
Resolution overview
The next steps stroll by way of getting ready the coaching atmosphere, launching the cluster, operating the job, monitoring progress, and internet hosting the educated mannequin.
Step 1: Put together the container picture
To get began rapidly, use the next Dockerfile to construct a container picture with SkyRL, VisGym, and their dependencies pre-installed. That is the picture you’ll specify when launching your Ray cluster on HyperPod within the subsequent step. It builds on the official NovaSky-AI SkyRL base and pins each SkyRL and VisGym to particular commit SHAs so the construct is reproducible:
Construct the picture and push it to an Amazon Elastic Container Registry (Amazon ECR) repository in your account. Be aware the total picture URI, as you’ll use it when creating the Ray cluster within the subsequent step:
Step 2: Launch the Ray cluster from SageMaker Studio
Navigate to SageMaker Studio, select HyperPod, choose your cluster, then go to the Duties tab. From the duty sort record, select RayCluster, then select Create Ray Cluster.
Within the creation type, give the cluster the title skyrl-visgym, set the pinnacle occasion sort to ml.r5d.16xlarge, and add three employees utilizing ml.g7e.12xlarge. Set the container picture to the IMAGE_URI you pushed in Step 1.
The occasion varieties listed below are what we used for this walkthrough. Different occasion varieties will work, however maintain one constraint in thoughts for the pinnacle node: it wants massive reminiscence. The top consolidates LoRA adapter shards from the GPU employees at every checkpoint save, which briefly masses the total adapter weight set into CPU reminiscence. We used ml.r5d.16xlarge for its massive reminiscence capability (512 GB RAM) to accommodate this.
Mounting Amazon FSx for Lustre
To connect your Amazon FSx filesystem, select the YAML button within the top-right nook of the creation type to modify to the uncooked manifest editor, then add the quantity and mount to each the pinnacle and employee pod specs. The related part for every pod seems like this:
Exchange <your-fsx-pvc-name> with the title of the PersistentVolumeClaim backed by your Amazon FSx filesystem. With this in place, /shared is offered on each node within the cluster and the coaching job can learn and write checkpoints, LoRA weights, and analysis output from the pods.
Activate Distant endpoints so you may submit jobs and open dashboards with out a native kubectl port-forward. The cluster generates IAM-authenticated URLs for each.
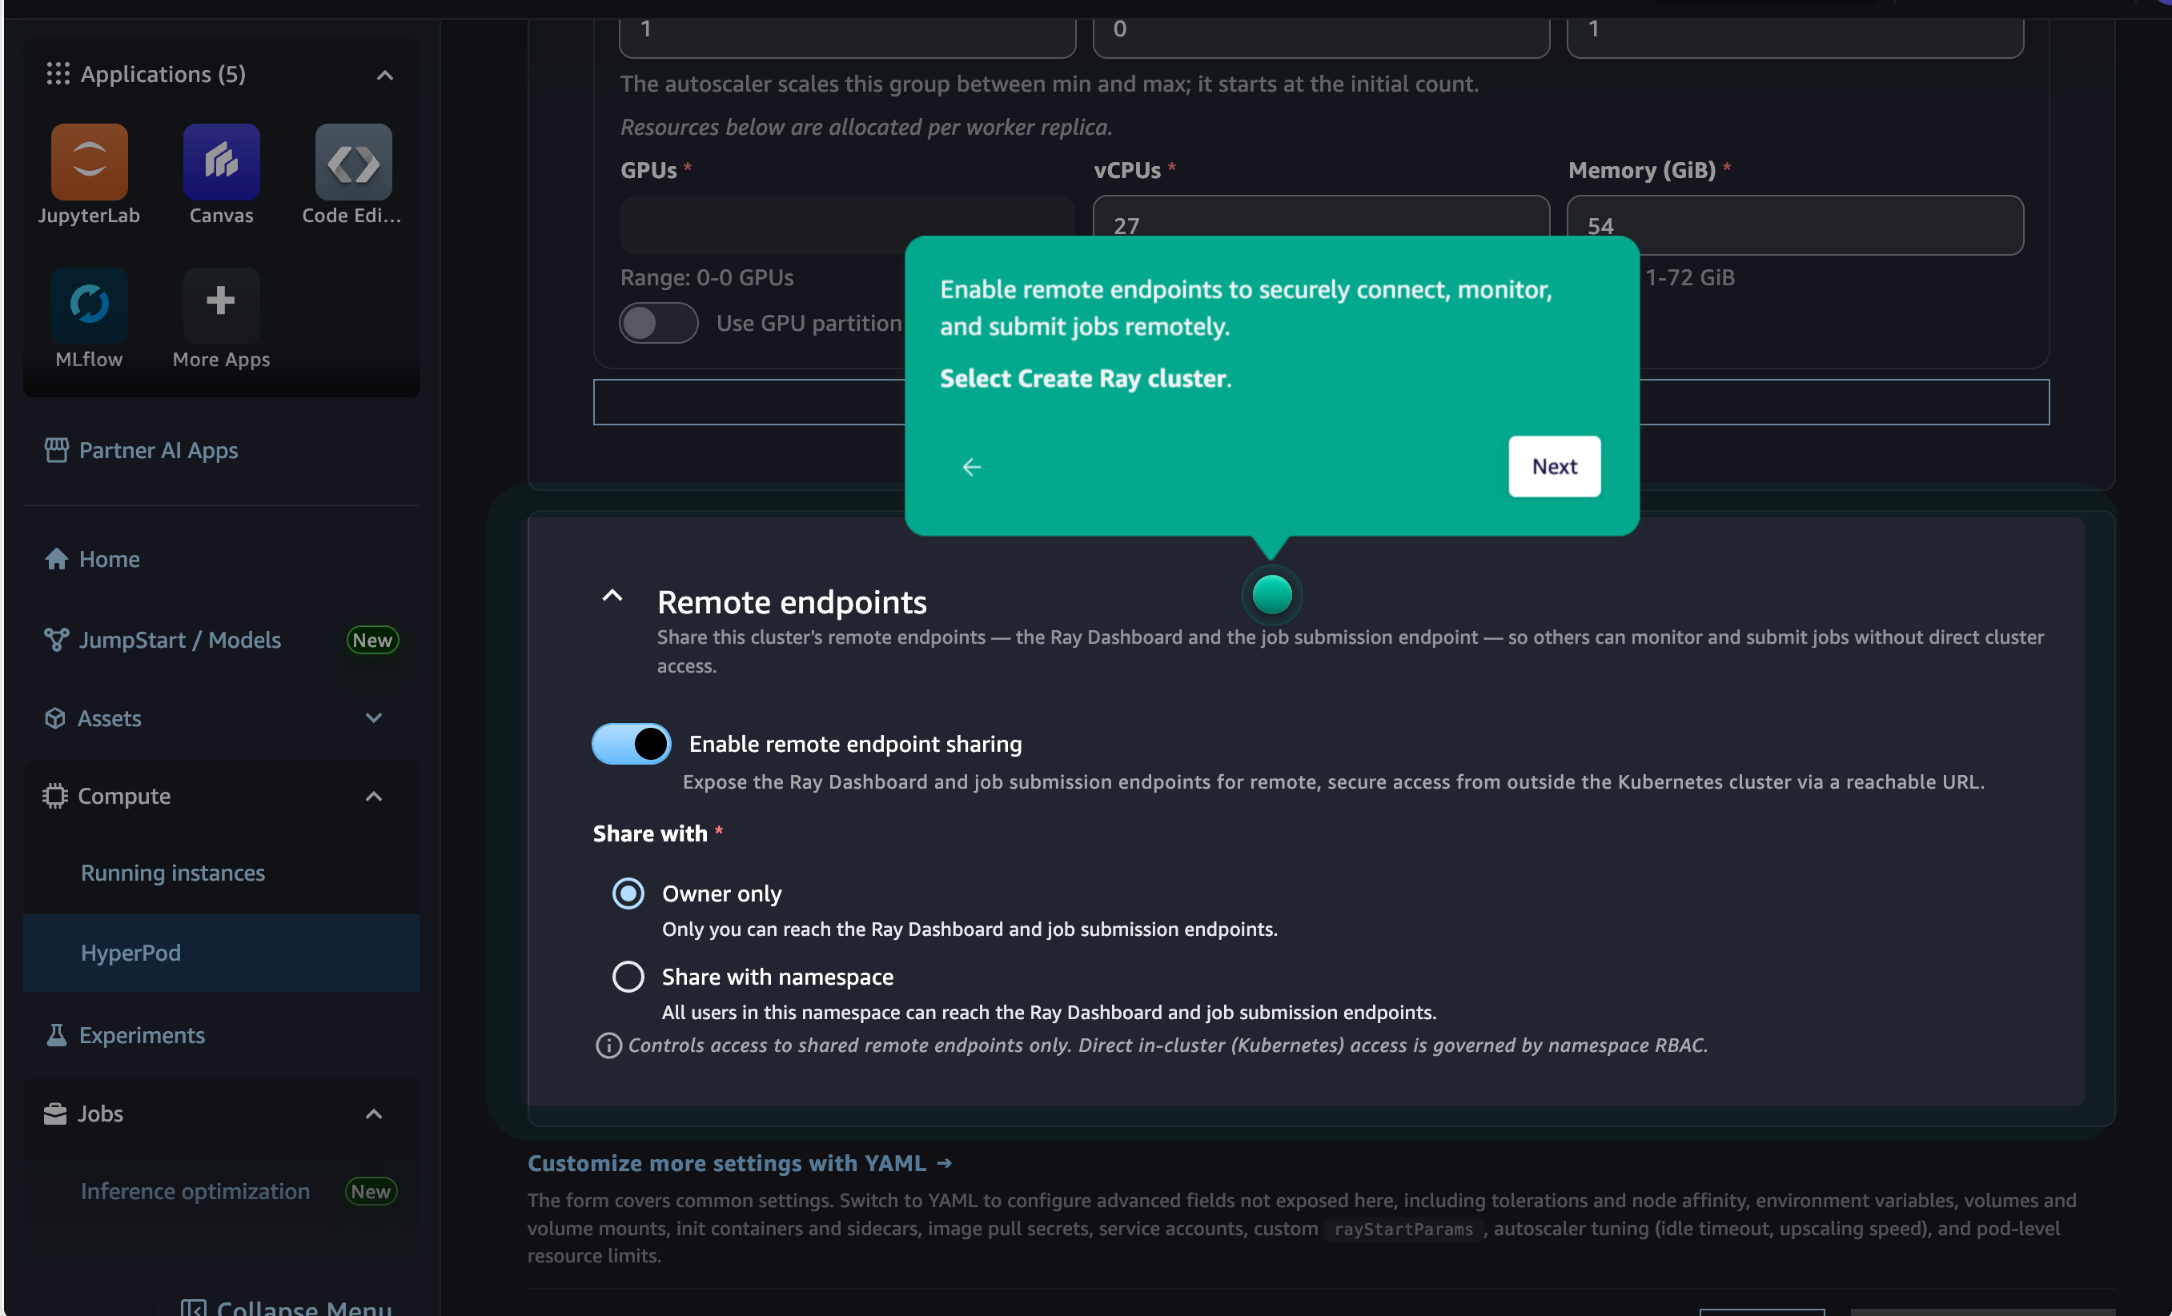
Determine 2: The Create Ray Cluster type in SageMaker Studio with distant endpoints turned on for job submission and dashboard entry
As soon as the cluster reaches Operating standing, the Actions menu within the Duties tab gives Open Ray Dashboard, Open Grafana, and cluster administration choices.
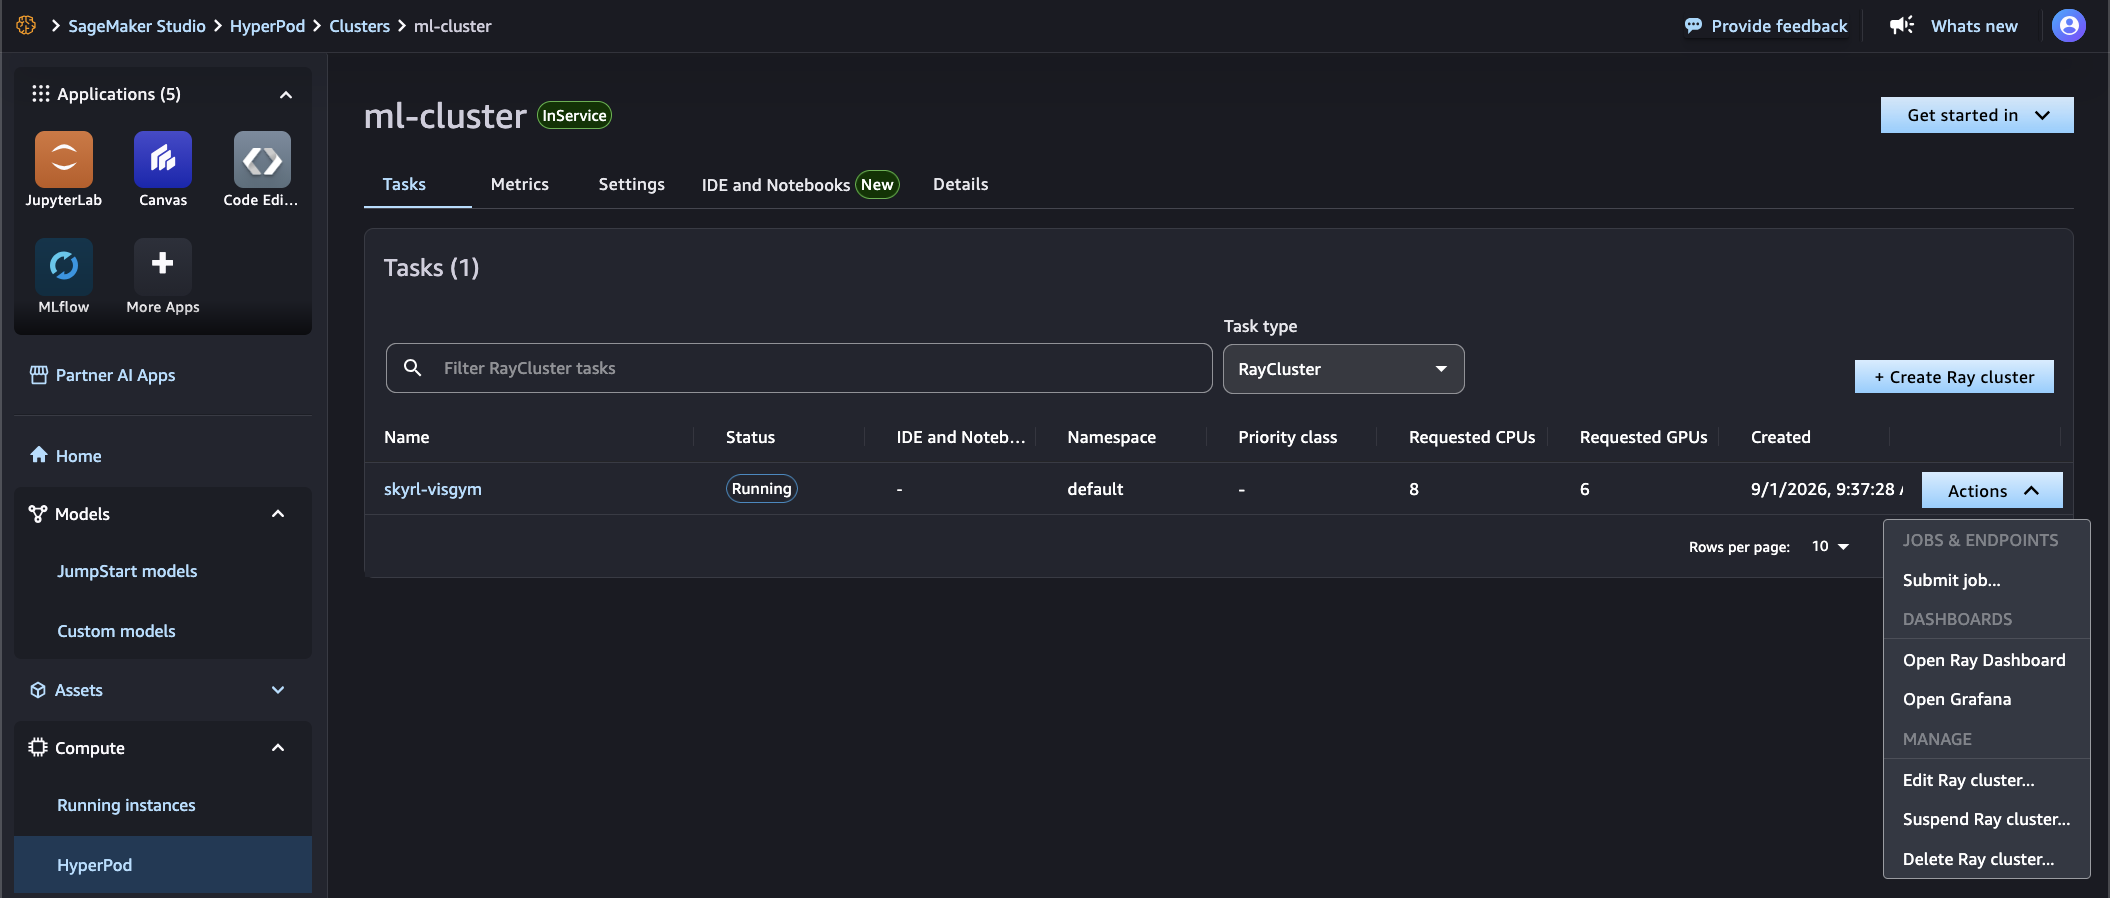
Determine 3: The skyrl-visgym Ray cluster at Operating standing within the SageMaker Studio Duties tab, with the Actions menu open
Step 3: Put together the coaching script
Save the next as train_job.sh in your working listing. The script downloads the SFT checkpoint and generates datasets on first run (each go to Amazon FSx, in order that they persist throughout runs), then launches the GRPO coaching job.
The SFT checkpoint provides GRPO a robust start line: Qwen3-VL-8B pre-trained on VisGym demonstrations already is aware of the right way to parse a maze picture and emit structured transfer actions, so GRPO solely must refine which sequences attain the objective.
With coach.placement.colocate_all=true, the vLLM rollout engines and FSDP coverage employees share the identical GPUs. Throughout rollout, GPUs run inference in parallel. Through the coverage replace step, they run FSDP coaching collectively. The lora_sync_path factors to Amazon FSx so up to date adapter weights are instantly seen to the inference engines on the nodes after every optimizer step. With out colocation, you want separate GPU swimming pools for coaching and inference, they usually sit idle ready for one another between phases, a ping-pong sample that wastes compute. Colocation avoids that idle time by having coaching and inference take activates the identical {hardware}. That’s the reason gpu_memory_utilization=0.45 is about conservatively: every GPU wants headroom for each the FSDP shard and the vLLM KV cache on the identical time.
Just a few different parameters are value noting. n_samples_per_prompt=8 controls what number of rollout trajectories GRPO generates per maze immediate to compute the group benefit. max_turns=15 caps every episode at 15 strikes. hf_save_interval=20 consolidates LoRA adapter shards onto the pinnacle node and saves a Hugging Face-compatible checkpoint each 20 steps. eval_interval=10 runs the held-out 64-maze analysis each 10 steps so you may monitor remedy charge as coaching progresses.
The job additionally writes full coaching checkpoints so it could get well from an interruption. Setting ckpt_interval=20 saves the whole coaching state to ckpt_path each 20 steps. That state consists of the mannequin weights, optimizer state, studying charge schedule, and dataloader place. resume_mode=newest tells SkyRL to choose up from the newest checkpoint below that path when the job begins. Level ckpt_path at sturdy shared storage that’s not tied to a single node, resembling an Amazon Easy Storage Service (Amazon S3) prefix or your Amazon FSx mount. Hold the trail secure throughout runs so a restarted job can discover its checkpoint. That is what pairs with HyperPod cluster resiliency. When a node fails, HyperPod detects and replaces it mechanically, and whenever you resubmit the job it continues from the final saved step as a substitute of beginning over. The complete checkpoints written right here seize coaching state for resumption, whereas the hf_save_interval exports seize inference-ready LoRA adapters, so the 2 run alongside one another for various functions.
Step 4: Submit the coaching job remotely
When toolkit-for-ray-on-sagemaker-ai is put in, Ray’s normal Jobs CLI authenticates by way of the cluster’s secured endpoint utilizing the sagemaker_ray:// deal with scheme the package deal registers. The library authenticates to the Ray endpoint utilizing your AWS credentials, so that you don’t must do it your self. This manner, you may submit and monitor jobs from a laptop computer, a CI/CD pipeline, or an atmosphere with AWS credentials, with no kubectl port-forward and no direct community path to the cluster.
First, authenticate in opposition to the EKS cluster:
Then submit the job, passing the present listing because the working dir so train_job.sh is uploaded to the cluster head:
As soon as submitted, monitor progress utilizing the identical deal with:
You can even monitor the job in SageMaker Studio below the Duties tab, or open the Ray Dashboard immediately from the cluster Actions menu for a full job view with per-actor useful resource utilization.
Step 5: Monitor coaching progress
HyperPod supplies two monitoring surfaces: the Ray Dashboard for job-level visibility, and Amazon Managed Grafana for infrastructure and coaching metrics. Each are accessible immediately from the Duties tab in SageMaker Studio.
Ray Dashboard
From the Duties tab in SageMaker Studio, select Open Ray Dashboard. This generates a short-lived authenticated URL for you mechanically.
You can even generate the URL from the HyperPod CLI:
The command returns a presigned URL. Open it in a browser to view the Ray dashboard. The session is legitimate for as much as six hours. For extra particulars, see Producing a dashboard connection URL within the HyperPod documentation.
The next screenshot reveals the Jobs view with the operating job, its present step, and per-worker useful resource utilization.
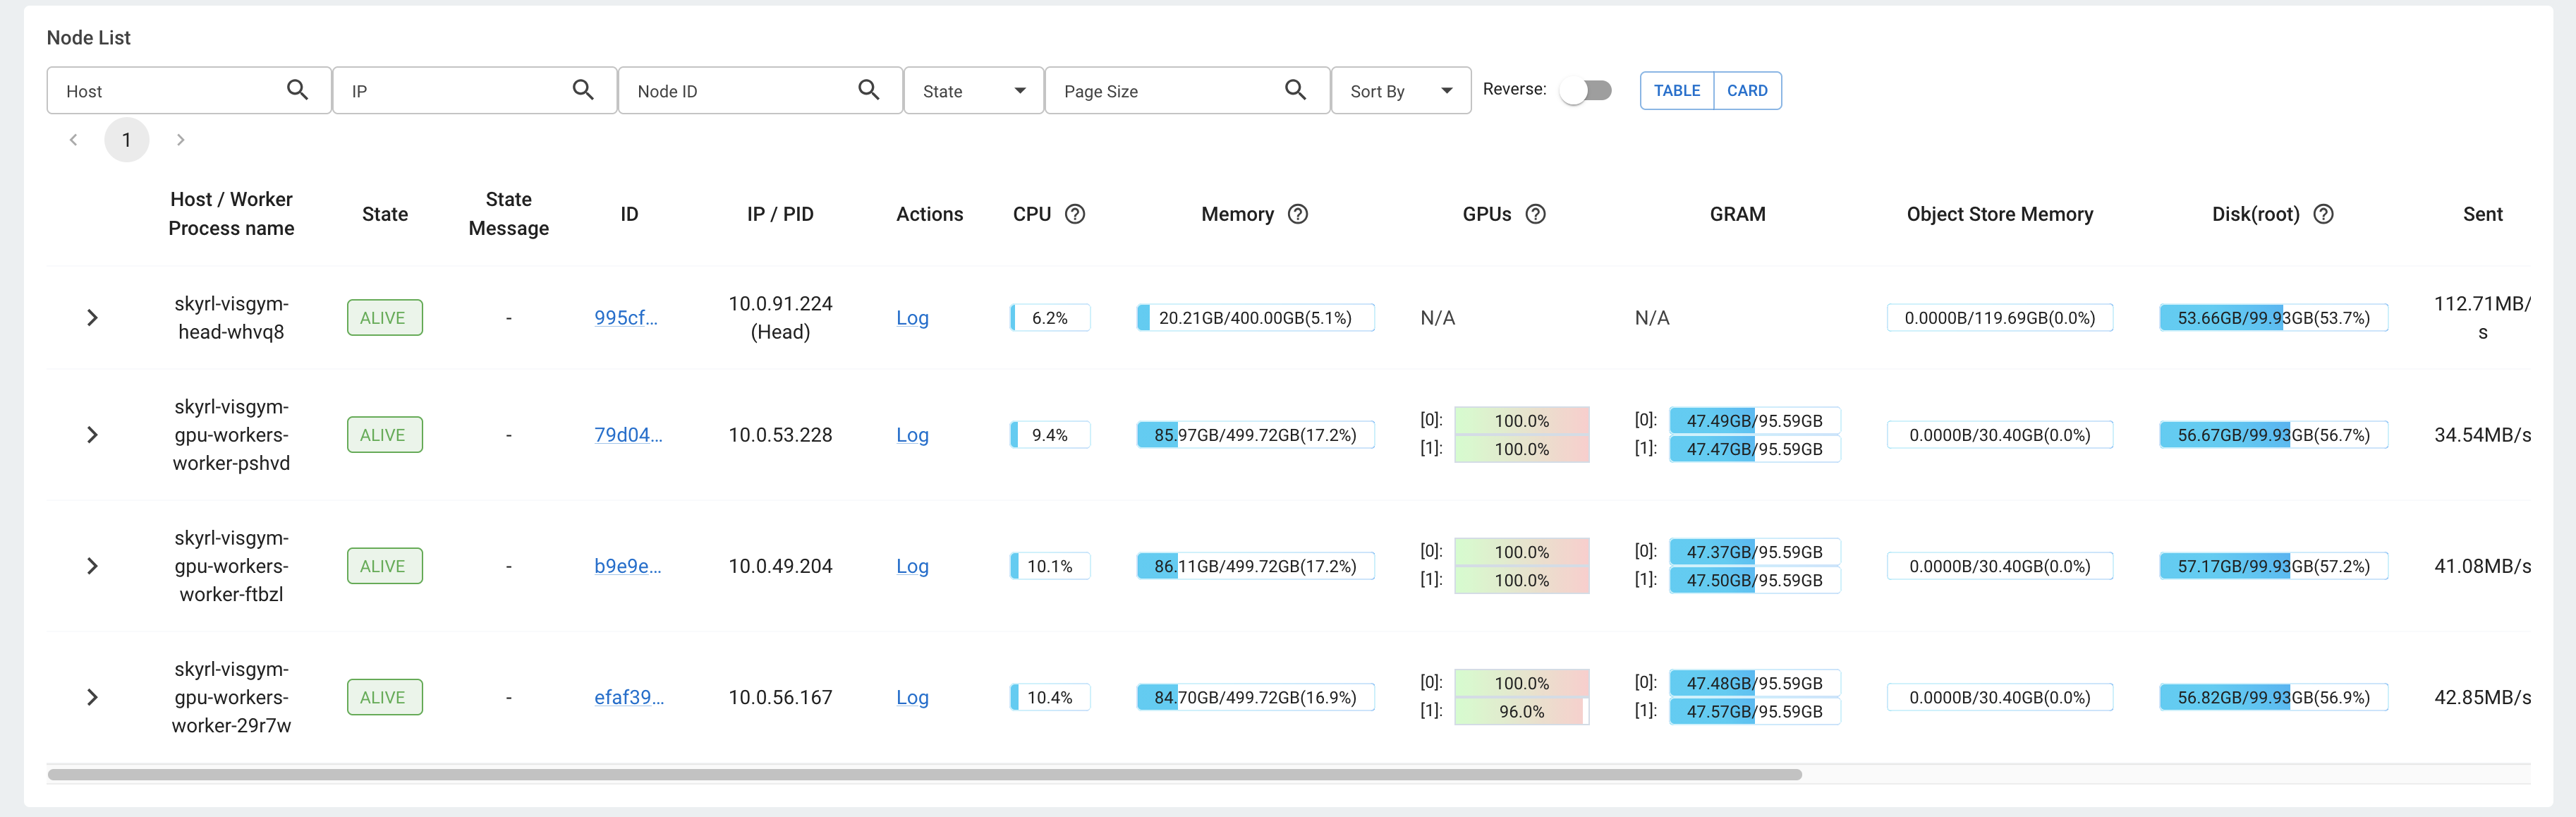
Determine 4: The Ray Dashboard Jobs view displaying the operating coaching job and per-worker GPU utilization
HyperPod Observability dashboards
From the Duties tab, select Open Grafana. The HyperPod Observability EKS add-on provisions 4 pre-built Ray dashboards in Amazon Managed Grafana: Ray Core, Ray Knowledge, Ray Prepare, and Ray Serve. All 4 seem below a Ray folder and assist filtering by cluster title. Here’s a part of the core dashboard displaying CPU, GPU, and reminiscence utilization whereas the coaching is in progress.
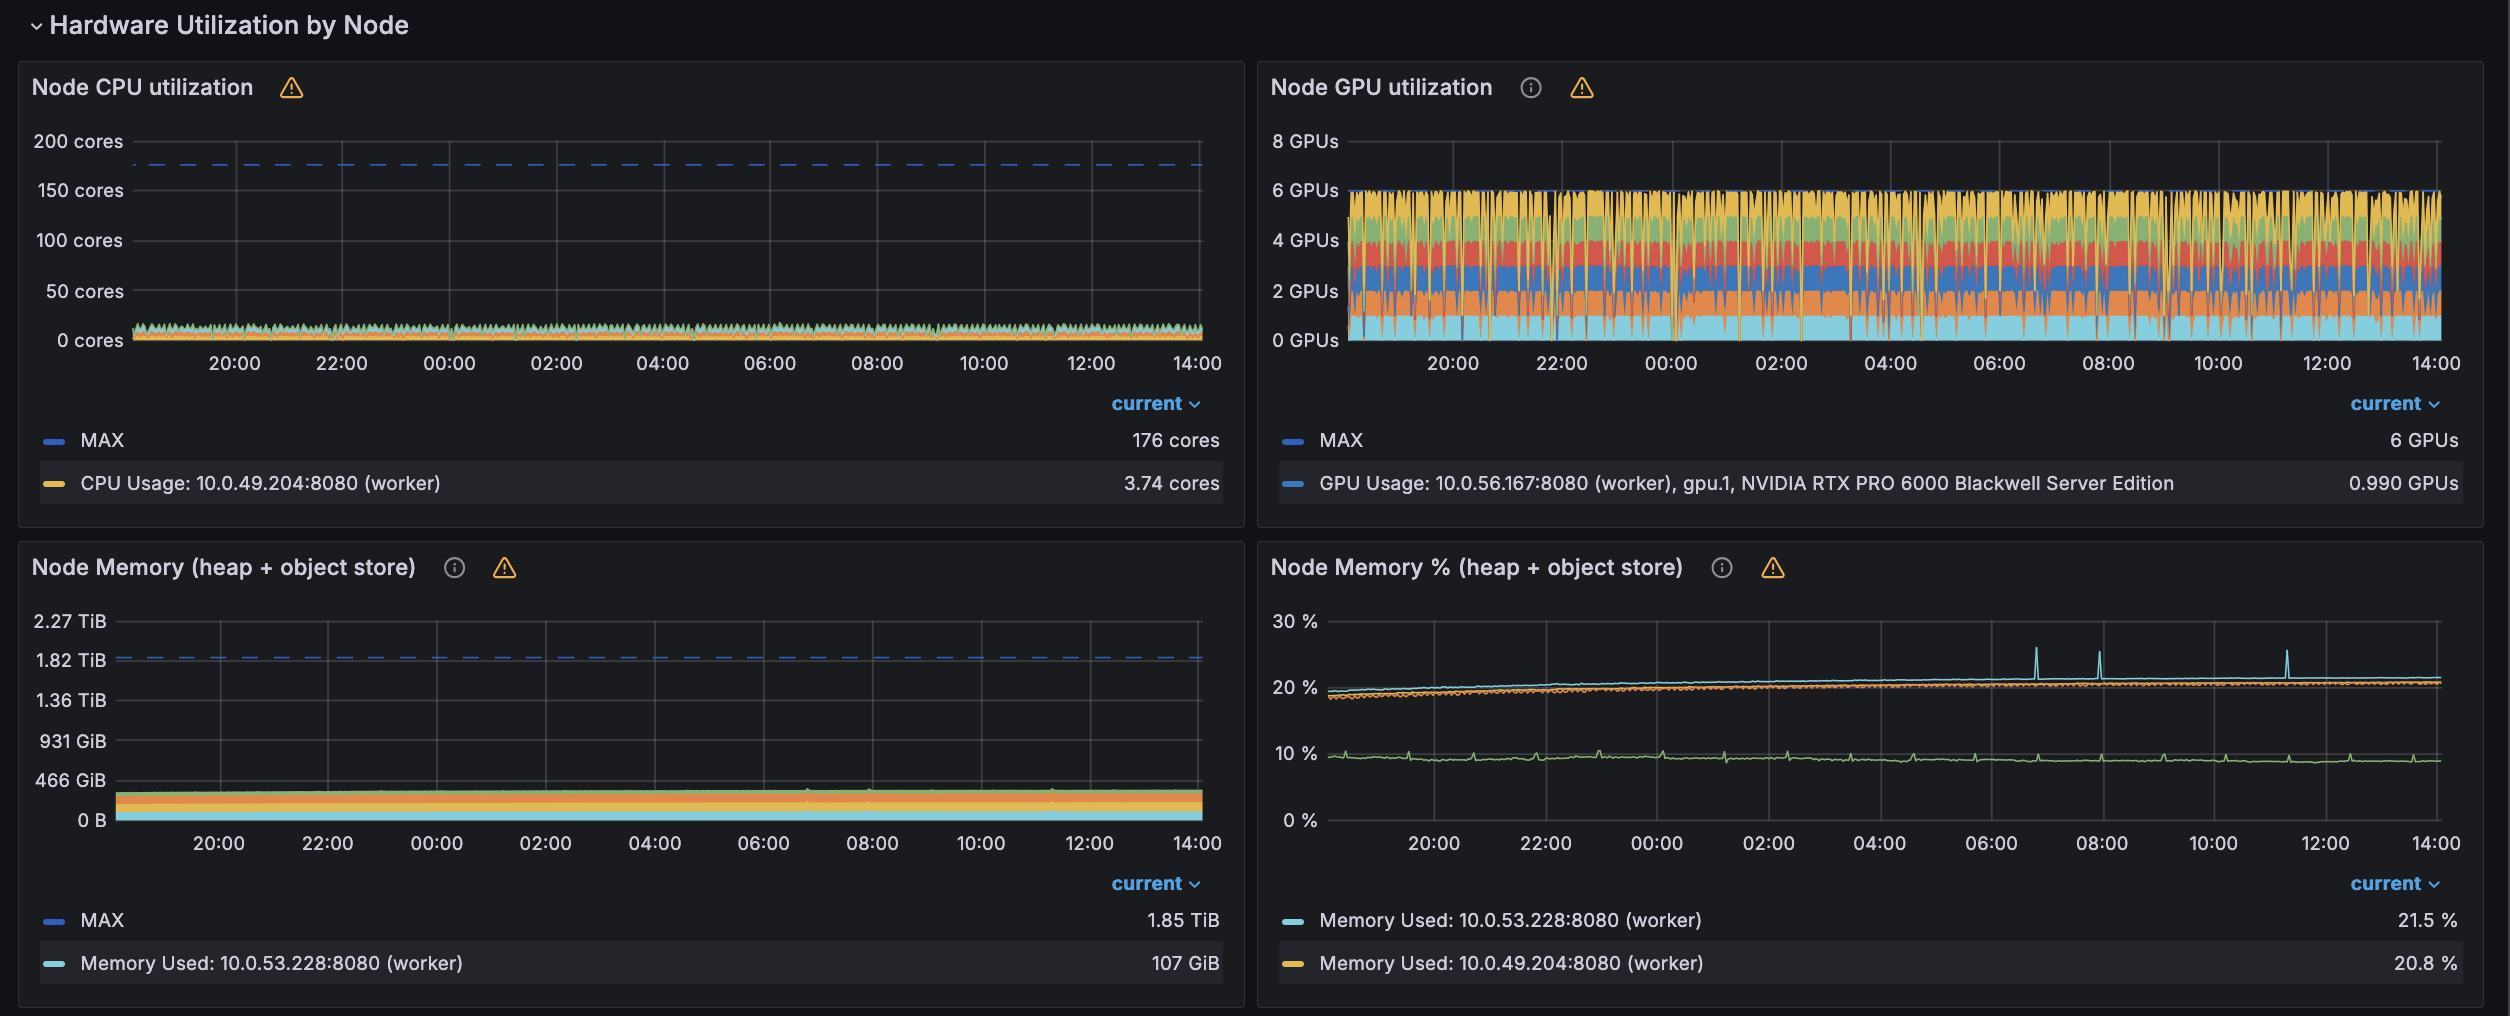
Determine 5: Amazon Managed Grafana Ray Core dashboard panels for CPU, GPU, and reminiscence utilization throughout coaching
Monitoring analysis accuracy
SkyRL runs an analysis cross each eval_interval=10 steps in opposition to the fastened 64-maze held-out set and logs eval/all/pass_at_1 to the console. You may grep for it within the job logs:
In our experiment, the mannequin reached 75% remedy charge round step 100 and peaked at 96.875% (62/64 mazes) at step 160, in comparison with a baseline of 43.75% (28/64 mazes) earlier than GRPO post-training. Your outcomes will differ based mostly on hyperparameters and the maze configuration. As soon as the remedy charge reaches your goal, the LoRA adapter at that step is prepared for inference. Checkpoints are saved to /shared/runs/<run_id>/global_step_<N>/coverage/adapter_model.safetensors each 20 steps.
Step 6: Host the educated mannequin for inference
With coaching full, the artifact you deploy is a LoRA adapter slightly than a full mannequin, and Ray Serve masses that adapter on demand at request time. The one requirement is the place the adapter lives. Ray Serve’s dynamic LoRA loader reads adapters from cloud storage resembling Amazon S3, so start by staging the adapter in an S3 prefix. Copy the adapter from the checkpoint step you chose throughout coaching into that prefix:
Every adapter occupies its personal subdirectory beneath this prefix, and that subdirectory title (maze-grpo on this instance) is the title you’ll use to request the adapter as soon as the endpoint is dwell.
Serve with Ray Serve on a Ray cluster
To host the adapter, run Ray Serve on a Ray cluster constructed from the AWS Deep Learning Container for Ray Serve LLM, which bundles Ray Serve, the ray[llm] stack, and vLLM. With it, you may arise an OpenAI-compatible endpoint utilizing the built-in ray.serve.llm:build_openai_app builder and no customized picture. We suggest operating inference on a RayService, which KubeRay reconciles into its personal Ray cluster (see the KubeRay docs).
A RayService describes its Serve utility by way of a serveConfigV2 spec, and inside that spec the ray.serve.llm:build_openai_app builder accepts one llm_configs entry per base mannequin, as proven within the following configuration:
On this configuration, model_source factors on the base SFT mannequin on the Amazon FSx mount, whereas dynamic_lora_loading_path factors on the S3 prefix you populated within the earlier step. Set max_lora_rank to the identical LoRA rank you used throughout coaching. Lastly, be sure that the Ray Serve replicas can get hold of AWS credentials to learn the adapters out of your S3 bucket. On Amazon EKS, the beneficial mechanism for that is Amazon EKS Pod Identification.
Dynamic LoRA loading per request
With this configuration in place, a single deployment serves each the bottom mannequin and each adapter saved below the S3 prefix, and also you select which one to run by way of the mannequin discipline on every request:
- Set
mannequintovisgym-qwen3vlto run the bottom SFT mannequin by itself. - Set
mannequintovisgym-qwen3vl:maze-grpoto use the GRPO adapter on prime of that base mannequin. The ID follows the<base-model-id>:<adapter-name>conference, the place the adapter title is the subdirectory you created belowdynamic_lora_loading_path.
The primary time an adapter is requested, Ray Serve downloads it from Amazon S3 onto the reproduction and caches it, so each later request reuses the loaded weights with out downloading once more. As a result of the endpoint speaks the OpenAI API, you may name it from an OpenAI-compatible shopper. For the whole set of configuration choices, see the Ray Serve LLM documentation and the multi-LoRA deployment guide.
With the adapter deployed, the mannequin can run a full maze episode by itself, taking within the present view at every flip and returning its subsequent transfer till it reaches the objective. The loop that drives this (constructing the immediate, encoding the maze picture, parsing the motion, stepping the atmosphere) is identical one SkyRL and VisGym already use for rollouts. Level that atmosphere on the served endpoint slightly than rebuilding it round a uncooked shopper.
Here’s a pattern consequence, the educated mannequin navigating two mazes finish to finish:
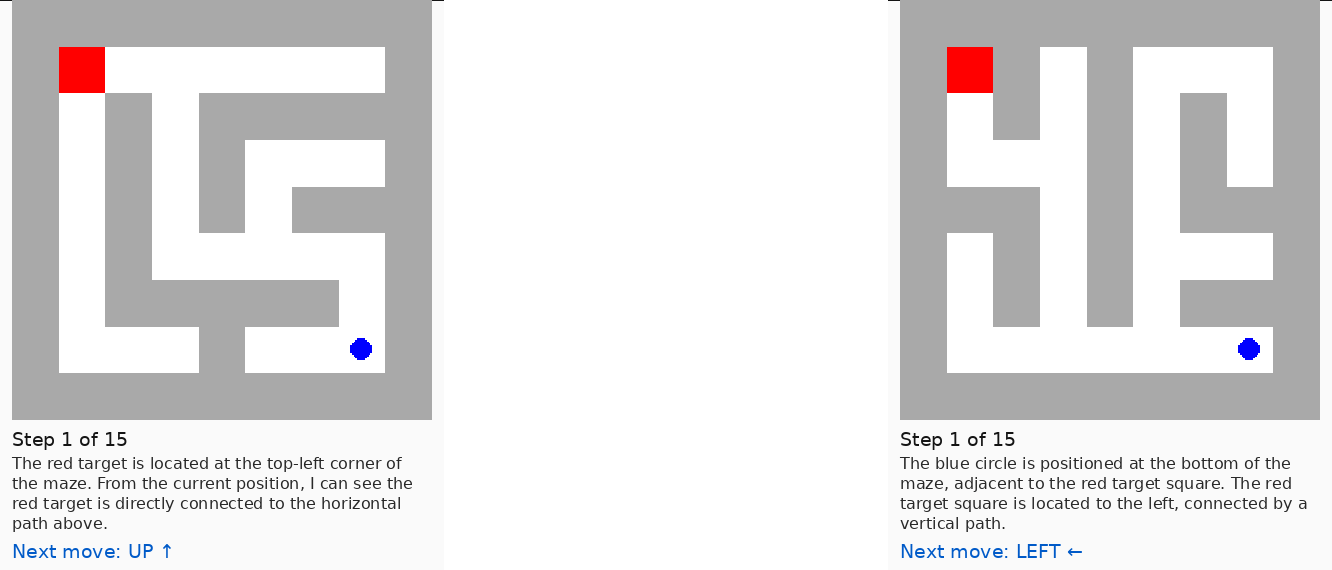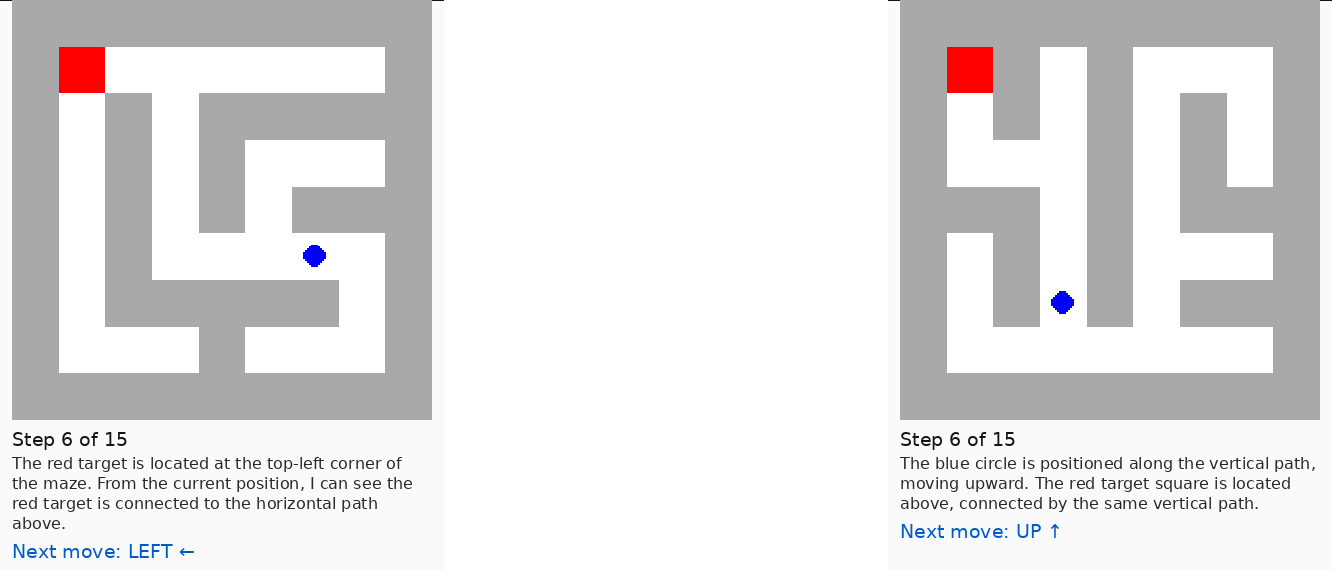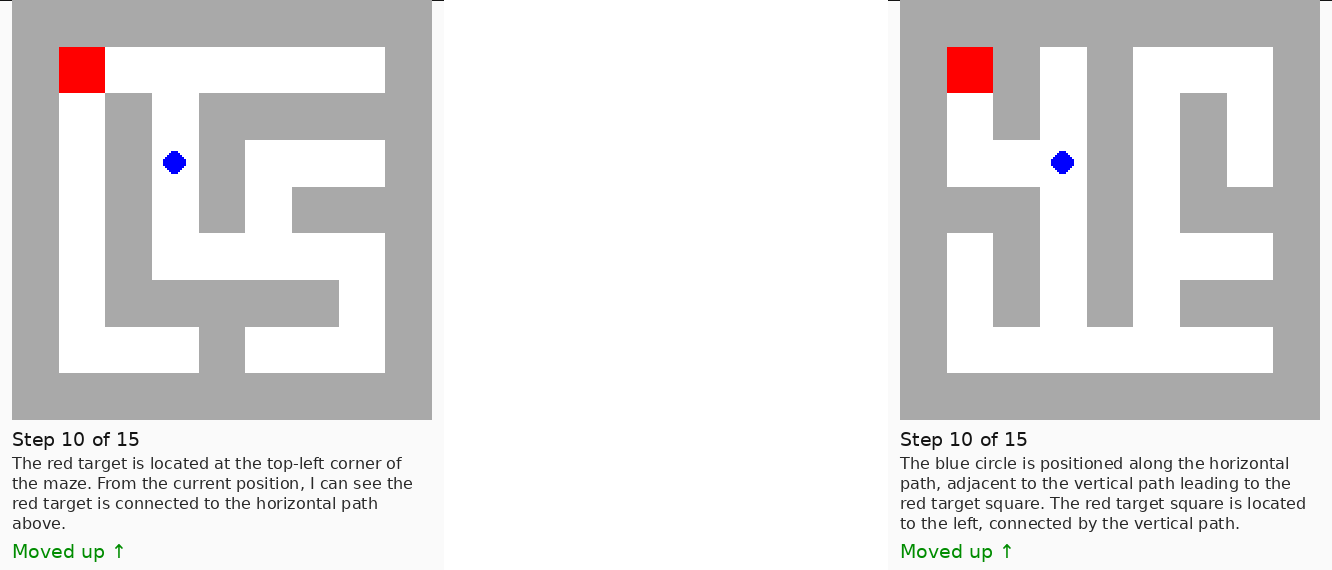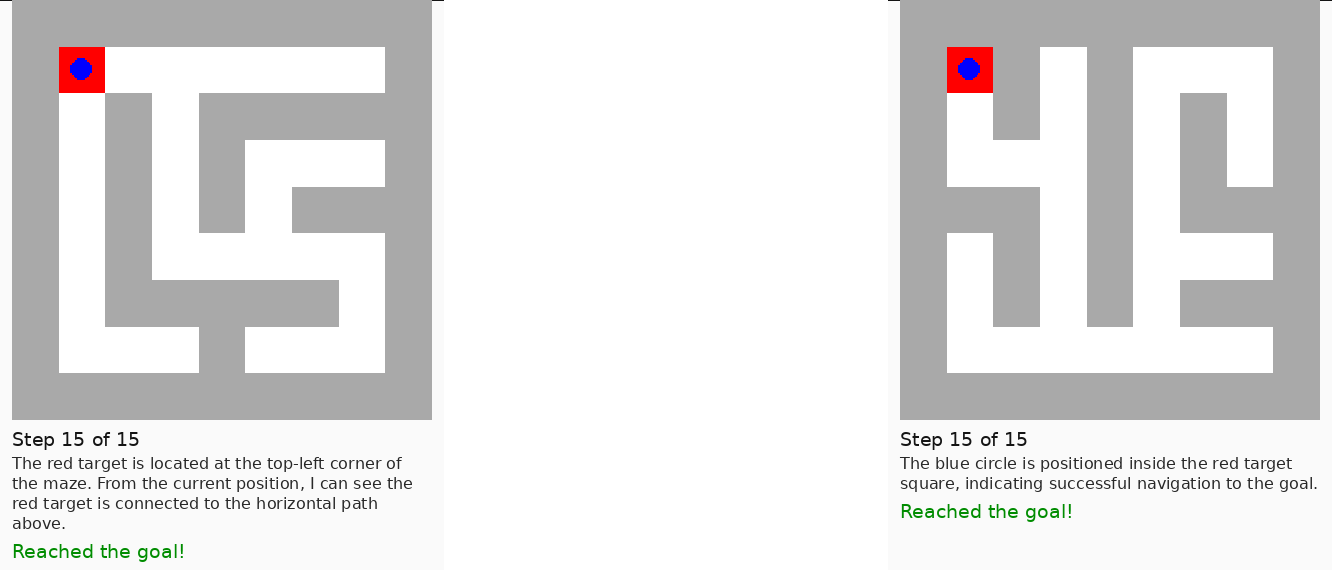
Determine 6: The fine-tuned mannequin fixing two mazes finish to finish, taking one transfer per flip till it reaches the objective
Clear up
Whenever you end the walkthrough, clear up the assets you created to cease incurring costs. Open the Duties tab in SageMaker Studio, choose the skyrl-visgym Ray cluster, and select Delete from the Actions menu. If you happen to created a separate RayService to host the educated adapter, delete that as properly with kubectl delete rayservice <title>. To launch the GPU capability itself, scale down the HyperPod occasion teams you added for this walkthrough, or delete the HyperPod cluster from the Amazon SageMaker AI console. If you happen to not want the SageMaker Studio area, you may delete it from the SageMaker AI console too.
Conclusion
On this publish, we walked by way of an end-to-end multimodal RL coaching workflow on Amazon SageMaker HyperPod: constructing a customized container picture, launching a Ray cluster from SageMaker Studio, ranging from the VisGym SFT checkpoint to offer GRPO a robust initialization, submitting the job utilizing the sagemaker_ray:// protocol, monitoring analysis accuracy by way of the Ray Dashboard and Grafana dashboards provisioned by the HyperPod Observability add-on, and internet hosting the educated adapter for inference as soon as it reached the goal remedy charge. All the workflow runs on the resilient, self-healing compute infrastructure that Amazon SageMaker HyperPod supplies.
The identical sample applies to SkyRL workloads or different Ray-based RL frameworks. The HyperPod infrastructure, the Studio console expertise, and the Amazon FSx shared storage work with frameworks that use normal Ray APIs.
To get began, see the Amazon SageMaker HyperPod documentation and the Ray on HyperPod getting began information.
In regards to the authors