
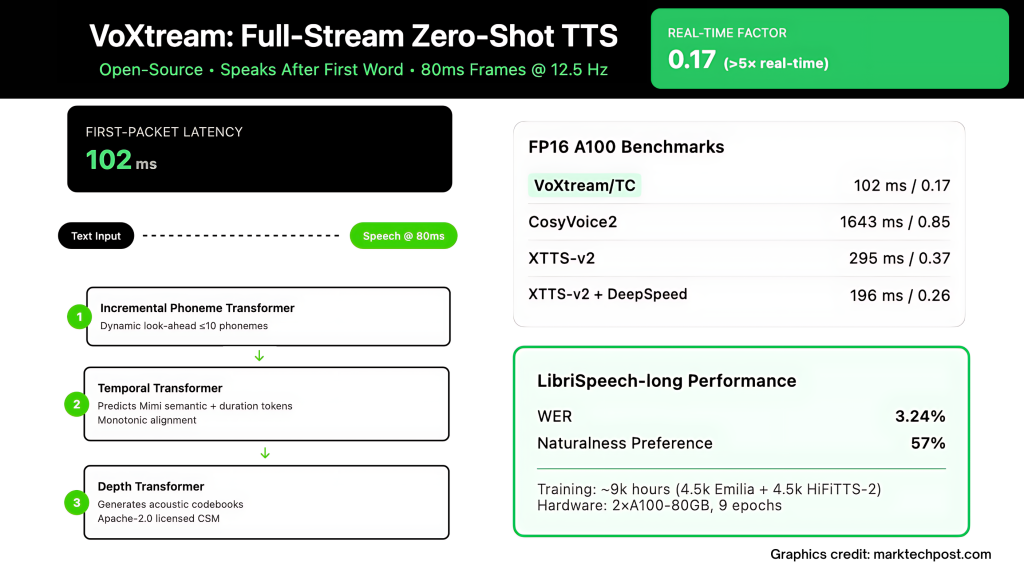
Actual-time brokers, dwell dubbing, and simultaneous translation die in 1000 milliseconds. Most “streaming” TTS (text-to-speech) stacks watch for a bit of textual content earlier than it emits a sound, so people hear the beat of silence earlier than the voice begins. Voxtream- Launched by Kth’s speech, music and listening to teams – this head-on assault: it begins speaking After the primary phraseoutputs audio 80ms bodyand report 102 MS First Packet Latency (FPL) Fashionable GPU (with Pytorch compilation).
What precisely is a “full stream” TTS? Additionally, how is it completely different from “output streaming”?
The output streaming system decodes audio in chunks, however nonetheless All the enter textual content Entrance; The clock begins late. Full Stream The system consumes textual content As I arrive (Every phrase from LLM) audio is emitted in lockstep. Voxtream implements the latter. It ingests phrase streams, generates audio frames constantly, eliminating input-side buffering whereas sustaining low frame-by-frame computing. The structure explicitly targets the beginning of a single phrase, not simply steady-state throughput.
How does Voxtream begin talking with out ready for future phrases?
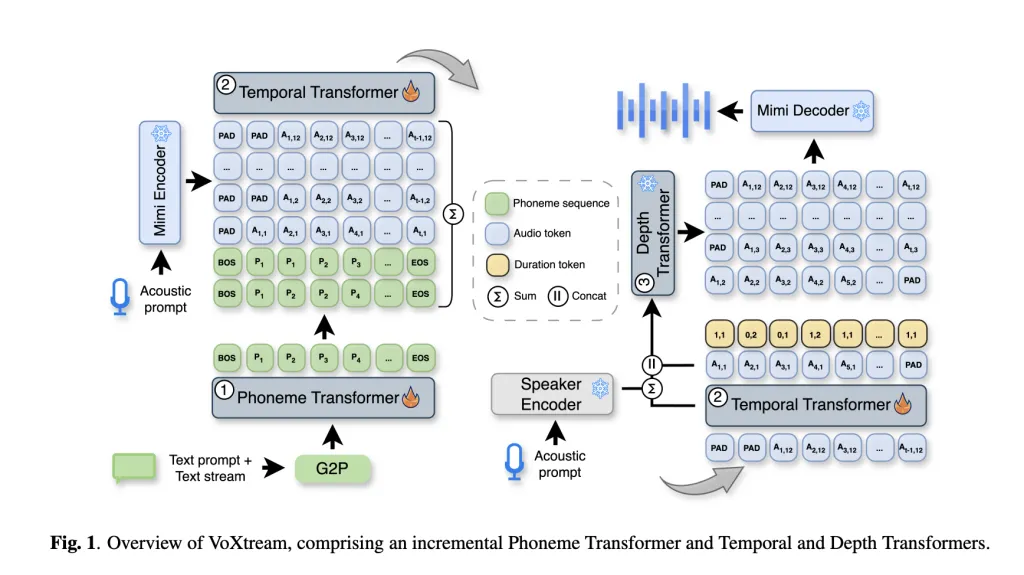
The core trick is a Dynamic phoneme look Inside Incremental Phoneme Transformer (PT). pt Could Please have a look 10 phonemes To stabilize the prosodic, nevertheless I am not ready For that context. Technology can begin instantly after the primary phrase enters the buffer. This avoids a set lookahead window that provides a begin delay.
What’s the mannequin stack below the hood?
Voxtream is a Single, totally automated (AR) Pipeline with 3 transformers:
- Phoneme Transformer (PT): Decoder solely, incremental; dynamic look ≤10 phonemes; speech through G2PE at phrase stage.
- Temporal Transformer (TT): AR predictor variables Mimi Codec Semantic token Plus a Period token It encodes a monotonous phoneme-to-auditory alignment (“Keep/go” and {1,2} phonemes). Mimi runs 12.5 Hz (→ 80ms Body).
- Depth Transformer (DT): AR generator for the remaining MIMI Acoustic CodebookTT output and a redimnet Embedded audio system Zero Shot Voice immediate. The MIMI decoder is reconstructed for every waveform body, permitting for steady emission.
Mimi’s streaming codec design and twin stream tokenization are properly documented. Voxtream makes use of the primary codebook as a “semantic” context, and the remaining for top constancy reconstruction.
Is it truly quick or is it simply “quick on paper”?
The repository accommodates a Benchmark script It measures each fpl and Actual-time Issue (RTF). Above A100Analysis Staff Report 171 ms / 1.00 RTF With out compilation 102 ms / 0.17 RTF With compilation; prime RTX 3090, 205 ms / 1.19 RTF Not compiled 123 ms / 0.19 RTF compile.
How does it evaluate to as we speak’s in style streaming baseline?
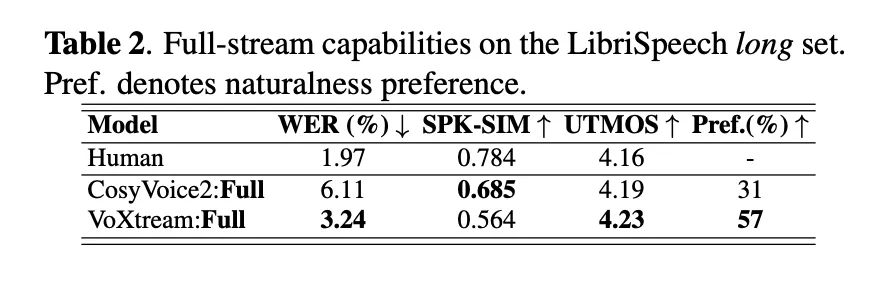
The analysis group evaluates Quick Kind Output Streaming and Full Stream situation. Above Librispeech-Lengthy Full stream (the place the textual content arrives by phrase), Voxtream exhibits Wer (3.24%) decrease than cosyvoice2 (6.11%) And a Vital naturalness preferences Within the case of a listener analysis voxtream (P≤5E-10), Cosyvoice2 scores greater on speaker similarity. Matches the stream matching decoder. At runtime, Voxtream has the bottom FPL of any public streaming system in contrastworks with compilation > 5×Sooner than actual time (RTF≈0.17).
Why does this AR design beat the unfold/stream stack at first?
A diffusion/stream vocoder normally generates audio chunkdue to this fact, even when textual content audio interleaving is intelligent, the vocoder will nonetheless impose a flooring on the latency of the primary packet. Voxtreams shall be stored All levels and body sync–PT→TT→DT→MIMI decoder – First 80ms As an alternative of a multi-step sampler, the packet seems after passing by the stack as soon as. How will introductory analysis be defined earlier than interleaved and chunked approaches? NAR Stream Matching Decoder IST-LM and cosyvoice2 Regardless of its robust offline high quality, it hinders low FPL.
Did they’ve an enormous quantity of information right here, or are they small and clear?
a ~9k hours midscale corpus: nearly 4.5kh Emilia and 4.5kh Hifitts-2 (22 kHz subset). group Throughout the day To take away a multi-speaker clip, Filtered transcripts Use and apply ASR nisqa Drops low high quality audio. All the pieces is resampled 24 kHzThe dataset card then spells out the pre-procedural pipeline and alignment artifacts (MIMI tokens, MFA alignment, length labels, speaker templates).
Does the headline high quality metric keep the clips on the cherry decide?
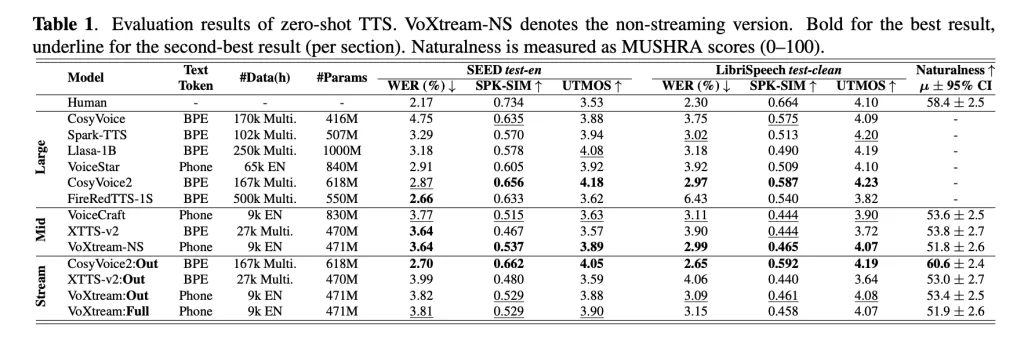
Desk 1 (Zero Shot TTS) exhibits that Voxtream is aggressive w, utmos (MOS predictor), and Speaker similarity Crossing Seed-TTS Check-en and Librispeech Check Clear; Analysis group may also perform the undertaking Ablation:addition CSM Depth Transformer and Speaker encoder Particularly, the similarity improves with no vital WER penalty in comparison with peeled baseline. Subjective research use Mushura-like protocols tailor-made to full-stream technology and second-stage desire exams.
The place is that this land situated within the TTS panorama?
In line with analysis papers, place a Voxtream between current instances Interleaved AR + NAR vocoder Strategy and lm-codec stack. Core contributions should not new codecs or big fashions. it’s Latency-centered AR structure Plus a Period token alignment It will likely be saved Enter facet streaming. When constructing a dwell agent, the necessary trade-offs are specific. A slight lower in speaker similarity and Low order fpl Greater than chunked NAR vocoder in full stream situations.
Please examine paper, Hug model, github page and Project Page. Please be happy to examine GitHub pages for tutorials, code and notebooks. Additionally, please be happy to comply with us Twitter And do not forget to hitch us 100k+ ml subreddit And subscribe Our Newsletter.
For content material partnerships/promotions on MarkTechPost.com, please Please talk to us
Asif Razzaq is CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, ASIF is dedicated to leveraging the probabilities of synthetic intelligence for social advantages. His newest efforts are the launch of MarkTechPost, a synthetic intelligence media platform. That is distinguished by its detailed protection of machine studying and deep studying information, and is straightforward to grasp by a technically sound and huge viewers. The platform has over 2 million views every month, indicating its recognition amongst viewers.
🔥[Recommended Read] Nvidia AI Open-Sources Vipe (Video Pause Engine): A strong and versatile 3D video annotation software for spatial AI