
This publish is co-written with Kostia Kofman and Jenny Tokar from Reserving.com.
As a worldwide chief within the on-line journey trade, Booking.com is all the time looking for progressive methods to reinforce its providers and supply clients with tailor-made and seamless experiences. The Rating workforce at Reserving.com performs a pivotal position in making certain that the search and advice algorithms are optimized to ship the most effective outcomes for his or her customers.
Sharing in-house sources with different inside groups, the Rating workforce machine studying (ML) scientists usually encountered lengthy wait occasions to entry sources for mannequin coaching and experimentation – difficult their means to quickly experiment and innovate. Recognizing the necessity for a modernized ML infrastructure, the Rating workforce launched into a journey to make use of the ability of Amazon SageMaker to construct, prepare, and deploy ML fashions at scale.
Reserving.com collaborated with AWS Skilled Providers to construct an answer to speed up the time-to-market for improved ML fashions by the next enhancements:
- Decreased wait occasions for sources for coaching and experimentation
- Integration of important ML capabilities resembling hyperparameter tuning
- A diminished improvement cycle for ML fashions
Decreased wait occasions would imply that the workforce may shortly iterate and experiment with fashions, gaining insights at a a lot quicker tempo. Utilizing SageMaker on-demand accessible cases allowed for a tenfold wait time discount. Important ML capabilities resembling hyperparameter tuning and mannequin explainability have been missing on premises. The workforce’s modernization journey launched these options by Amazon SageMaker Computerized Mannequin Tuning and Amazon SageMaker Make clear. Lastly, the workforce’s aspiration was to obtain fast suggestions on every change made within the code, lowering the suggestions loop from minutes to an prompt, and thereby lowering the event cycle for ML fashions.
On this publish, we delve into the journey undertaken by the Rating workforce at Reserving.com as they harnessed the capabilities of SageMaker to modernize their ML experimentation framework. By doing so, they not solely overcame their current challenges, but in addition improved their search expertise, finally benefiting thousands and thousands of vacationers worldwide.
Strategy to modernization
The Rating workforce consists of a number of ML scientists who every must develop and take a look at their very own mannequin offline. When a mannequin is deemed profitable based on the offline analysis, it may be moved to manufacturing A/B testing. If it exhibits on-line enchancment, it may be deployed to all of the customers.
The purpose of this venture was to create a user-friendly setting for ML scientists to simply run customizable Amazon SageMaker Mannequin Constructing Pipelines to check their hypotheses with out the necessity to code lengthy and sophisticated modules.
One of many a number of challenges confronted was adapting the present on-premises pipeline resolution to be used on AWS. The answer concerned two key parts:
- Modifying and lengthening current code – The primary a part of our resolution concerned the modification and extension of our current code to make it appropriate with AWS infrastructure. This was essential in making certain a clean transition from on-premises to cloud-based processing.
- Shopper bundle improvement – A consumer bundle was developed that acts as a wrapper round SageMaker APIs and the beforehand current code. This bundle combines the 2, enabling ML scientists to simply configure and deploy ML pipelines with out coding.
SageMaker pipeline configuration
Customizability is essential to the mannequin constructing pipeline, and it was achieved by config.ini, an in depth configuration file. This file serves because the management heart for all inputs and behaviors of the pipeline.
Out there configurations inside config.ini embrace:
- Pipeline particulars – The practitioner can outline the pipeline’s title, specify which steps ought to run, decide the place outputs ought to be saved in Amazon Easy Storage Service (Amazon S3), and choose which datasets to make use of
- AWS account particulars – You may determine which Area the pipeline ought to run in and which position ought to be used
- Step-specific configuration – For every step within the pipeline, you possibly can specify particulars such because the quantity and kind of cases to make use of, together with related parameters
The next code exhibits an instance configuration file:
config.ini is a version-controlled file managed by Git, representing the minimal configuration required for a profitable coaching pipeline run. Throughout improvement, native configuration information that aren’t version-controlled could be utilized. These native configuration information solely must include settings related to a selected run, introducing flexibility with out complexity. The pipeline creation consumer is designed to deal with a number of configuration information, with the newest one taking priority over earlier settings.
SageMaker pipeline steps
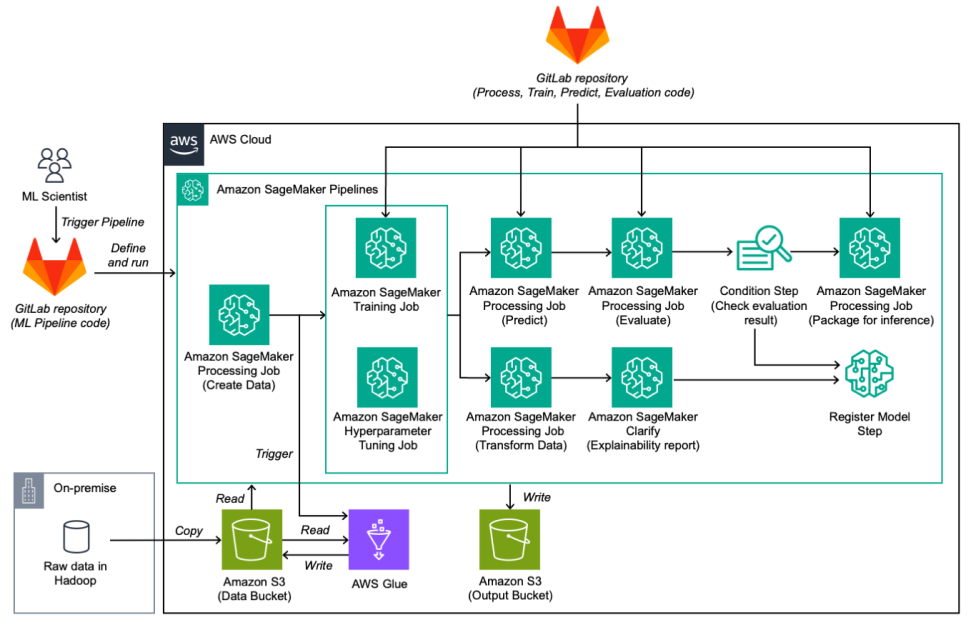
The pipeline is split into the next steps:
- Practice and take a look at information preparation – Terabytes of uncooked information are copied to an S3 bucket, processed utilizing AWS Glue jobs for Spark processing, leading to information structured and formatted for compatibility.
- Practice – The coaching step makes use of the TensorFlow estimator for SageMaker coaching jobs. Coaching happens in a distributed method utilizing Horovod, and the ensuing mannequin artifact is saved in Amazon S3. For hyperparameter tuning, a hyperparameter optimization (HPO) job could be initiated, selecting the right mannequin primarily based on the target metric.
- Predict – On this step, a SageMaker Processing job makes use of the saved mannequin artifact to make predictions. This course of runs in parallel on accessible machines, and the prediction outcomes are saved in Amazon S3.
- Consider – A PySpark processing job evaluates the mannequin utilizing a customized Spark script. The analysis report is then saved in Amazon S3.
- Situation – After analysis, a choice is made relating to the mannequin’s high quality. This choice is predicated on a situation metric outlined within the configuration file. If the analysis is constructive, the mannequin is registered as accepted; in any other case, it’s registered as rejected. In each instances, the analysis and explainability report, if generated, are recorded within the mannequin registry.
- Bundle mannequin for inference – Utilizing a processing job, if the analysis outcomes are constructive, the mannequin is packaged, saved in Amazon S3, and made prepared for add to the interior ML portal.
- Clarify – SageMaker Make clear generates an explainability report.
Two distinct repositories are used. The primary repository comprises the definition and construct code for the ML pipeline, and the second repository comprises the code that runs inside every step, resembling processing, coaching, prediction, and analysis. This dual-repository method permits for larger modularity, and permits science and engineering groups to iterate independently on ML code and ML pipeline parts.
The next diagram illustrates the answer workflow.

Computerized mannequin tuning
Coaching ML fashions requires an iterative method of a number of coaching experiments to construct a sturdy and performant closing mannequin for enterprise use. The ML scientists have to pick the suitable mannequin sort, construct the right enter datasets, and modify the set of hyperparameters that management the mannequin studying course of throughout coaching.
The choice of applicable values for hyperparameters for the mannequin coaching course of can considerably affect the ultimate efficiency of the mannequin. Nonetheless, there isn’t any distinctive or outlined option to decide which values are applicable for a selected use case. More often than not, ML scientists might want to run a number of coaching jobs with barely completely different units of hyperparameters, observe the mannequin coaching metrics, after which attempt to choose extra promising values for the following iteration. This technique of tuning mannequin efficiency is also called hyperparameter optimization (HPO), and might at occasions require tons of of experiments.
The Rating workforce used to carry out HPO manually of their on-premises setting as a result of they may solely launch a really restricted variety of coaching jobs in parallel. Subsequently, they needed to run HPO sequentially, take a look at and choose completely different combos of hyperparameter values manually, and recurrently monitor progress. This extended the mannequin improvement and tuning course of and restricted the general variety of HPO experiments that might run in a possible period of time.
With the transfer to AWS, the Rating workforce was ready to make use of the automated mannequin tuning (AMT) function of SageMaker. AMT permits Rating ML scientists to robotically launch tons of of coaching jobs inside hyperparameter ranges of curiosity to search out the most effective performing model of the ultimate mannequin based on the chosen metric. The Rating workforce is now ready select between 4 completely different automated tuning methods for his or her hyperparameter choice:
- Grid search – AMT will count on all hyperparameters to be categorical values, and it’ll launch coaching jobs for every distinct categorical mixture, exploring your complete hyperparameter area.
- Random search – AMT will randomly choose hyperparameter values combos inside supplied ranges. As a result of there isn’t any dependency between completely different coaching jobs and parameter worth choice, a number of parallel coaching jobs could be launched with this methodology, rushing up the optimum parameter choice course of.
- Bayesian optimization – AMT makes use of Bayesian optimization implementation to guess the most effective set of hyperparameter values, treating it as a regression drawback. It can contemplate beforehand examined hyperparameter combos and its affect on the mannequin coaching jobs with the brand new parameter choice, optimizing for smarter parameter choice with fewer experiments, however it’ll additionally launch coaching jobs solely sequentially to all the time have the ability to study from earlier trainings.
- Hyperband – AMT will use intermediate and closing outcomes of the coaching jobs it’s operating to dynamically reallocate sources in the direction of coaching jobs with hyperparameter configurations that present extra promising outcomes whereas robotically stopping people who underperform.
AMT on SageMaker enabled the Rating workforce to scale back the time spent on the hyperparameter tuning course of for his or her mannequin improvement by enabling them for the primary time to run a number of parallel experiments, use automated tuning methods, and carry out double-digit coaching job runs inside days, one thing that wasn’t possible on premises.
Mannequin explainability with SageMaker Make clear
Mannequin explainability permits ML practitioners to know the character and habits of their ML fashions by offering beneficial insights for function engineering and choice selections, which in flip improves the standard of the mannequin predictions. The Rating workforce needed to judge their explainability insights in two methods: perceive how function inputs have an effect on mannequin outputs throughout their whole dataset (world interpretability), and in addition have the ability to uncover enter function affect for a selected mannequin prediction on an information focal point (native interpretability). With this information, Rating ML scientists could make knowledgeable selections on learn how to additional enhance their mannequin efficiency and account for the difficult prediction outcomes that the mannequin would sometimes present.
SageMaker Make clear allows you to generate mannequin explainability reviews utilizing Shapley Additive exPlanations (SHAP) when coaching your fashions on SageMaker, supporting each world and native mannequin interpretability. Along with mannequin explainability reviews, SageMaker Make clear helps operating analyses for pre-training bias metrics, post-training bias metrics, and partial dependence plots. The job can be run as a SageMaker Processing job inside the AWS account and it integrates immediately with the SageMaker pipelines.
The worldwide interpretability report can be robotically generated within the job output and displayed within the Amazon SageMaker Studio setting as a part of the coaching experiment run. If this mannequin is then registered in SageMaker mannequin registry, the report can be moreover linked to the mannequin artifact. Utilizing each of those choices, the Rating workforce was in a position to simply observe again completely different mannequin variations and their behavioral modifications.
To discover enter function affect on a single prediction (native interpretability values), the Rating workforce enabled the parameter save_local_shap_values within the SageMaker Make clear jobs and was in a position to load them from the S3 bucket for additional analyses within the Jupyter notebooks in SageMaker Studio.

The previous photographs present an instance of how a mannequin explainability would appear like for an arbitrary ML mannequin.
Coaching optimization
The rise of deep studying (DL) has led to ML changing into more and more reliant on computational energy and huge quantities of information. ML practitioners generally face the hurdle of effectively utilizing sources when coaching these complicated fashions. While you run coaching on giant compute clusters, varied challenges come up in optimizing useful resource utilization, together with points like I/O bottlenecks, kernel launch delays, reminiscence constraints, and underutilized sources. If the configuration of the coaching job shouldn’t be fine-tuned for effectivity, these obstacles may end up in suboptimal {hardware} utilization, extended coaching durations, and even incomplete coaching runs. These elements enhance venture prices and delay timelines.
Profiling of CPU and GPU utilization helps perceive these inefficiencies, decide the {hardware} useful resource consumption (time and reminiscence) of the assorted TensorFlow operations in your mannequin, resolve efficiency bottlenecks, and, finally, make the mannequin run quicker.
Rating workforce used the framework profiling function of Amazon SageMaker Debugger (now deprecated in favor of Amazon SageMaker Profiler) to optimize these coaching jobs. This lets you observe all actions on CPUs and GPUs, resembling CPU and GPU utilizations, kernel runs on GPUs, kernel launches on CPUs, sync operations, reminiscence operations throughout GPUs, latencies between kernel launches and corresponding runs, and information switch between CPUs and GPUs.
Rating workforce additionally used the TensorFlow Profiler function of TensorBoard, which additional helped profile the TensorFlow mannequin coaching. SageMaker is now additional built-in with TensorBoard and brings the visualization instruments of TensorBoard to SageMaker, built-in with SageMaker coaching and domains. TensorBoard lets you carry out mannequin debugging duties utilizing the TensorBoard visualization plugins.
With the assistance of those two instruments, Rating workforce optimized the their TensorFlow mannequin and have been in a position to establish bottlenecks and scale back the common coaching step time from 350 milliseconds to 140 milliseconds on CPU and from 170 milliseconds to 70 milliseconds on GPU, speedups of 60% and 59%, respectively.
Enterprise outcomes
The migration efforts centered round enhancing availability, scalability, and elasticity, which collectively introduced the ML setting in the direction of a brand new degree of operational excellence, exemplified by the elevated mannequin coaching frequency and decreased failures, optimized coaching occasions, and superior ML capabilities.
Mannequin coaching frequency and failures
The variety of month-to-month mannequin coaching jobs elevated fivefold, resulting in considerably extra frequent mannequin optimizations. Moreover, the brand new ML setting led to a discount within the failure charge of pipeline runs, dropping from roughly 50% to twenty%. The failed job processing time decreased drastically, from over an hour on common to a negligible 5 seconds. This has strongly elevated operational effectivity and decreased useful resource wastage.
Optimized coaching time
The migration introduced with it effectivity will increase by SageMaker-based GPU coaching. This shift decreased mannequin coaching time to a fifth of its earlier length. Beforehand, the coaching processes for deep studying fashions consumed round 60 hours on CPU; this was streamlined to roughly 12 hours on GPU. This enchancment not solely saves time but in addition expedites the event cycle, enabling quicker iterations and mannequin enhancements.
Superior ML capabilities
Central to the migration’s success is using the SageMaker function set, encompassing hyperparameter tuning and mannequin explainability. Moreover, the migration allowed for seamless experiment monitoring utilizing Amazon SageMaker Experiments, enabling extra insightful and productive experimentation.
Most significantly, the brand new ML experimentation setting supported the profitable improvement of a brand new mannequin that’s now in manufacturing. This mannequin is deep studying somewhat than tree-based and has launched noticeable enhancements in on-line mannequin efficiency.
Conclusion
This publish supplied an summary of the AWS Skilled Providers and Reserving.com collaboration that resulted within the implementation of a scalable ML framework and efficiently diminished the time-to-market of ML fashions of their Rating workforce.
The Rating workforce at Reserving.com realized that migrating to the cloud and SageMaker has proved helpful, and that adapting machine studying operations (MLOps) practices permits their ML engineers and scientists to deal with their craft and enhance improvement velocity. The workforce is sharing the learnings and work achieved with your complete ML group at Reserving.com, by talks and devoted classes with ML practitioners the place they share the code and capabilities. We hope this publish can function one other option to share the information.
AWS Skilled Providers is able to assist your workforce develop scalable and production-ready ML in AWS. For extra data, see AWS Skilled Providers or attain out by your account supervisor to get in contact.
Concerning the Authors
 Laurens van der Maas is a Machine Studying Engineer at AWS Skilled Providers. He works intently with clients constructing their machine studying options on AWS, focuses on distributed coaching, experimentation and accountable AI, and is enthusiastic about how machine studying is altering the world as we all know it.
 Daniel Zagyva is a Information Scientist at AWS Skilled Providers. He focuses on growing scalable, production-grade machine studying options for AWS clients. His expertise extends throughout completely different areas, together with pure language processing, generative AI and machine studying operations.
 Kostia Kofman is a Senior Machine Studying Supervisor at Reserving.com, main the Search Rating ML workforce, overseeing Reserving.com’s most in depth ML system. With experience in Personalization and Rating, he thrives on leveraging cutting-edge know-how to reinforce buyer experiences.
 Jenny Tokar is a Senior Machine Studying Engineer at Reserving.com’s Search Rating workforce. She focuses on growing end-to-end ML pipelines characterised by effectivity, reliability, scalability, and innovation. Jenny’s experience empowers her workforce to create cutting-edge rating fashions that serve thousands and thousands of customers day by day.
 Aleksandra Dokic is a Senior Information Scientist at AWS Skilled Providers. She enjoys supporting clients to construct progressive AI/ML options on AWS and he or she is happy about enterprise transformations by the ability of information.
 Luba Protsiva is an Engagement Supervisor at AWS Skilled Providers. She focuses on delivering Information and GenAI/ML options that allow AWS clients to maximise their enterprise worth and speed up pace of innovation.