
The North Star
Each group racing to deploy AI brokers faces the identical reckoning: an agent that demos fantastically can quietly degrade in manufacturing, and by the point a human notices, the belief is already damaged. The place conventional software program fails loudly, brokers fail softly. They return a solution that appears assured, reads fluently, and is incorrect. When that reply drives an actual enterprise determination, the fee isn’t a damaged function. It’s a damaged relationship with the consumer.
That’s the standard drawback at its core. The problem is subsequently not constructing brokers that work as soon as, however proving they preserve working, at scale, throughout each sub-agent, each workflow, and each launch. The groups that win the agent period would be the ones who deal with high quality not as a remaining QA step however because the working system of the agent itself: constantly measured, robotically defended, and improved with each interplay. On this publish, we present how we constructed a steady high quality loop for production-ready agentic options at scale utilizing Amazon Bedrock AgentCore.
Enterprise drawback
The answer makes use of Amazon Bedrock AgentCore and different AWS providers for inside use, so sellers and gross sales leaders can ask enterprise questions in plain English from Amazon Fast. Behind that single expertise, a number of specialised sub-agents work collectively: the Efficiency Insights Agent for territory-scoped income and efficiency, the Buyer Insights Agent for buyer intelligence, the Knowledge Insights Agent for text-to-SQL over foundational datasets, and direct dashboard entry. Solutions are scoped to every consumer’s territory and role-level safety. Subject groups use these solutions to help in planning account technique, put together for buyer conferences, so the numbers have to be proper. Probably the most damaging failure isn’t a crash. It’s a fluent, assured reply that’s quietly incorrect. Earlier than launch, once we evaluated the Buyer Insights Agent, we discovered precisely that:
- It reported $410.08 of a buyer’s three-month income on a service as “$410.08 Million.”
- It reported Gross sales Income labeled as Gross sales Income excluding Changes.
- It supplied an Annual Recurring Income estimate that appeared nowhere within the knowledge.
- It introduced its personal calculations as sourced details.
Via the completely different runs, monitoring stayed inexperienced. It advised us the system had responded, not whether or not the reply was proper.
Had these errors shipped uncaught, the sector would have paid for them. A vendor who repeats an inflated determine can lose credibility with the shopper. That is precisely why we caught it earlier than launch. The danger doesn’t finish at launch: it grows with each new agent and each change to knowledge, prompts, code, or fashions. It additionally grows with none launch, as a result of upstream pipelines refresh the info each week. Coordinated releases introduce a associated threat: when a knowledge change, a software change, and a paired immediate replace are supposed to ship collectively however land aside, the system runs mismatched till all adjustments catch up. In a single pre-production check, that mismatch window by itself dropped the move fee from 78 % to 38 %. To catch failures like these, earlier than each launch and constantly in manufacturing, we’d like a framework that may present whether or not solutions are grounded and proper, and hint every failure again to its root trigger within the knowledge, the immediate, or the agent’s code.
At AWS, the Gross sales, Advertising and marketing, and World Providers (SMGS) Operations staff developed a manufacturing multi-agent system serving AWS Subject Gross sales worldwide. It serves two distinct audiences. For area gross sales groups, it replaces hours of handbook knowledge evaluation with on-demand, conversational intelligence, serving to sellers perceive the well being of their enterprise, floor dangers and alternatives, and take motion sooner. For management, it powers enterprise administration cadences together with Weekly Enterprise Critiques (WBRs), surfacing the indicators that matter throughout the portfolio with out requiring handbook report preparation. The identical agentic system serves each the vendor on the entrance line and the chief reviewing efficiency at scale.
The agentic system orchestrates a rising portfolio of specialised sub-agents, every proudly owning a definite functionality area. Amongst them: the Efficiency Insights Agent generates natural-language enterprise intelligence narratives from complicated gross sales knowledge, turning uncooked metrics into actionable vendor insights. The Buyer Insights Agent assembles a 360-degree view of every buyer by synthesizing indicators throughout product utilization, assist historical past, contract standing, and engagement knowledge, serving to sellers perceive the place a buyer is of their journey and what they want subsequent. The Knowledge Insights Agent is a text-to-SQL agent that account groups use to question structured analytics knowledge in plain English with out writing a single line of SQL. These three brokers are those referenced all through the remainder of this publish.
Coordinating these brokers reliably at scale made one factor clear: agentic high quality wasn’t an operational concern to handle later. It was the prerequisite for working. A single degraded sub-agent can silently corrupt each response downstream, and conventional monitoring gained’t catch it. That actuality made a full lifecycle analysis framework not non-obligatory however obligatory. AgentCore Evaluations, a functionality of Amazon Bedrock AgentCore, is the connective tissue powering it, alongside Amazon Bedrock Guardrails (security), Amazon CloudWatch (metrics, alarms, tracing), Amazon Easy Storage Service (Amazon S3) and Amazon Redshift (analysis persistence), Amazon Fast (dashboards), and AWS Lambda ({custom} evaluators).
On this publish, we share how we tackled the toughest operational challenges in working AI brokers at enterprise scale, and the way Amazon Bedrock AgentCore Evaluations grew to become the spine of agent high quality. Particularly, we cowl:
- Brokers play by completely different guidelines – Why brokers demand a unique operational self-discipline, and why conventional monitoring (latency, error charges, uptime) leaves you blind to the failures that matter most.
- A map for the entire journey – The nine-stage analysis framework we constructed on AgentCore Evaluations, overlaying each section of the agent improvement lifecycle from first decide to manufacturing.
- From concept to observe – Concrete patterns (steady integration and steady supply (CI/CD) regression gates, canary scoring, drift detection, and automatic suggestions loops) and precisely how AgentCore Evaluations powers every one.
- Metrics that really matter – The measurable influence on deployment confidence, regression prevention, and iteration velocity throughout our agent portfolio.
Why brokers want a structured analysis framework
Conventional software program is deterministic: the identical enter produces the identical output. Machine studying (ML) fashions launched probabilistic outputs, and MLOps emerged to handle their coaching, versioning, monitoring, and re-training. AI brokers add a 3rd layer of operational complexity: autonomous, multi-step reasoning, the place the query shifts from “did one thing break?” to “is the agent making sound selections throughout its whole reasoning chain?”
Brokers inherit the onerous issues of each predecessors, and introduce some new ones. They’re non-deterministic, following completely different reasoning paths for similar inputs. They make cascading selections throughout routing, software choice, and synthesis, the place a single step can fail quietly and corrupt every part downstream. Most critically, they degrade silently: latency stays low, error charges keep flat, but the standard of agent response erodes, as a result of the agent remains to be responding. It’s simply responding incorrect.
Agent analysis is the observe of catching precisely that. It spans 5 dimensions: security (is it behaving inside outlined boundaries?), high quality (is the agent producing appropriate, coherent, grounded responses?), efficiency (is it quick and dependable sufficient?), value (is it working effectively at scale?), and operational management (can we detect, diagnose, and remediate points shortly?). A mature analysis observe addresses 5 constantly, all through the complete agent lifecycle.
On this publish, we share how we operationalize 5 analysis dimensions throughout a manufacturing multi-agent system. Security and safety is our first precedence. No agent ships, and no agent retains working, if it will probably’t meet its security bar. High quality will get essentially the most house on this publish as a result of it’s the toughest of the 5 to get proper and advantages most from a devoted framework, but it surely doesn’t outrank security. Efficiency, value, and operational management are woven into each stage of the lifecycle alongside each. Critically, this framework applies at each stage of the agent hierarchy. On the software stage, every functionality (a buyer disambiguation software, graph retrieval software) has its personal analysis contract. On the agent stage, every sub-agent is evaluated end-to-end. On the multi-agent stage, orchestration paths are evaluated for coherence, appropriate routing, and synthesis accuracy throughout agent boundaries.
The 9 levels apply at three ranges concurrently, and this hierarchy isn’t particular to this product. It’s the best psychological mannequin once we construct or combine new manufacturing brokers. Most groups begin by evaluating on the agent stage and cease there. However agent-level high quality is simply pretty much as good because the instruments it depends on, and multi-agent programs introduce a 3rd failure floor that neither stage can see alone. A strong analysis observe covers three, with every stage working its personal golden set, its personal evaluators, and its personal promotion standards by way of the 9 levels.
The agent analysis framework: 9 levels, one closed loop
These 9 levels hint the agent lifecycle from first decide to stay manufacturing, and every one solutions a query groups face as their brokers mature.
The agent lifecycle and the 9 frequent questions
Each staff constructing manufacturing brokers encounters the next questions as their agent matures:
Stage 1: The Basis: “What does good appear like?”
Stage 2: The Experiment: “Which model is healthier?”
Stage 3: The Merge (CI): “Did I break one thing?”
Stage 4: The Gate (CD): “Is it protected for manufacturing?”
Stage 5: The Canary: “Did one thing silently break?”
Stage 6: The Adversary: “What if somebody tries to interrupt it?”
Stage 7: The Drift: “Is high quality drifting in stay?”
Stage 8: The Pulse: “How do we all know it’s working proper now?”
Stage 9: The Suggestions Loop: “How does it get higher robotically?”
We construct one framework for each stage of the agent lifecycle utilizing AgentCore Evaluations. The 9 levels should not separate instruments stitched collectively after the actual fact. They’re 9 factors on a single, steady analysis floor, powered by AgentCore Evaluations from first decide to manufacturing response, as proven in Determine 1.
Right here’s how we deal with every one: the sample that works, the AgentCore providers behind it, and what it appears to be like like working in manufacturing, proven in system design in Determine 2.

Determine 2: System design of the AgentCore analysis framework
Stage 1: The Basis. Outline high quality
The inspiration of evaluating an agent isn’t about choosing the proper instruments. It’s about asking the best query: what does success appear like for this agent, and the way do we all know when it’s failing? The reply should come from the shopper, not from the mannequin. That is an iterative course of. Our definition of success has sharpened as we observe what the agent really does in manufacturing. All the pieces outlined right here (failure thresholds, evaluator stack, golden set, security guidelines, latency budgets, and price targets) is the contract each subsequent stage enforces. If Stage 1 is imprecise, each downstream gate is guessing.
Stage 1.1: Outline your corporation metrics first. Begin by asking what the agent exists to ship. The 2 finish consumer personas outline success in another way:
- For sellers, success means strolling right into a buyer dialog with correct, present intelligence on the proper element stage and on the proper time.
- For management, success means dependable weekly and cross-business evaluate inputs with out prolonged handbook preparation. These are enterprise outcomes, not mannequin properties.
Stage 1.2: Translate these enterprise metrics into analysis metrics. For every end result, determine the sign that confirms the agent delivered it. Every sign turns into a tracked metric with an express threshold and an alarm situation. Correct account intelligence maps to entity decision accuracy and grounding fee. Vendor belief maps to faithfulness and hallucination fee. Vendor motion maps to helpfulness and scope adherence. Management evaluate reliability maps to accuracy move fee and response protection. This translation should cowl 5 dimensions: alongside high quality thresholds, outline security guardrail insurance policies, set p50, p90, and p99 latency targets per software and per agent, set up cost-per-query budgets, and outline the service stage agreements (SLAs) that decide when an alarm fires and which runbook it triggers.
For accuracy particularly, as a result of the answer instantly informs income selections, renewal methods, and government evaluations, the bar is excessive. A confidently incorrect reply doesn’t solely waste a vendor’s time. It results in a incorrect determination in an actual enterprise second. We outline six failure varieties derived from actual manufacturing errors, any considered one of which marks a response as inaccurate:
- Metric swap: appropriate buyer and interval, incorrect metric returned. Tracked as occurrences per 100 responses.
- Flawed interval: knowledge from one time window is labeled as one other, for instance a year-over-year (YoY) determine introduced to the vendor as month-over-month (MoM), or the reverse. Tracked as % citing the proper window.
- Flawed entity: conflated account names or subsidiaries. Tracked as entity decision accuracy %.
- Pure hallucination: ungrounded figures with no traceable supply. Tracked as grounding fee %.
- Flawed symbols: appropriate metric, incorrect forex or unit image. Tracked as scope adherence fee %.
- Unauthorized calculation: unsanctioned derived figures not current within the supply knowledge. Tracked as occurrences per 100 responses.
The general accuracy move fee is the headline metric. Per-dimension monitoring is what makes it actionable. Past accuracy, we additionally observe Response relevance, Faithfulness, Helpfulness, Instruction Following,Software Choice Accuracy. An accurate reply buried in three paragraphs, or arriving too late, has additionally failed the vendor.
Stage 1.3: Construct an evaluator stack that displays these metrics. No single evaluator kind covers the varied failure modes attainable. We mix 4 varieties:
- AgentCore built-in evaluators for broad baseline protection. Relevance, faithfulness, and helpfulness map on to analysis templates obtainable natively in AgentCore Evaluations.
- Custom-made evaluators, one per failure kind in our taxonomy: a metric swap evaluator, a incorrect interval evaluator, a incorrect buyer evaluator, a pure hallucination evaluator, a incorrect symbols evaluator, and an unauthorized calculation evaluator. Not one of the six are lined by native templates. They’re domain-specific indicators we constructed on prime of the AgentCore framework. Understanding upfront which metrics a local template already covers, and which require a custom-made evaluator, is itself a part of the design determination.
- Third-party evaluators, we deployed the managed evaluators from third-party open supply libraries DeepEval and AutoEval.
- Deterministic evaluators for floor reality checks the place the proper reply is understood precisely, resembling income, renewal date, and contract standing.
The place reasoning high quality and helpfulness haven’t any single appropriate reply, we use LLM-as-judge rubrics as a substitute, with built-in rubrics for relevance, faithfulness, and helpfulness plus assist for absolutely {custom} rubrics. AgentCore Evaluations supplies each floor reality and LLM-as-judge analysis natively, which is what allow us to rise up each analysis paths with out constructing both scoring engine ourselves. Deterministic offers precision on details. LLM-as-judge offers breadth on reasoning.
Stage 1.4: Construct a golden set to train your analysis metrics. On the software stage, every essential software has its personal deterministic floor reality pairs: buyer identification should resolve to the precise canonical entity or fail. On the agent stage, matter evaluation on actual consumer queries produces a dataset throughout 4 query varieties (complete, reporting, reasoning, and ambiguous), every requiring a unique analysis technique, revisited month-to-month. On the multi-agent stage, end-to-end orchestration situations catch errors that solely emerge when brokers work together. The golden set isn’t solely a high quality dataset. It additionally contains security check circumstances, latency benchmark circumstances, and price reference circumstances, so Levels 3 and 4 can verify 5 dimensions towards the identical curated dataset.
The golden set is a dwelling doc, constructed from three sources. Manufacturing-derived circumstances are sampled from actual vendor and management queries, together with the low-scoring stay classes promoted in Stage 7. Failure-derived circumstances come from each regression caught in staging or manufacturing, together with the sentinel circumstances promoted in Stage 3 and the everlasting regression guards promoted in Stage 9. Artificial edge circumstances are intentionally constructed to ensure protection of situations we all know matter however can’t wait to come across within the wild, such because the 4 query varieties above and the parent-subsidiary and ticker-symbol disambiguation circumstances in Stage 4. The set is version-controlled, reviewed, and constantly prolonged throughout three sources.
Stage 2: The Experiment. Know which model wins
Each change (a immediate replace, a brand new software, a mannequin improve, a dataset refresh) raises the identical query: is that this model really higher? In a system serving the AWS area at international scale, instinct isn’t a suitable reply.
Earlier than a change merges, we run an AgentCore On-Demand Analysis, scored towards the identical golden set with the identical evaluator suite. The event staff makes use of the standard, latency, value metrics, and context token, to curate downstream comparisons which is evaluated throughout 5 dimensions concurrently, as proven aspect by aspect in Determine 3. A mannequin that improves accuracy by 5 % however doubles latency and triples value doesn’t robotically win.
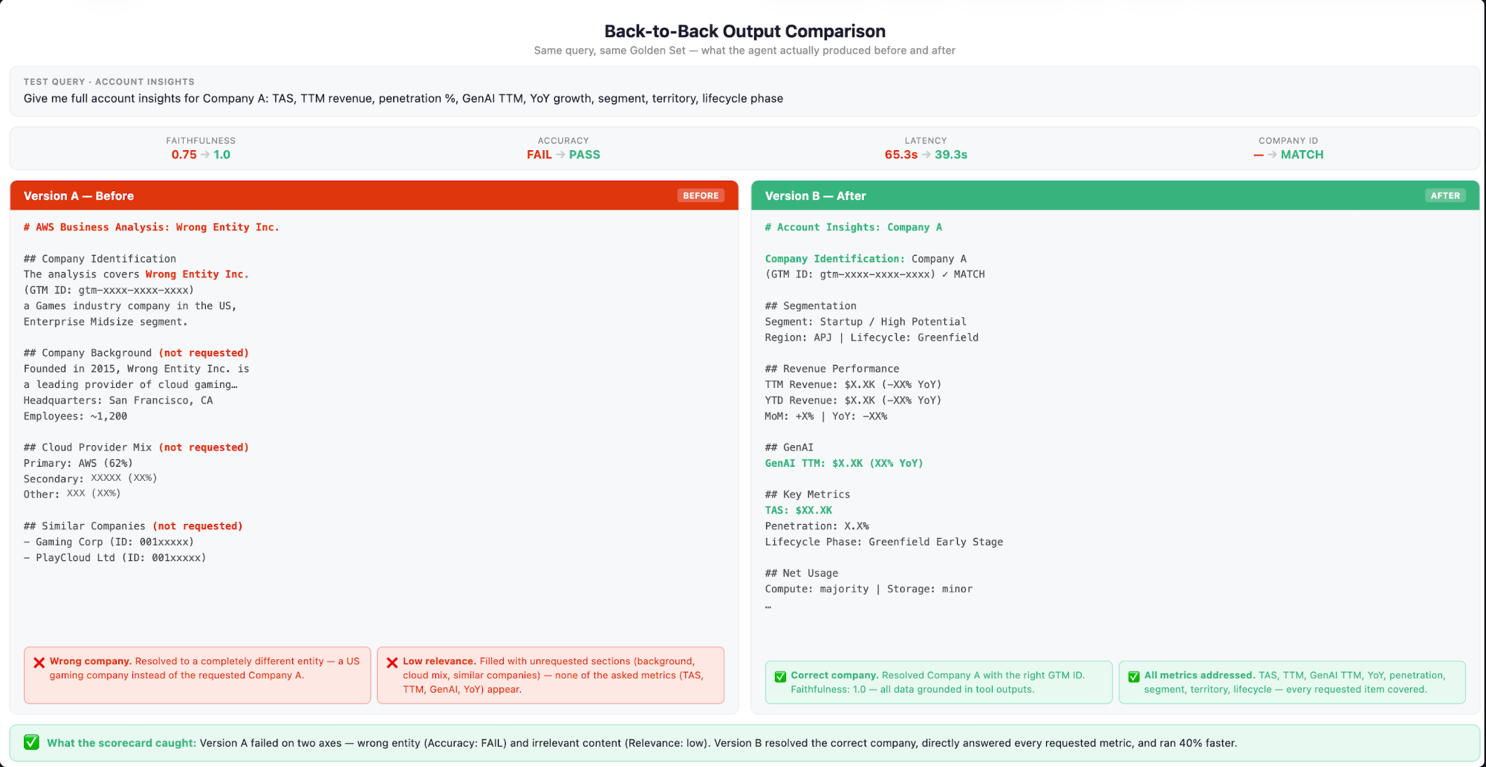
Determine 3: Facet-by-side comparability of two candidate agent responses in an AgentCore On-Demand Analysis throughout high quality, latency, and price. The numbers and values within the determine are illustrative.
We observe high quality as a complete scorecard, not one single quantity. A move fee alone doesn’t inform you sufficient. Every eval run produces a full breakdown throughout each failure class in our taxonomy: not simply whether or not high quality improved, however the place and why, as captured within the scorecard in Determine 4. Each analysis can be absolutely recorded: inputs, outputs, retrieved context, scores and analysis causes are saved in S3 and our knowledge lake, giving us a persistent observability layer to hint failure again to its root trigger: what the agent noticed, what it generated, and why it went incorrect. Over three months of focused iteration, this scorecard drove move fee from 93 % to a secure 96 %: pure hallucinations dropped from 138 to beneath 52 per 10,000 responses, unauthorized calculations fell from 59 to beneath 44, confirming that retrieval was sound and the features got here from era fixes. With out the per-category breakdown and the detailed hint knowledge behind it, we’d have been iterating blind.
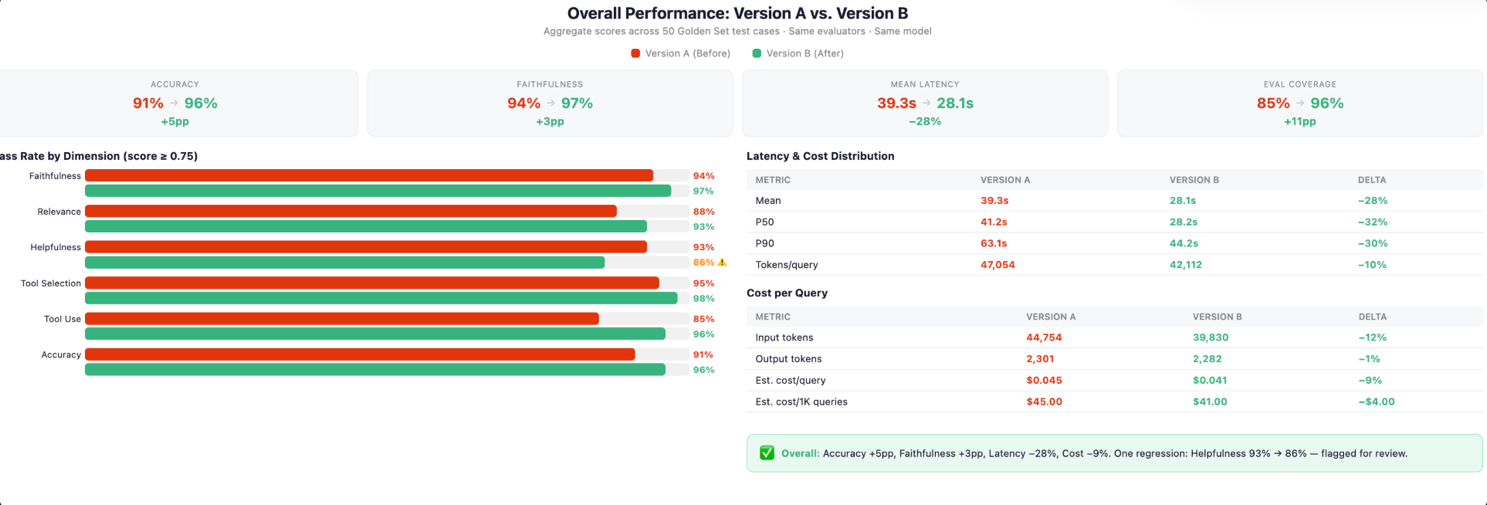
Determine 4: Analysis scorecard with per-category failure breakdown and pass-rate pattern. The numbers and values within the determine are illustrative.
Stage 3: The Merge (CI). Forestall regression at merge time
Stage 3 is a pre-production gate. It runs within the staging atmosphere, triggered by code and configuration adjustments, and its job is to dam a nasty change earlier than it ever reaches manufacturing. If Stage 3 catches a regression, nothing ships.
Engineers or scientists change the system in some ways: the immediate, the underlying knowledge, the instruments, or the mannequin. The change appears to be like clear domestically, exams move, however a immediate that improves responses for expertise accounts might silently degrade responses for monetary providers accounts. With out an automatic gate, this ships.
Our CI analysis is triggered robotically on each staging deployment utilizing AgentCore On-Demand Analysis. Engineers don’t want to recollect to run an analysis. No deployment can silently skip the gate. The run completes in minutes as a result of it evaluates solely the sentinel set, not the complete golden set. Velocity is intentional: the sentinel is slender sufficient to run on each deployment however consultant sufficient to catch the failures that matter most.
The sentinel set is a curated choice of the highest-risk situations throughout 5 dimensions. High quality regressions past tolerance block the deployment. A security boundary violation blocks simply as onerous. A change that doubles p90 latency doesn’t proceed with no deliberate determination. Token value spikes are flagged earlier than they compound at scale. Each sentinel run publishes its scores to CloudWatch as {custom} metrics alongside high quality scores, latency, value per question, and security move fee are all emitted after each run, and CloudWatch alarms are configured to fireplace if any metric breaches its Stage 1 threshold. Each run can be logged and saved, feeding the audit path Stage 8 and Stage 9 depend on. We keep a separate sentinel at every stage: software, agent, and multi-agent. A change that improves agent-level high quality however degrades a essential software nonetheless blocks. The sentinel is reviewed month-to-month, and a regression that slips by way of to manufacturing is instantly promoted right into a everlasting case so it doesn’t attain customers twice.
One instance of what this catches. After a knowledge normalization replace, a disambiguation software began returning unresolved entities for a subset of account title codecs. The agent, receiving an unresolved entity, responded with a best-guess match, returning actual knowledge for the incorrect buyer. Our tool-level sentinel contains precisely this class of edge case: the entity decision floor reality verify failed for the affected account title codecs, and the deployment was blocked robotically. The change by no means reached manufacturing.
Stage 4: The Gate (CD). Ship with quantitative confidence
The sentinel covers 15 circumstances. Manufacturing covers tens of 1000’s of question patterns throughout a whole bunch of account varieties, geographies, and vendor segments. Clearing the sentinel is critical. It’s not adequate.
Earlier than a candidate ships, we run an AgentCore On-Demand Analysis towards the complete golden set throughout the evaluator dimensions. We name this the High quality Gate. It replaces “it appears advantageous” with a quantitative delivery determination.
Sandboxed execution and power mocking. Consider it as a replay, not a stay name. Forward of time, we freeze a recognized, versioned dataset of appropriate software conduct. Each software name the candidate makes through the gate is intercepted and answered from that frozen dataset as a substitute of an actual system. We construct that frozen dataset in two steps. First, we check every software by itself: we ship it a held-out set of inputs from our golden set the place the proper reply is already recognized, and rating what it really returns towards that recognized reply. This tells us whether or not the software itself works (entity decision, retrieval, SQL era) earlier than the agent is even concerned. Second, after a software’s responses are confirmed appropriate, we freeze those self same validated solutions into the replay dataset the agent sees throughout gate analysis. Meaning the agent is examined purely by itself reasoning, not on stay software velocity or availability, and since each candidate replays from the identical frozen dataset, any rating distinction head-to-head is concerning the agent, not software variance.
Aggregated end-to-end scoring. The gate additionally runs a holistic move: the complete candidate agent solutions 200 held-out questions end-to-end, scored by an LLM-as-judge rubric throughout all evaluator dimensions. Any considered one of three circumstances shuts the gate robotically: the combination rating regresses towards the candidate’s personal prior run, it fails to beat the present manufacturing baseline, or greater than an outlined proportion of the 200 questions falls beneath the per-question threshold. A candidate should clear all three, which catches what a easy common can conceal: a mannequin that improves the imply whereas quietly failing a bigger share of particular person questions doesn’t move.
One instance of what this catches. That is the place mocking exams the agent’s personal reasoning, not simply the instruments beneath it. Our golden set features a hierarchy mismatch case: the Buyer Insights Agent and Knowledge Insights Agent return completely different, individually appropriate income figures for a similar buyer, one scoped to the mother or father account, the opposite to a subsidiary. Neither quantity is incorrect. The case exams whether or not the agent infers the best scope from the question’s semantics and the requester’s persona (a vendor doubtless desires the subsidiary, whereas a management question doubtless desires the mother or father rollup), somewhat than defaulting, averaging, or asking the vendor to disambiguate. The candidate failed, returning the parent-level determine for a subsidiary-scoped query. The golden set’s floor reality for this case specifies which scope the query expects, so the High quality Gate flagged the mismatch instantly: not a incorrect quantity, however the best quantity for the incorrect scope.
Stage 5: The Canary. Catch silent post-deploy failures
Stage 5 is a post-production monitor. It runs constantly within the manufacturing atmosphere towards stay visitors and artificial analysis circumstances, and its job is to catch points that no code change triggered and that Stage 3 subsequently didn’t see. Stage 3 guards towards what engineers change. Stage 5 guards towards every part else like upstream knowledge shifts, evolving mannequin conduct, adjustments in third-party dependencies, or different circumstances resembling elevated latency or shifting visitors patterns that solely manifest beneath real-world load.
The product operates towards a knowledge property fed by 1000’s of upstream schemas and knowledge pipelines. On a given day, dozens of these pipelines refresh with out triggering a deployment or CI gate. The agent code is unchanged, the mannequin is unchanged, however the knowledge it causes over has modified, and high quality can degrade silently because of this. We discovered this the onerous means: an upstream pipeline refreshed with a schema change, the agent began citing knowledge from the incorrect time window, and the primary sign got here by way of a vendor inquiry somewhat than an automatic alert. Stage 5 is how we catch this within the first 30-minute analysis window as a substitute.
We run AgentCore Batch Analysis on two complementary schedules, and the selection of cadence was deliberate.
We settled on 30-minute cycles after studying from each instructions: quarter-hour generated too many false alarms; 60 minutes let two hours move earlier than an actual degradation registered. We name every 30-minute cycle an analysis window. Thirty minutes catches an actual pattern inside 90 minutes (three consecutive home windows) whereas filtering out single-query noise. Every window scores a round-robin choice throughout the golden set, giving full protection in 24 hours.
Thresholds are intentionally decrease than CI/CD gates. A single window failure is an ops sign, not an incident. We solely web page oncall after three consecutive home windows breach threshold. We discovered this rule the onerous means: the primary month we used a single-window threshold, oncall stopped trusting the system solely. As soon as per day, the complete golden set runs at gate thresholds because the authoritative every day scorecard. The 30-minute home windows floor the pattern. The every day run confirms it and cuts a ticket.
Each run publishes to CloudWatch (accuracy, hallucination charges, grounding fee, latency, and price), with alarm logic that distinguishes between the 2 cadences. The canary runs at three ranges: tool-level scores floor a degraded retrieval software earlier than it corrupts agent-level responses.
One other instance of what this catches. After an upstream index refresh, a retrieval software started returning loosely related chunks as a substitute of the exact context wanted to reply the question. Latency was nominal. Error fee was zero. The agent saved producing fluent, assured responses by reasoning over weakly grounded context, producing solutions that seemed appropriate however cited the incorrect figures. No infra alarm fired. The canary caught it within the first 30-minute window: grounding fee and retrieval precision dropped throughout the tool-level sentinel, triggering a CloudWatch alarm earlier than sellers acted on the degraded solutions. The low evaluator rating flagged the precise hint accountable. From there, the on-call engineer opened that hint in AgentCore and traced the degraded context again to the retrieval software in minutes.
Stage 6: The Adversary. Defend towards misuse
Not each unhealthy output comes from a degraded mannequin. Queries crafted to extract unauthorized account knowledge, and immediate injections embedded in retrieved paperwork, are predictable patterns in a system serving 1000’s of customers on delicate enterprise knowledge.
Security isn’t a stage. It runs by way of all 9 levels. We apply Amazon Bedrock Guardrails at two factors in each interplay. At enter, we validate question scope and display screen for immediate injection. At output, we confirm that no delicate knowledge is surfaced to unauthorized customers and that the agent has not been manipulated right into a coverage violation. These checks run on one hundred pc of visitors, synchronously, earlier than a response reaches the consumer.
We configure two guardrail layers, every overlaying a definite menace class:
Content material filters detect and block dangerous or inappropriate content material in each inputs and outputs. We implement filters throughout classes together with VIOLENCE, HATE, SEXUAL, MISCONDUCT, and INSULTS. A request or response that triggers these filters is blocked earlier than it reaches the vendor or is surfaced to the consumer.
Immediate safety filters shield the agent from adversarial manipulation beneath a single PROMPT_ATTACK guardrail class, overlaying three sub-types: JAILBREAK (makes an attempt to override the agent’s system directions or bypass its operational boundaries), PROMPT_INJECTION (unintended directions embedded in retrieved paperwork, software outputs, or consumer queries), and PROMPT_LEAKAGE (makes an attempt to extract the system immediate or inside configuration). In a multi-agent system that makes use of Retrieval Augmented Era (RAG), immediate injection by way of retrieved content material is an actual threat. An unintended doc in a vendor’s account knowledge might try to redirect the agent’s conduct mid-reasoning.
Security guidelines are outlined at Stage 1, checked for regressions at Levels 3 and 4, and enforced constantly in manufacturing.
Stage 7: The Drift. Maintain high quality and validate with stay visitors
High quality degrades from a number of instructions: upstream knowledge adjustments with out triggering a deployment, fashions develop stale, and customers push boundaries with queries no golden set absolutely anticipates. Stage 7 detects it earlier than sellers do, and validates candidates towards actual consumer visitors earlier than full rollout.
Drift detection. Utilizing AgentCore On-line Analysis, we pattern 10 % of stay visitors constantly by way of the completely different evaluators outlined at Stage 1, so the drift is instantly seen as a deviation from the baselines established offline. Scores feed right into a High quality-State Calculator monitoring high quality, latency, and price in the identical window.
One manufacturing instance. Our golden set for buyer identification was constructed from artificial edge circumstances: title variations, subsidiary lookups, abbreviations. It carried out effectively offline. However in stay visitors, sellers queried with inventory ticker symbols (“what’s happening with AMZN?”), shorthand names, and typos the artificial circumstances didn’t train. The High quality-State Calculator surfaced the drift throughout three consecutive 30-minute home windows: 98 % at 1:30am, 81 % at 2:00am, 80 % at 2:30am. CloudWatch paged oncall when the rolling threshold was crossed. The on-call engineer queried the agent: “What occurred to buyer identification accuracy between 1am and 3am?” and acquired a pattern abstract pinpointing ticker image lookups and shorthand names because the failure driver. The agent’s hint made the foundation trigger instantly seen. The repair: increase the golden set with the low-scoring stay classes, and replace the disambiguation software to normalize enter codecs earlier than decision. Accuracy recovered to baseline inside the subsequent analysis cycle.
Reside visitors feeds two steady enchancment loops: low-scoring classes are promoted into the golden set as new edge circumstances, and clusters of low-scoring traces inform immediate revisions, software updates, and routing changes.
A/B testing: After a candidate clears a high quality gate, AgentCore Gateway, a functionality of Amazon Bedrock AgentCore, routes a slice of actual visitors between present and candidate brokers. On-demand confirms no regression on recognized circumstances. On-line confirms it holds up towards the long-tail inputs and novel phrasings solely actual customers produce. A candidate should win or draw throughout all evaluator dimensions earlier than full rollout.
Stage 8: The Pulse. Actual-time high quality visibility
A single name to the agent would possibly contact three sub-agents, 5 instruments, and two retrieval paths. When a high quality alarm fires, “one thing within the agent pipeline” isn’t a runbook. Stage 8 is the place indicators from Levels 5, 6, and seven converge into an observability layer with sufficient decision to behave.
AgentCore Observability, a functionality of Amazon Bedrock AgentCore, is the muse. For brokers hosted on the AgentCore runtime, a functionality of Amazon Bedrock AgentCore, each execution is instrumented robotically by way of OpenTelemetry, emitting structured telemetry for each reasoning step: instruments referred to as, order, inputs and outputs, latency, and token consumption, revealed on to CloudWatch as {custom} metrics and logs, after CloudWatch Transaction Search is enabled (a one-time setup step). Evaluator scores are a separate pipeline: they arrive from analysis configs, not from execution instrumentation, and land in their very own CloudWatch log group. Each analysis run additionally persists its full outputs to S3 and our knowledge lake, feeding two dashboards:
- A conversational dashboard to question analysis and observability outcomes.
- An Amazon Fast dashboard for pattern evaluation, scorecard monitoring, and cross-agent comparisons throughout the complete historical past.
Position-appropriate views sit on prime. Oncall engineers get a trace-first view: one click on from a CloudWatch alarm to the AgentCore Observability hint that triggered it. The hint reveals each software referred to as, in what order, with latency per step, token consumption, value, and the complete reasoning context: every part wanted to go from “alarm fired” to “root trigger recognized” with out opening a second software, as proven in Determine 5.
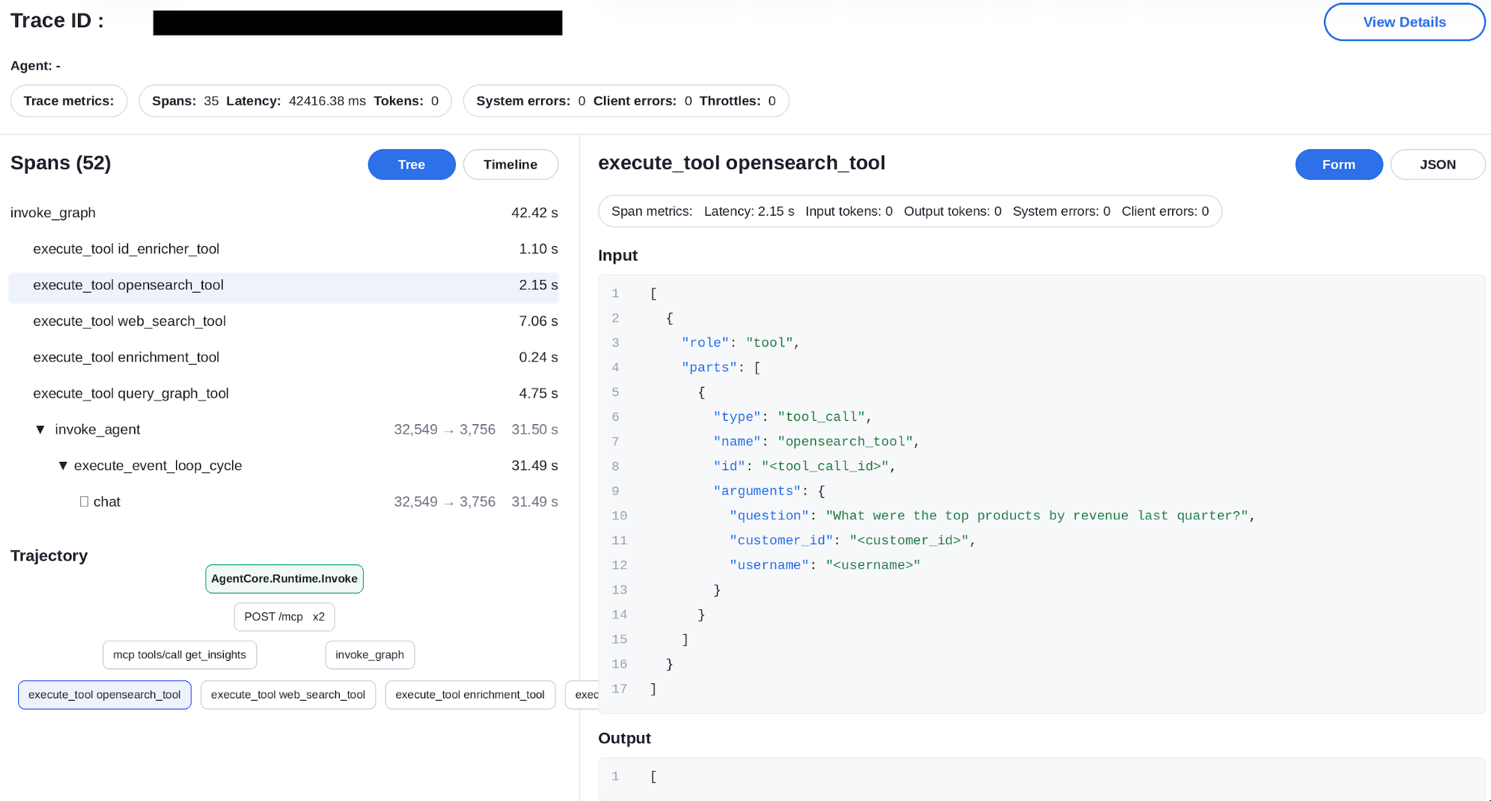
Determine 5: AgentCore execution hint for the Buyer Insights Agent, displaying the span tree, trajectory, and span-level metrics. The numbers and values within the determine are illustrative.
Product managers get Amazon Fast pattern dashboards: high quality scores by sub-agent and have, release-over-release. Management will get a single-page well being abstract aligned to weekly and cross-business evaluations throughout all 5 dimensions, a one-minute spot verify that solutions “how are our brokers performing?”
Determine 6 reveals the top-line view of our weekly analysis dashboard: one mixed move fee drawn from each {custom} evaluators and AgentCore built-in evaluators, alongside latency, for the week’s run. The numbers and values within the determine are illustrative.
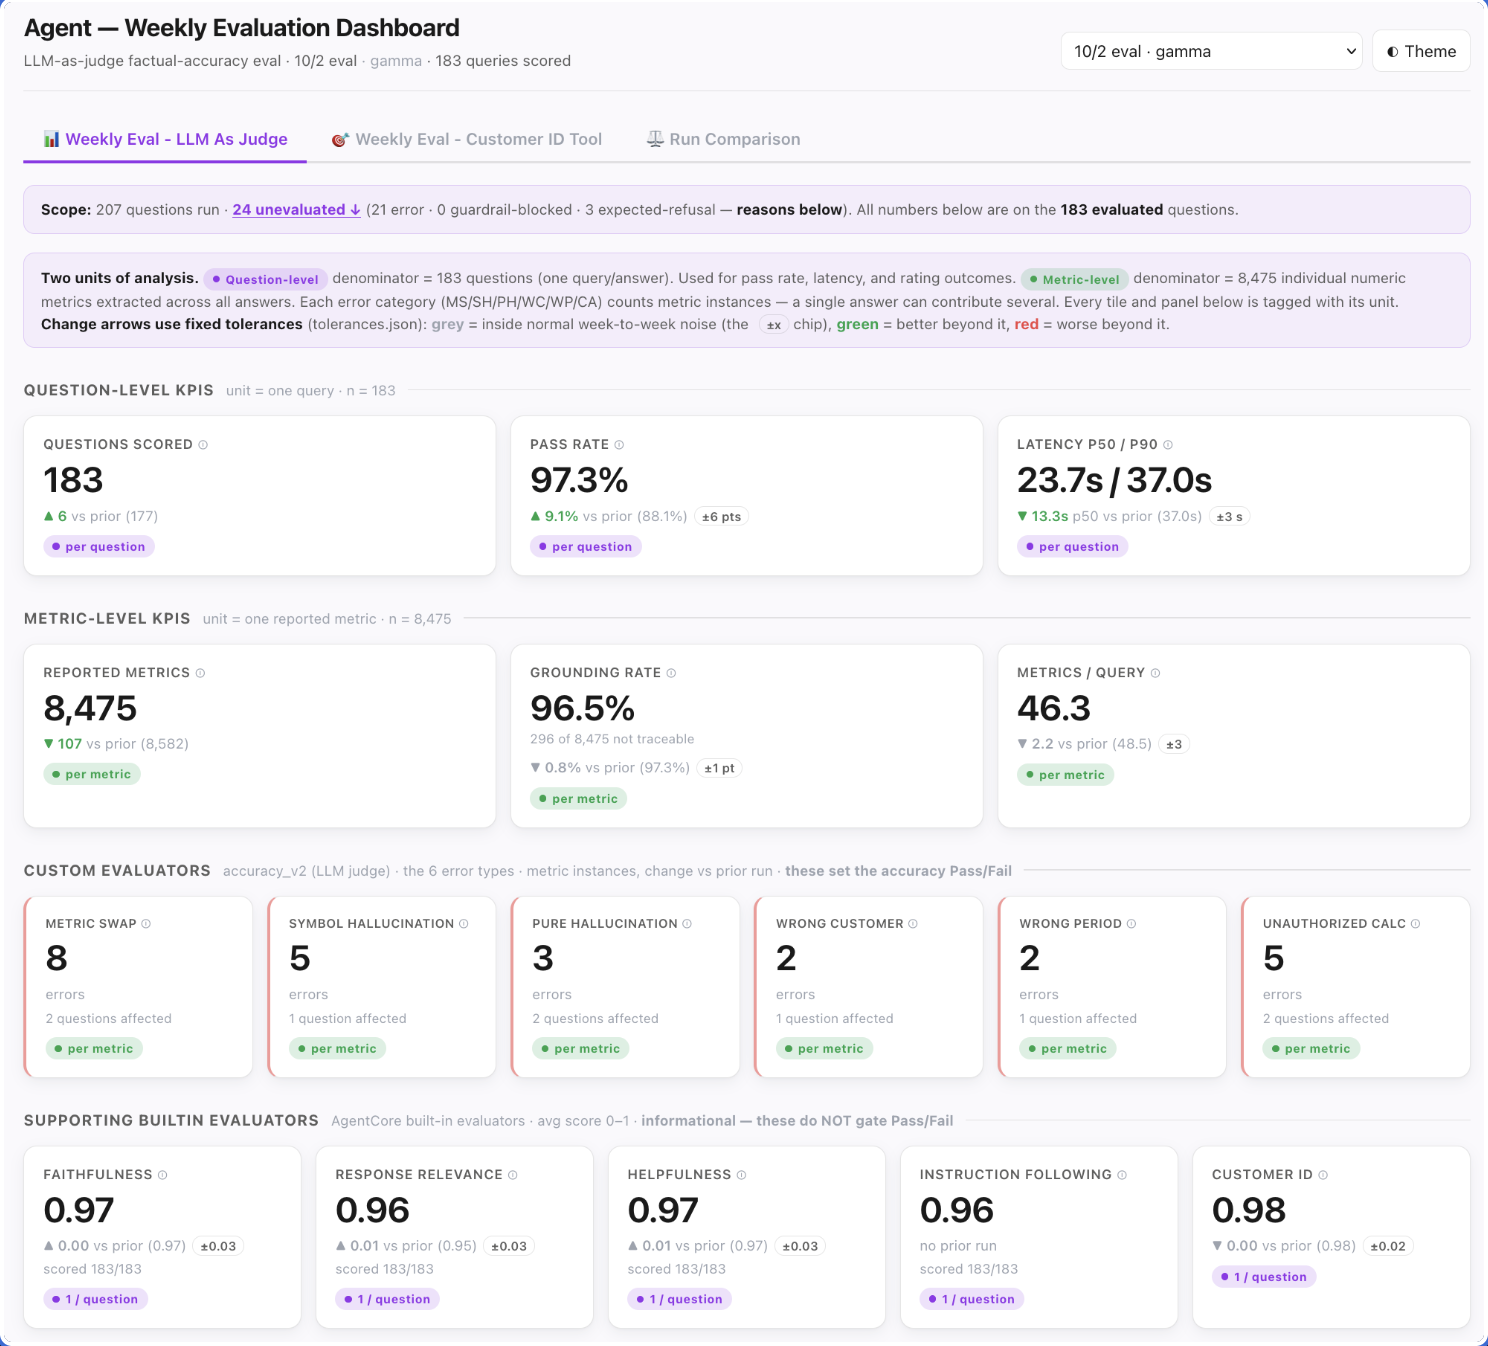
Determine 6: High-line weekly analysis dashboard with mixed move fee and latency. The numbers and values within the determine are illustrative.
Determine 7 drills into that very same run on the custom-evaluator, failure-category stage, breaking down precisely which error varieties (metric swaps, hallucinations, buyer ID misses, and others) are driving the hole and what number of questions every one impacts. The numbers and values within the determine are illustrative.
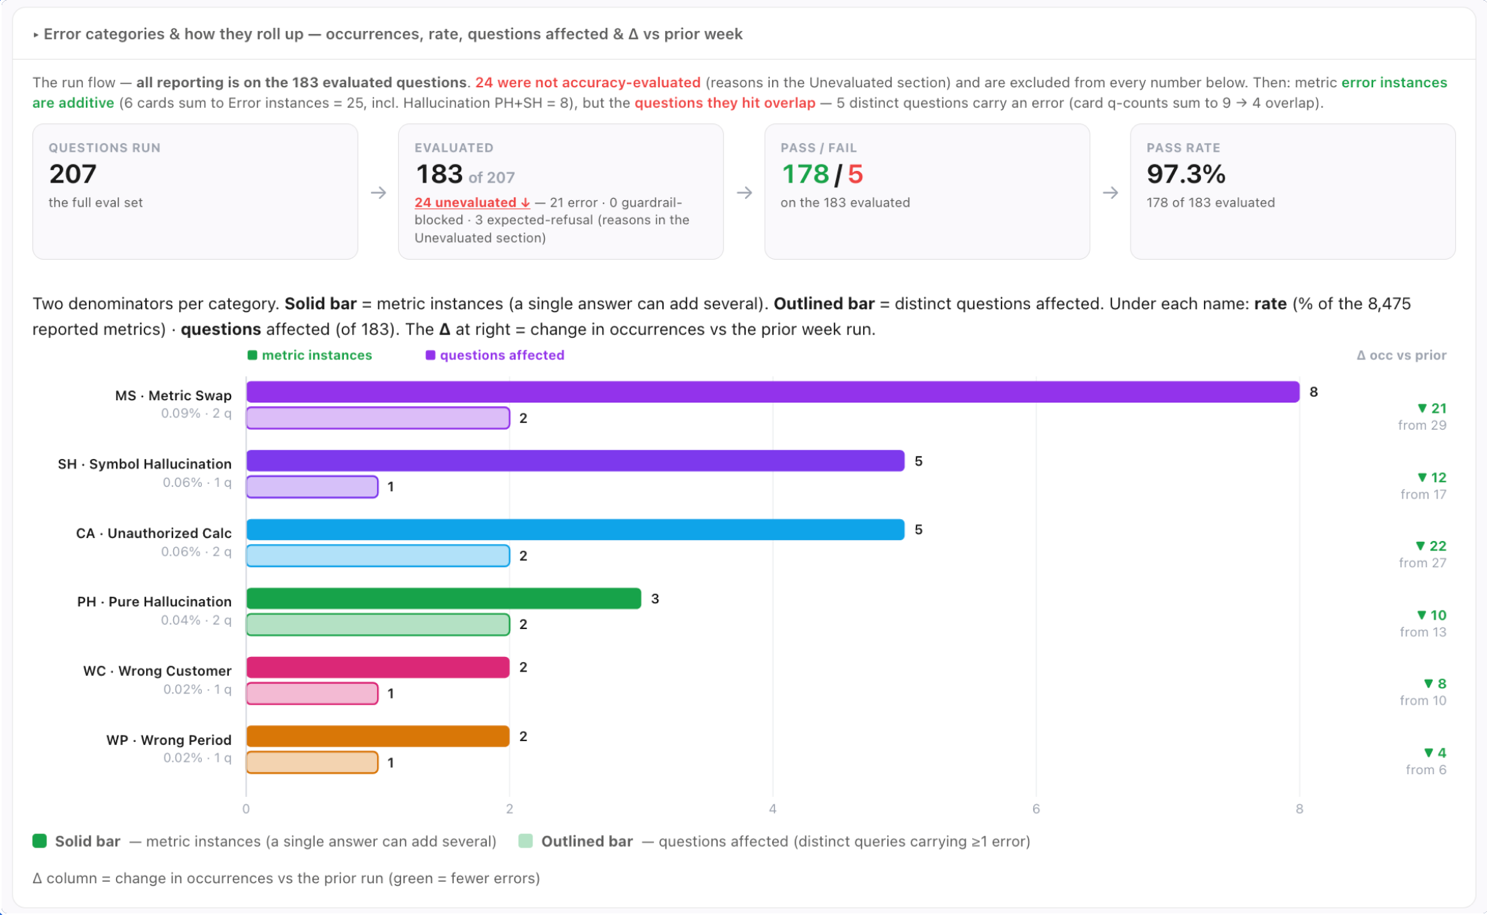
Determine 7: Weekly error-reporting dashboard breaking down failures by class. The numbers and values within the determine are illustrative.
Earlier than Stage 8, imply time to detect (MTTD) was days to weeks. After Stage 8, it’s beneath 4 hours, and the primary sign is a CloudWatch alarm with an AgentCore hint connected.
Stage 9: The Suggestions Loop. Steady enchancment
This stage turns observations into actions. The system compounds high quality over time. We use AgentCore optimization, a functionality of Amazon Bedrock AgentCore, to shut the loop.
- System immediate advice: Analyzes agent traces and generates a knowledge pushed optimized system immediate that improves efficiency on the goal evaluator. The answer makes use of failure patterns and provides particular behavioral directions.
- Software description advice: Analyzes agent traces and generates sharpened software descriptions that scale back software choice confusion. Significantly when an agent selects the incorrect software for ambiguous requests.
Let’s have a look at an instance:
AgentCore optimization in motion
What to enhance on:
Goal evaluator: hallucination: mannequin reproducing hardcoded values from few-shot examples verbatim in unrelated contexts.Why this occurred: Few-shot examples include actual greenback quantities and buyer names (for instance, “$4.2M”, “Acme Corp”) that the mannequin memorizes and leaks into unrelated queries.
How one can repair: Substitute hardcoded values in few-shot examples with generic placeholders (for instance,
$[AMOUNT],[CUSTOMER_NAME]) so the mannequin learns response construction with out memorizing particular knowledge factors.Influence and end result: Repair utilized. Pure hallucination occurrences dropped from 138 to beneath 52 per 10,000 responses, and total grounding fee improved from 93 % to 96 %.
AgentCore optimization makes use of suggestions to supply knowledge pushed system immediate and power descriptions adjustments based mostly on actual agent traces and a goal evaluator. AgentCore optimization builds on AgentCore Evaluations . Low-scoring traces are promoted into the golden set as everlasting regression guards so every failure doesn’t attain customers twice.
Agent analysis key metrics at a look
The analysis metrics are outlined at Stage 1, enforced throughout the 9 levels, and monitored constantly in manufacturing. This set isn’t static. As we be taught from the agent in manufacturing, new failure patterns floor, new dimensions turn out to be measurable, and the metrics evolve accordingly. What follows is the place we began and what we observe at present.
| Degree | Metric | What it measures | Tracked as |
| High quality: Agent | General accuracy move fee | % of responses with zero taxonomy failures | Headline scorecard metric |
| High quality: Agent | Metric swap fee | Right buyer and interval, incorrect metric returned | Occurrences per 100 responses |
| High quality: Agent | Flawed interval fee | Knowledge from the incorrect time window | % citing the proper time window |
| High quality: Agent | Flawed buyer fee | Conflated account names or subsidiaries | Entity decision accuracy % |
| High quality: Agent | Grounding fee | Figures traceable to a retrieved supply | % of reported figures grounded |
| High quality: Agent | Scope adherence fee | Responses that tackle the query requested | % on-topic responses |
| High quality: Agent | Unauthorized calculation fee | Unsanctioned derived figures | Occurrences per 100 responses |
| High quality: Agent | Relevance / Faithfulness / Helpfulness | Response high quality throughout AgentCore built-in dimensions | AgentCore built-in evaluator rating (0–1) |
| High quality: Software | Buyer identification accuracy | Software resolves to the precise canonical entity | % appropriate resolutions (deterministic) |
| High quality: Software | Software choice accuracy | Agent selects the proper software for the question | AgentCore built-in evaluator rating (0–1) |
| High quality: Software | Retrieval precision | Retrieved context incorporates the knowledge wanted | % retrievals with related context |
| High quality: Software | SQL era accuracy | Knowledge Insights Agent generates appropriate SQL | % appropriate end result units (deterministic) |
| High quality: Software | Software move fee | % of software calls returning a legitimate response | % success per software |
| High quality: Multi-agent | Finish-to-end accuracy move fee | Full orchestration path produces an accurate response | % of situations passing all evaluators |
| High quality: Multi-agent | Routing accuracy | Orchestrator routes to the proper sub-agent(s) | % appropriate routing (deterministic) |
| High quality: Multi-agent | Synthesis faithfulness | Sub-agent outputs mixed with out distortion | LLM-as-judge rating throughout agent boundaries |
| High quality: Multi-agent | Context propagation accuracy | Context handed between brokers is appropriate and full | % traces with no context loss |
| Security | Guardrail block fee | % of requests blocked at enter or output | Per 1,000 requests |
| Security | Enter / Output violation fee | % of queries or responses flagged as policy-violating | % of complete requests / responses |
| Security | Guardrail latency | Latency overhead added by guardrail checks | p99 (goal: beneath 50ms) |
| Efficiency | Finish-to-end latency | Question acquired to response delivered | p50, p90, p99 |
| Efficiency | Per sub-agent / software latency | Per sub-agent and per software execution | p50, p90, p99 independently |
| Efficiency | Latency regression fee | CI runs that breach the Stage 1 latency threshold | % of CI runs |
| Price | Price per question | Whole token value per end-to-end consumer request | Enter + output tokens × worth |
| Price | Price per profitable response | Price per question divided by move fee | Penalizes pricey failures |
| Price | Avg software calls per question | Reasoning effectivity. Rising calls sign degradation | Common per question |
| Ops management | MTTD / MTTR | Time to detect and remediate, per failure class | Hours (MTTD goal: beneath 4h) |
| Ops management | Automation detection fee | Incidents detected by analysis in comparison with consumer complaints | % (goal: above 95%) |
| Ops management | Alarm false optimistic fee | Alarms not akin to actual degradation | % of complete alarms |
Conclusion
The influence of the nine-stage agent analysis framework was concrete and measurable. High quality regressions that beforehand took days or even weeks to floor, and normally arrived by way of a vendor criticism, at the moment are caught in beneath 4 hours by automated analysis. Deployment selections that after relied on subjective judgment now require each evaluator to move a quantitative threshold. Immediate iteration cycles fell from days to minutes. Security moved from periodic audits to one hundred pc guardrail protection on each request. Latency regressions are caught on the CI gate earlier than they attain manufacturing. Price surprises that after appeared weeks later in billing at the moment are evaluated at Stage two and enforced by the standard gate earlier than a change ships. And “one thing within the agent pipeline” grew to become one click on from a CloudWatch alarm to a full agent execution hint with each reasoning step seen.
The broader lesson is one the business has discovered earlier than. DevOps taught us that delivery code with out automated testing is reckless. MLOps taught us that deploying fashions with out monitoring is harmful. AgentOps teaches us the identical factor about AI brokers: working them with out steady, multi-level analysis is flying blind.
The nine-stage framework described right here isn’t particular to gross sales intelligence brokers. Crew deploying multi-agent programs that purpose, name sub-agents, instruments, and synthesize responses will face these similar questions throughout the identical lifecycle. Your failure taxonomy will look completely different. Your golden set will replicate your area. Your evaluator stack will probably be tuned to your customers. What stays fixed is the precept: analysis isn’t a remaining QA step. It’s the working system of the agent itself, constantly measured, robotically defended, and improved with each interplay.
If you’re constructing manufacturing brokers and need to deliver this type of analysis self-discipline to your system, Amazon Bedrock AgentCore Evaluations offers you the platform to do it: on-demand analysis for experiments, batch analysis for steady monitoring, on-line analysis for stay visitors, built-in and customised evaluators, dataset analysis(in public preview), CloudWatch integration, and the AgentCore optimization options suggestions and A/B exams to shut the suggestions loop. Begin with Stage one, outline what beauty like on your agent, and let the framework do the remaining.
Prepared to begin? See Consider agent efficiency within the Amazon Bedrock AgentCore documentation. And for those who’re constructing manufacturing brokers and need to discuss by way of tips on how to apply this framework to your system, we’re glad to assist. Attain out to us instantly or by way of your AWS account staff.
To be taught extra about Amazon Bedrock AgentCore Evaluations, see Consider agent efficiency within the AWS documentation. For a technical introduction, learn Construct dependable AI brokers with AgentCore Evaluations. To see how we constructed the Efficiency Insights Agent, learn How AWS SMGS makes use of an AI-powered conversational assistant to remodel enterprise administration with Amazon Bedrock AgentCore. To study AgentCore advice and optimization, learn AgentCore optimization: Enhance agent high quality loop with suggestions and A/B exams
Acknowledgement
We prolong our honest gratitude to our government sponsors and mentors whose imaginative and prescient and steerage made this initiative attainable: Damien Forthomme, Supervisor III, Utilized Science; Akhand Singh, Head of Knowledge Engineering; Sujit Narapareddy, Director AWS Insights; Monica Jain, Sr. Product Supervisor – Tech and Norman Braddock, Senior Supervisor of AI Product Administration at AWS; Muhammad Umar Javed, Utilized Scientist III, L6.
Concerning the authors